CI/CD
Playwright Sharding: Split Your Suite Across CI Machines
Workers, fullyParallel and shards are three different knobs. When to use each, with complete GitHub Actions and GitLab CI configs.
Playwright sharding splits one test suite across several CI machines, so each machine runs a slice and the whole run finishes sooner. It is the right tool when one machine is already busy and the suite is still too slow, not when you have unused cores.
Every command was run with @playwright/test 1.64.1, the latest release as of October 2026, against a local suite of 12 tests in 4 files. The CI configs were replayed locally, and the outputs quoted below come from those runs.
Key takeaways
- Workers are processes on one machine. Shards are separate machines.
fullyParalleldecides whether a file or a single test is the unit that gets handed out. - Raise workers first. Shard when one machine is maxed out and the run is still too slow.
- Turn on
fullyParallelbefore you shard. Without it, whole files move between shards and one shard can end up with nothing to do. - Each shard writes a blob report. A final job merges them into one HTML report.
- Shards share one backend. Shared accounts collide, and
globalSetupruns once per shard.
Workers, fullyParallel and shards: three different knobs
Workers are operating system processes that Playwright starts on one machine. Each worker launches its own browser and runs tests one after another. The workers option defaults to half of the machine's logical CPU cores. You can set a number or a percentage such as '50%'.
fullyParallel changes the unit of work. By default, Playwright hands out whole files: tests inside one file run in order, in one worker. With fullyParallel: true, every test can go to any worker. Sharding splits by that same unit.
Shards are separate playwright test processes, usually on separate CI machines. You pass --shard=2/4 and that machine runs only the second quarter of the suite. Total concurrency is shards times workers per shard.
| Knob | Where it acts | What it controls | Set it with |
|---|---|---|---|
| Workers | One machine | How many tests run at once on that machine | workers in config or --workers |
fullyParallel |
Every machine | Whether a file or a single test is the unit of work | fullyParallel in config or --fully-parallel |
| Shards | Many machines | Which slice of the suite this machine runs | --shard=x/y or shard in config |
When sharding helps, and when more workers is enough
Sharding has a fixed cost per machine. Every shard checks out the repo and installs dependencies and browsers before it runs a single test. Four shards pay that cost, and the bill, four times.
So start with workers. Playwright's own CI guide recommends workers: 1 in CI for stability and reproducibility, and suggests sharding when you need more parallelism. If your runner has more cores and your tests are isolated, try two or more workers before you add machines, and watch for new timeouts: a CPU-starved machine produces flaky tests.
Shard when both of these are true:
- One machine is fully used. Adding workers either does not help or makes tests time out.
- The run is still slower than your team will accept for a pull request.
If the suite is slow because a few tests are slow, sharding will not fix it. A shard can never finish faster than its slowest test or its longest serial group.
Turn on fullyParallel before you shard
Playwright splits the suite by test count, in order. It does not look at how long tests take. Without fullyParallel, a whole file is one unit, and the shard boundaries fall wherever the file boundaries let them.
You can see the split without running anything. --list combined with --shard prints the tests that a shard would run:
npx playwright test --list --shard=2/4Here is what that printed for a 12-test suite in 4 files, once with fullyParallel: false and once with true:
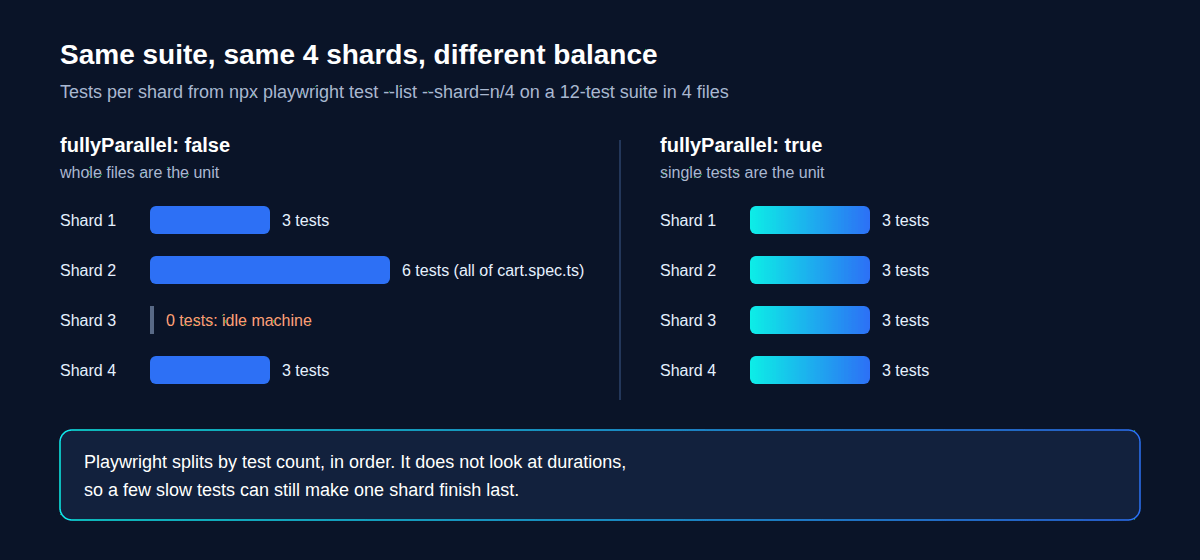
With whole files as the unit, the 6-test cart.spec.ts landed on shard 2 and shard 3 got nothing. That shard still started, ran globalSetup and exited with code 0. You pay for an idle machine while the run waits on the overloaded one.
The config that fixes this, and that the rest of this guide uses:
// playwright.config.ts
import { defineConfig, devices } from '@playwright/test';

export default defineConfig({
  testDir: './tests',
  // Split work test by test, not file by file, so shards stay even.
  fullyParallel: true,
  forbidOnly: !!process.env.CI,
  retries: process.env.CI ? 2 : 0,
  // One machine per shard; start with 1 worker per CI machine, raise it once runs are stable.
  workers: process.env.CI ? 1 : undefined,
  // Each shard writes a blob report in CI; locally you get the usual HTML report.
  reporter: process.env.CI ? 'blob' : 'html',
  globalSetup: './global-setup.ts',
  use: {
    trace: 'on-first-retry',
  },
  projects: [
    { name: 'chromium', use: { ...devices['Desktop Chrome'] } },
  ],
});
GitHub Actions and GitLab CI both set CI=true for every job, so the blob reporter switches on by itself there. The global setup file only logs its shard:
// global-setup.ts
import type { FullConfig } from '@playwright/test';

// Runs once per `playwright test` process, so once on every shard.
export default async function globalSetup(config: FullConfig) {
  const shard = config.shard ? `${config.shard.current}/${config.shard.total}` : 'none';
  console.log(`[global-setup] running on shard ${shard}`);
}
Make every shard write a blob report
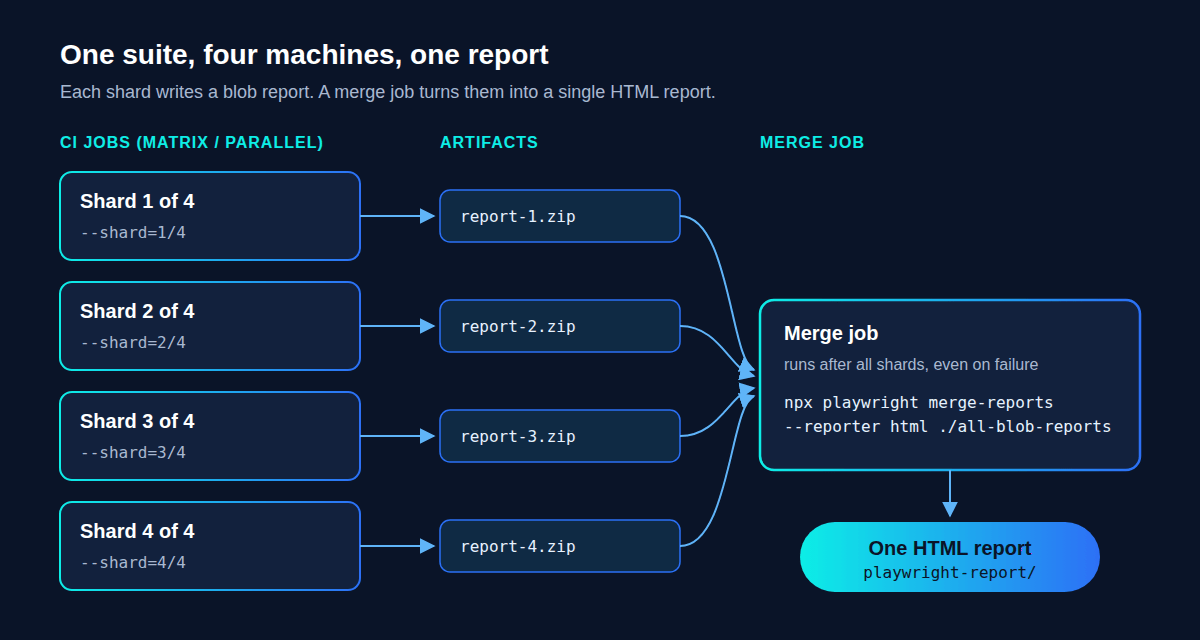
Separate HTML reports per shard leave you with four partial views. The blob reporter instead records everything about the run, including traces and screenshots, into a zip that merge-reports can turn into any other report.
A few details that matter in CI:
- It writes to
blob-report/next to yourpackage.jsonby default. - When you shard, the file name carries the shard number:
report-1.ziptoreport-4.zipin the example run, zero-padded (report-01.zip) once you have 10 or more shards. The files never overwrite each other when you collect them in one folder. - It deletes whatever is already in its output folder before writing. Do not point two shards at the same folder on one machine.
- If your config already lists several reporters, add
'blob'to the array instead of replacing the array. Otherwise you silently drop the others, such as a JUnit file your CI reads.
Merging is one command, run in a folder that contains all the zips:
npx playwright merge-reports --reporter html ./all-blob-reportsThe HTML report lands in playwright-report/; a comma-separated list such as --reporter html,github gives several outputs. For more on the formats, see Playwright reporters.
GitHub Actions: a shard matrix and a merge job
This workflow follows the official sharding example: a matrix of four shards, then a job that downloads every blob report and builds one HTML report.
# .github/workflows/playwright.yml
name: Playwright Tests
on:
  push:
    branches: [main]
  pull_request:

jobs:
  playwright-tests:
    runs-on: ubuntu-latest
    timeout-minutes: 30
    strategy:
      fail-fast: false
      matrix:
        shardIndex: [1, 2, 3, 4]
        shardTotal: [4]
    steps:
      - uses: actions/checkout@v6
      - uses: actions/setup-node@v6
        with:
          node-version: lts/*
      - name: Install dependencies
        run: npm ci
      - name: Install Playwright browsers
        run: npx playwright install --with-deps
      - name: Run Playwright tests
        run: npx playwright test --shard=${{ matrix.shardIndex }}/${{ matrix.shardTotal }}
      - name: Upload blob report
        if: ${{ !cancelled() }}
        uses: actions/upload-artifact@v4
        with:
          name: blob-report-${{ matrix.shardIndex }}
          path: blob-report
          retention-days: 1

  merge-reports:
    # Run even when a shard failed, so you get a report for the failures.
    if: ${{ !cancelled() }}
    needs: [playwright-tests]
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v6
      - uses: actions/setup-node@v6
        with:
          node-version: lts/*
      - name: Install dependencies
        run: npm ci
      - name: Download blob reports
        uses: actions/download-artifact@v5
        with:
          path: all-blob-reports
          pattern: blob-report-*
          merge-multiple: true
      - name: Merge into one HTML report
        run: npx playwright merge-reports --reporter html ./all-blob-reports
      - name: Upload HTML report
        uses: actions/upload-artifact@v4
        with:
          name: html-report--attempt-${{ github.run_attempt }}
          path: playwright-report
          retention-days: 14
The lines that are easy to get wrong:
fail-fast: false. Otherwise one failing shard cancels the other three and throws away their results.if: ${{ !cancelled() }}on the upload step and on the merge job. A failed test fails the shard job, and without this condition the upload and merge are skipped, so you lose the report exactly when you need it.- A unique artifact name per shard.
blob-report-${{ matrix.shardIndex }}keeps the four uploads apart. The download step collects them by pattern, andmerge-multiple: trueputs all zips in one folder. npm ciin the merge job.merge-reportsruns from your installed@playwright/test. The lockfile keeps it on the same version that wrote the blobs.- The attempt number in the HTML artifact name keeps each re-run's report separate.
The whole flow:
GitLab CI: the parallel keyword
The parallel keyword starts several copies of one job, and each copy gets two predefined variables: CI_NODE_INDEX, starting at 1, and CI_NODE_TOTAL. That is exactly the x/y format Playwright expects.
# .gitlab-ci.yml
stages:
  - test
  - report

# Use the image tag that matches @playwright/test in your lockfile.
image: mcr.microsoft.com/playwright:v1.64.1-noble

e2e:
  stage: test
  parallel: 4
  script:
    - npm ci
    - npx playwright test --shard=$CI_NODE_INDEX/$CI_NODE_TOTAL
  artifacts:
    # Keep the blob report from failed shards too.
    when: always
    paths:
      - blob-report/
    expire_in: 1 day

merge-reports:
  stage: report
  # Run after every shard, passed or failed.
  when: always
  # needs on a parallel job waits for all 4 jobs and downloads all 4 artifacts.
  needs: [e2e]
  script:
    - npm ci
    # Each shard's file is named report-<n>.zip (zero-padded from 10 shards), so all four land side by side.
    # merge.config.ts sets testDir, in case runners checked out to different paths.
    - npx playwright merge-reports -c merge.config.ts ./blob-report
  artifacts:
    when: always
    paths:
      - playwright-report/
    expire_in: 2 weeks
And the small merge config it points to:
// merge.config.ts
// Used only by `playwright merge-reports -c merge.config.ts`.
// testDir tells the merge where the tests live, so blobs recorded in
// different checkout paths (or operating systems) can still be merged.
export default {
  testDir: 'tests',
  reporter: [['html', { open: 'never' }]],
};
How the pieces fit:
parallel: 4creates jobs namede2e 1/4toe2e 4/4. GitLab allows values from 1 to 200.- When
needsnames a parallel job, the merge job waits for every copy and downloads all their artifacts into the same paths. The shard-numbered zip names keep them apart inblob-report/. when: alwayson the artifacts keeps the blob report of a failed shard.when: alwayson the merge job lets it run after a failure.- The Docker image already contains the browsers, so there is no
playwright installstep. Its version must match the@playwright/testversion in your lockfile, or Playwright will look for browser builds the image does not have.
Why the merge config is there
In our local replay, each job ran from its own folder, like runners that check out to different paths. The plain merge command refused to run:
Error: Blob reports being merged were recorded with different test directories, and
merging cannot proceed. This may happen if you are merging reports from
machines with different environments, like different operating systems or
if the tests ran with different playwright configs.

You can force merge by specifying a merge config file with "-c" option. If
you'd like all test paths to be correct, make sure 'testDir' in the merge config
file points to the actual tests location.

Found directories:
...
The blobs store absolute test paths, so differing paths break the merge, and the message names the fix itself. With -c merge.config.ts, the same four blobs merged into one report with all 12 tests. GitHub-hosted Linux runners share one checkout path, so the GitHub workflow needs this only if you mix runner types or operating systems.
For a fuller GitLab setup, with caching and merge request reports, see Playwright in GitLab CI.
Balancing shards: pick a count from your own timings
Other teams' speed-ups tell you little about your suite. Your own timings do.
Step 1: get test time per file. After any sharded run, merge the blobs into JSON instead of HTML:
PLAYWRIGHT_JSON_OUTPUT_NAME=timings.json npx playwright merge-reports --reporter json ./all-blob-reportsStep 2: see where the time goes. This script reads that JSON, prints time per file, and estimates the slowest shard for 1 to 8 shards. It copies how Playwright splits: one list of every test, project by project in config order, then file by file, cut into slices of equal test count, durations ignored. A shard count as the second argument also prints each shard's tests, to check against --list.
// scripts/shard-timings.mjs
// Usage: [SETUP_PROJECTS=setup] node scripts/shard-timings.mjs timings.json [shardCount]
// With a shard count, it also lists the tests each shard gets, to compare with --list.
import { readFileSync } from 'node:fs';

const [, , reportPath, listFor] = process.argv;
const report = JSON.parse(readFileSync(reportPath, 'utf8'));

// Setup and teardown projects run in full on every shard that needs them, so
// they are not split. The JSON report does not mark them: name them in
// SETUP_PROJECTS (comma-separated). Every other project is split in config order.
const setup = new Set((process.env.SETUP_PROJECTS ?? '').split(',').filter(Boolean));
const projectOrder = report.config.projects.map((p) => p.name).filter((name) => !setup.has(name));

// Flatten every test with its project, position and total time
// (all attempts, because retries cost CI time too).
const tests = [];
function walk(suite) {
  for (const spec of suite.specs ?? []) {
    for (const t of spec.tests) {
      tests.push({
        project: t.projectName,
        file: spec.file,
        line: spec.line,
        column: spec.column,
        where: `[${t.projectName}] ${spec.file}:${spec.line}`,
        title: spec.title,
        // Skipped at declaration: never handed to a worker (workerIndex -1).
        // A test.skip() inside the test body ran in a worker, so it still counts.
        skipped: t.expectedStatus === 'skipped' && t.results.every((r) => r.workerIndex === -1),
        ms: t.results.reduce((sum, r) => sum + r.duration, 0),
      });
    }
  }
  for (const child of suite.suites ?? []) walk(child);
}
report.suites.forEach((fileSuite) => walk(fileSuite));

// Playwright reads test folders in name order, so compare paths folder by folder.
function byPath(a, b) {
  const x = a.split('/');
  const y = b.split('/');
  for (let i = 0; i < Math.min(x.length, y.length); i++) {
    const c = x[i].localeCompare(y[i]);
    if (c) return c;
  }
  return x.length - y.length;
}

// Playwright's order: project by project, then file by file, then as declared.
const ordered = tests
  .filter((t) => projectOrder.includes(t.project))
  .sort((a, b) =>
    projectOrder.indexOf(a.project) - projectOrder.indexOf(b.project) ||
    byPath(a.file, b.file) || a.line - b.line || a.column - b.column);
if (ordered.length === 0) {
  console.error('No tests found.');
  process.exit(1);
}
// Recent Playwright versions leave tests skipped at declaration out of the
// count, unless every test is skipped.
const active = ordered.filter((t) => !t.skipped);
const shardable = active.length ? active : ordered;

const total = ordered.reduce((s, t) => s + t.ms, 0);
const byFile = new Map();
for (const t of ordered) {
  const key = t.where.replace(/:\d+$/, '');
  byFile.set(key, (byFile.get(key) ?? 0) + t.ms);
}
console.log(`${ordered.length} tests (${shardable.length} counted for sharding), ${(total / 1000).toFixed(1)} s of test time\n`);
console.log('Time per file (slowest first):');
for (const [file, ms] of [...byFile].sort((a, b) => b[1] - a[1])) {
  console.log(`  ${(ms / 1000).toFixed(1).padStart(7)} s  ${file}`);
}
const slowest = ordered.reduce((a, b) => (b.ms > a.ms ? b : a));
console.log(`\nSlowest single test: ${(slowest.ms / 1000).toFixed(1)} s (${slowest.title})`);

// Equal test counts per shard, earlier shards take the remainder, durations
// ignored. This splits test by test; serial groups and files with beforeAll
// hooks really move as blocks, so a boundary can be off by one block.
function split(n) {
  const shards = [];
  let from = 0;
  for (let i = 0; i < n; i++) {
    const to = from + Math.floor(shardable.length / n) + (i < shardable.length % n ? 1 : 0);
    shards.push(shardable.slice(from, to));
    from = to;
  }
  return shards;
}
const seconds = (list) => (list.reduce((s, t) => s + t.ms, 0) / 1000).toFixed(1);

console.log('\nShards  slowest shard (test time, 1 worker each)');
for (let n = 1; n <= 8; n++) {
  const worst = Math.max(...split(n).map((s) => Number(seconds(s))));
  console.log(`  ${String(n).padStart(2)}    ${worst.toFixed(1).padStart(7)} s`);
}

if (listFor) {
  split(Number(listFor)).forEach((shard, i) => {
    console.log(`\nShard ${i + 1}/${listFor}: ${shard.length} tests, ${seconds(shard)} s`);
    for (const t of shard) console.log(`  ${t.where} › ${t.title}`);
  });
}
Treat the output as an estimate. On a two-project run of the example suite, its lists matched --list exactly for 2 and 3 shards. Where it drifts:
- Blocks. A serial group moves as one block, and a fully parallel file with
beforeAllorafterAllhooks moves in a few chunks. Each block lands on the shard where its first test falls, so a boundary can be off by one block. - Worker settings. Playwright groups a project's files by worker-level settings first.
profile.spec.ts, the only file with a worker fixture, was queued aftersearch.spec.tsalthough its name sorts first, so the 5-shard estimate was off by one test. - Setup projects. Projects named in
dependenciesrun in full on every shard that needs them. The JSON does not mark them, so list them inSETUP_PROJECTS. - Skipped tests. In 1.64.1, tests skipped at declaration (
test.skip(),test.fixme()) do not count toward the split unless every test is skipped, and the script does the same. Version 1.61.1 still counted them.
Step 3: add the fixed cost. In one shard job, read how long checkout, install and browser setup took: that is your setup time. The wall-clock time of a sharded run is roughly the setup time plus the slowest shard. Your bill is roughly the number of shards multiplied by the setup time, plus the total test time.
Step 4: stop where the curve flattens. Pick the smallest shard count that meets your target. Once the slowest shard is close to your slowest test, or to your longest serial group, more shards only add setup cost.
If the estimate shows one shard far behind the others, the usual causes are:
- Slow tests that sit next to each other. Shards take contiguous runs of tests, so a cluster of slow tests in one file, or in files with neighbouring names, lands on one shard. Splitting that file spreads them out.
fullyParallelturned off for a project, which brings back file-level splitting for that project, or a describe block set tomode: 'default', which makes the whole block one unit.
Playwright sharding and test isolation
Shards run at once, on different machines, against the same staging environment, so whatever made tests fragile under several workers gets worse.
Per-worker accounts stop being unique. A common pattern gives each worker its own test user, keyed by parallelIndex. Every shard has its own worker 0, so two shards running at once both log in as the same user. Add the shard number to the key:
// tests/account-fixture.ts
import { test as base } from '@playwright/test';

type Worker = { accountName: string };

// One test account per worker *and* per shard. parallelIndex alone is not
// enough: every shard has its own worker 0, so two shards running at the same
// time would share "qa-user-0".
export const test = base.extend<{}, Worker>({
  accountName: [async ({}, use, workerInfo) => {
    const shard = workerInfo.config.shard?.current ?? 0;
    await use(`qa-user-s${shard}-w${workerInfo.parallelIndex}`);
  }, { scope: 'worker' }],
});

export { expect } from '@playwright/test';
On shard 2 of 2 this produced names like qa-user-s2-w0; the worker number depends on which worker picks up the test. Locally, without --shard, the prefix is s0. For creating those users, see Playwright test data.
globalSetup runs on every shard. Each shard is a full playwright test process, so it runs global setup itself. In the example run, the log showed [global-setup] running on shard 1/4 through 4/4. Setup projects behave the same way: every shard ran the whole setup project. If your global setup resets a database or seeds shared records, four shards will do it four times, possibly while another shard is mid-test. Move one-time, destructive work into its own CI job that runs before the shards, and keep globalSetup to work that is safe to repeat, such as logging in and saving storage state.
Serial groups stay together, but nothing stops a test on another shard from changing the same record. The fix is the same as for workers: unique data per test.
Retries stay on their shard. Retries run inside the same shard, so a flaky test can make its shard the slow one. Playwright retries covers how to read retry results without letting them hide bugs.
Reading the merged report
A few things to know about the merged report:
- The status is the worst of all shards. If any shard failed, the merged run is failed.
- The run duration runs from the earliest shard's start to the latest shard's end. It counts Playwright time only, not checkout or install, and it is not the sum of shard times.
- Traces and screenshots come along. The blob holds the attachments, so a failure from shard 3 opens its trace from the merged report like any other. See Playwright Trace Viewer for reading them.
- Same tests in several environments? Set
tagin the config so the merged report shows where each result came from. Each tag must start with@, sotag: process.env.CI_ENVIRONMENT_NAMEneeds a value such as@staging.
Where Blendra fits
If you build your suite with Blendra, the export is a normal Playwright project. It already sets fullyParallel: true and one worker in CI. It includes a GitHub Actions workflow that runs the suite in a single job, and a reporter that sends CI results to Blendra (it needs BLENDRA_API_TOKEN, on Pro and above). With the reporter on, a passed run fails if Blendra cannot confirm it received the results.
The Blendra reporter doesn't support sharded runs yet. In a GitHub Actions matrix every shard reports under the same run, and every shard but the first to report fails. Keep the exported workflow in one job, or remove the reporter line from sharded jobs.
See GitHub Actions, the generated project structure and the reporter. Runs in your own CI never use Blendra's cloud runner minutes, whatever your plan.
FAQ
How many shards should I use?
The smallest number that brings the run under your target time. The balancing section shows how to measure it.
Does globalSetup run on every shard?
Yes, and global teardown too. Keep both safe to repeat, as explained under test isolation.
Can I shard by project, for example per browser?
You can combine --project and --shard. GitLab's parallel:matrix can run each project and shard pair as its own job, as the Playwright CI docs show. Without --project, Playwright joins every project's tests into one list and cuts it into equal slices. A shard may get only one project, and one file can land on different shards for different projects.
Why is one shard always slower than the others?
Playwright balances shards by test count, not duration, so clustered slow tests, serial groups and retries pile up on one shard. Run the timings script to find which, then split the file or fix the flake.