Locators and selectors
Playwright Locators: A Ranked Guide to Selectors That Survive Redesigns
A ranked guide to Playwright locators, with the way each one breaks and how to narrow a locator that matches too much.
Playwright locators decide whether your tests survive the next redesign. Pick them well and a CSS rewrite or a moved button costs you nothing, and a new component library costs you very little. Pick them badly and every sprint starts with a red pipeline. This guide ranks every locator type, shows the change that usually breaks each one, and fixes the error you hit most often: a locator that matches more than one element.
Every example runs against one small page that the tests load with page.setContent. The next sections show that page in full as tests/fixture.ts, so you can paste it and any test below into a fresh project and run npx playwright test. Every snippet was run on Playwright 1.61.
TL;DR
- Use
getByRolewith anamefirst. ThengetByLabel,getByPlaceholderandgetByText. - Use
getByTestIdwhen the role or the visible name is unstable: translated UIs, icon-only buttons, copy that changes weekly. - Use CSS and XPath last. They read the implementation, not what the user sees.
- Every locator should match exactly one element. When it matches more, narrow it with
filter()or by chaining inside a row or region. Don't reach for.first().
How Playwright locators work
A locator is a description of how to find an element, not the element itself. Three properties follow from that.
Lazy. page.getByRole('button', { name: 'Save' }) does nothing on its own. Playwright looks for the element only when you act on it or assert on it.
Re-resolved. The Playwright locators guide explains that Playwright looks up a fresh DOM element every time you use a locator for an action. If React re-renders the button between two clicks, the second click finds the new button. With locators you don't get the stale-element errors Selenium users know. Element handles (page.$()) can still go stale, which is one reason to avoid them.
Strict. An action such as click() or fill() needs exactly one match. If the locator matches two elements, Playwright throws instead of guessing. Methods that are about a set, such as count(), all() and toHaveCount(), accept many matches.
Before each action, Playwright also waits for the element to pass actionability checks, such as being visible, stable, enabled and able to receive events. That is a separate topic, covered in Playwright auto-waiting.
One more default trips people up. Text matching in getByText, and name matching in getByRole, is case-insensitive and matches a substring. { exact: true } makes it case-sensitive and whole-string. Whitespace is still normalized, even with an exact match: runs of spaces and line breaks collapse to one space, and leading and trailing spaces are ignored.
The page used in this guide
Here is the whole shared page, tests/fixture.ts: a sign-up form, an invoice table with three Edit buttons, a team list, an icon-only Close button and a Bold toggle button that flips aria-pressed when clicked.
// tests/fixture.ts
// One shared DOM for every example in the post. Tests load it with page.setContent,
// so nothing needs a server and nothing touches the network.
export const signupAndInvoices = `
<main>
<h1>Create account</h1>
<form aria-label="Sign up">
<label for="email">Work email</label>
<input id="email" name="email" type="email"
placeholder="you@company.com" data-testid="signup-email">
<label><input type="checkbox" name="terms"> I accept the terms</label>
<button type="submit">Create account</button>
</form>
<section aria-labelledby="invoices-title">
<h2 id="invoices-title">Invoices</h2>
<table>
<thead>
<tr><th>Invoice</th><th>Customer</th><th>Status</th><th>Actions</th></tr>
</thead>
<tbody>
<tr>
<td>Invoice 41</td><td>Acme Ltd</td><td>Paid</td>
<td><button>Edit</button></td>
</tr>
<tr>
<td>Invoice 42</td><td>Globex</td><td>Overdue</td>
<td><button>Edit</button></td>
</tr>
<tr>
<td>Invoice 43</td><td>Initech</td><td>Paid</td>
<td><button>Edit</button></td>
</tr>
</tbody>
</table>
</section>
<ul aria-label="Team members">
<li>Ana Silva <span>Admin</span> <button>Remove</button></li>
<li>Ben Okafor <span>Editor</span> <button>Remove</button></li>
</ul>
<button aria-label="Close banner" data-testid="close-banner">×</button>
<button aria-pressed="false" onclick="this.setAttribute('aria-pressed', String(this.getAttribute('aria-pressed') !== 'true'))">Bold</button>
</main>
`;Each spec file imports it and loads it before every test. Every snippet below that isn't a whole file (the ones marked "excerpt" and the short fragments in the strict mode section) runs inside a spec that starts like this:
import { test, expect } from '@playwright/test';
import { signupAndInvoices } from './fixture';

test.beforeEach(async ({ page }) => {
  await page.setContent(signupAndInvoices);
});
Playwright locators ranked, with how each one breaks
The ranking puts what a locator proves first and how often it breaks second. A locator that reads what the user sees fails when the user would notice a change. That failure is worth reading. A locator that reads class names fails when nobody would notice anything.
| Rank | Locator | Best for | Usually breaks when |
|---|---|---|---|
| 1 | getByRole(role, { name }) |
Buttons, links, inputs, headings, rows, dialogs | The visible or accessible name is reworded or translated |
| 2 | getByLabel(text) |
Form fields with a <label>, aria-labelledby or aria-label |
The label is reworded or loses its for link |
| 3 | getByPlaceholder(text) |
Inputs that have no label (fix that too) | The placeholder is rewritten or removed |
| 4 | getByText(text) |
Non-interactive text: messages, empty states | Copy edits; the same text appears twice |
| 5 | getByAltText / getByTitle |
Images; elements with a title tooltip |
Alt or tooltip text is edited |
| 6 | getByTestId(id) |
Translated UIs, icon-only buttons, CMS copy | A refactor drops the attribute |
| 7 | locator('css') |
Third-party widgets with no roles or ids | Classes, nesting or styling change |
| 8 | locator('xpath=...') |
Almost nothing; legacy suites | Any change in nesting; can't see inside shadow DOM |
The Playwright docs list getByText second, right after getByRole. This guide moves it below label and placeholder for anything you interact with, because the same text often appears twice on a page (see the Create account example below).
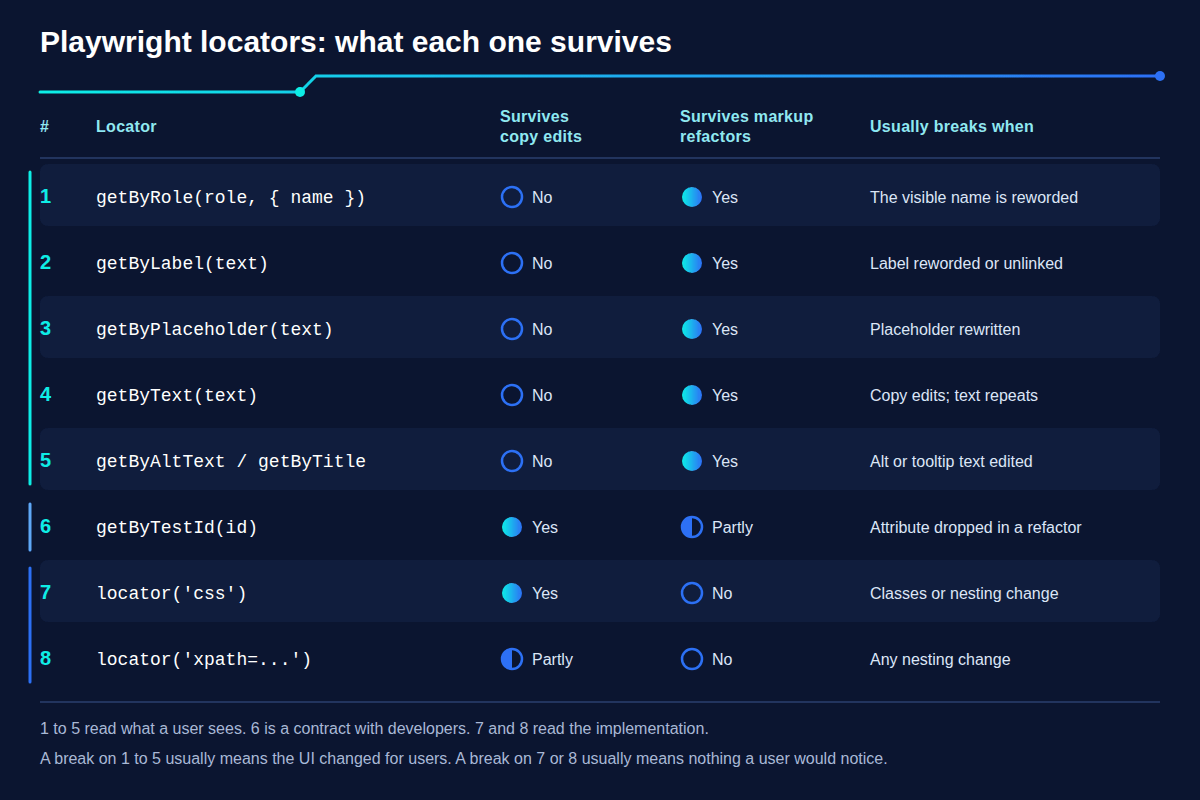
Test ids sit at rank 6 even though they survive copy changes best. The Playwright docs say so plainly: test ids are the most resilient option, but they are not user facing. A test that clicks getByTestId('submit') still passes when the button's text says "Lorem ipsum". A role locator would catch that.
Here is the same input found six ways. Every locator resolves to the one <input>, so every one sees the value that the first one typed.
// tests/same-element.spec.ts
import { test, expect } from '@playwright/test';
import { signupAndInvoices } from './fixture';

test('one input, found six ways', async ({ page }) => {
  await page.setContent(signupAndInvoices);

  const byRole = page.getByRole('textbox', { name: 'Work email' });
  const byLabel = page.getByLabel('Work email');
  const byPlaceholder = page.getByPlaceholder('you@company.com');
  const byTestId = page.getByTestId('signup-email');
  const byCss = page.locator('#email');
  const byXPath = page.locator('xpath=//input[@name="email"]');

  await byRole.fill('ana@example.com');

  for (const locator of [byRole, byLabel, byPlaceholder, byTestId, byCss, byXPath]) {
    await expect(locator).toHaveCount(1);
    await expect(locator).toHaveValue('ana@example.com');
  }
});
They all pass today. The difference shows up later. Rename the id and the CSS locator breaks. Wrap the input in another <div> and an absolute XPath breaks. Change "Work email" to "Email" and the role and label locators break, which is fair, because users see that change.
getByRole done right
getByRole reads the accessibility tree: the roles and names that a screen reader announces. Most HTML elements have an implicit role. A <button> is a button, an <a href> is a link, an <input type="email"> is a textbox, a <section> with an accessible name is a region. You rarely need a role attribute.
Always pass a name. getByRole('button') matches every button on the page. The name comes from the element's text, its aria-label, its aria-labelledby target or, for inputs, its <label>.
Know the matching rules. By default the name is a case-insensitive substring. That is handy and occasionally surprising:
// tests/role-options.spec.ts (excerpt)
test('name matching is a case-insensitive substring unless exact is set', async ({ page }) => {
  await expect(page.getByRole('button', { name: 'create' })).toHaveCount(1);
  await expect(page.getByRole('button', { name: 'create', exact: true })).toHaveCount(0);
  await expect(page.getByRole('button', { name: 'Create account', exact: true })).toHaveCount(1);
});
Use a regular expression when part of the name changes: { name: /Invoice 42/ } or { name: /^Order #\d+$/ }.
Use the state options instead of attribute selectors. getByRole takes checked, pressed, expanded, selected, disabled, level and includeHidden. They read the ARIA state, so they work for native checkboxes and for custom toggles alike.
// tests/role-options.spec.ts (excerpt)
test('state options: checked and pressed', async ({ page }) => {
  await page.getByRole('checkbox', { name: 'I accept the terms' }).check();
  await expect(page.getByRole('checkbox', { name: 'I accept the terms', checked: true })).toHaveCount(1);

  await page.getByRole('button', { name: 'Bold' }).click();
  await expect(page.getByRole('button', { name: 'Bold', pressed: true })).toBeVisible();
});

test('headings by level', async ({ page }) => {
  await expect(page.getByRole('heading', { level: 2 })).toHaveText('Invoices');
});
Prefer getByRole over getByText for anything you click. On the sample page, "Create account" is both the <h1> and the submit button. getByText('Create account') matches both. Role plus name picks one of each:
// tests/same-element.spec.ts (excerpt)
await expect(page.getByText('Create account')).toHaveCount(2);
await expect(page.getByRole('heading', { name: 'Create account', level: 1 })).toBeVisible();
await expect(page.getByRole('button', { name: 'Create account' })).toBeEnabled();
Find the role and name quickly. Run npx playwright test --ui or npx playwright codegen <url> and use Pick locator: hover an element and Playwright shows the locator it would use. Chrome DevTools also has an Accessibility pane that shows the computed role and name. A role locator is not an accessibility audit, as the docs point out, but a control with no name is a bug for screen-reader users too. Fix it in the app, not in the test.
When a test id beats a role
Role first is a default, not a law. Switch to getByTestId when:
- The UI is translated. "Save" becomes "Speichern", and a role locator needs a name per locale. If you test one locale, set
localein the config and keep role locators. If you run every locale, test ids save you a lookup table. - The control has no stable name. An icon-only button with
aria-label="Close banner"works withgetByRole. Without anaria-label, add one; if you can't, add a test id. - The copy changes weekly. Marketing pages and CMS-driven labels change without a code change. A test id keeps that churn out of your suite.
- No text tells repeated controls apart, and their container has no text either. (When the container has text, scope to it instead. See the next section.)
getByTestId matches the data-testid attribute exactly. If your team uses another attribute, change it once in the config:
// playwright.config.ts
import { defineConfig, devices } from '@playwright/test';

export default defineConfig({
  use: {
    ...devices['Desktop Chrome'],
    testIdAttribute: 'data-test',
  },
});
With that setting, getByTestId('save-draft') finds data-test="save-draft", and data-testid is no longer read at all. Test ids only work with developer buy-in: an agreed naming scheme and a rule that nobody deletes one without updating the tests. data-testid best practices covers naming, ownership and whether to strip them from production builds.
When a locator matches more than one element: the strict mode violation
This is the error you see most often. The invoice table has three Edit buttons:
await page.getByRole('button', { name: 'Edit' }).click();Error: locator.click: Error: strict mode violation: getByRole('button', { name: 'Edit' }) resolved to 3 elements:
1) <button>Edit</button> aka getByRole('row', { name: 'Invoice 41 Acme Ltd Paid Edit' }).getByRole('button')
2) <button>Edit</button> aka getByRole('row', { name: 'Invoice 42 Globex Overdue Edit' }).getByRole('button')
3) <button>Edit</button> aka getByRole('row', { name: 'Invoice 43 Initech Paid Edit' }).getByRole('button')Read the aka lines. Playwright already suggests the fix: scope the button to its row. The error is a feature. Without strictness, the click would go to the first Edit button and the test could pass while editing the wrong invoice.
Assertions are strict too. expect(edit).toBeVisible() on those three buttons fails with the same strict mode violation. toHaveCount(3) is fine, because it is about the whole set.
Here are four ways to narrow it. Each one runs against the same sample page.
1. Filter the rows by text, then find the button.
const edit = page
  .getByRole('row')
  .filter({ hasText: 'Invoice 42' })
  .getByRole('button', { name: 'Edit' });

await expect(edit).toHaveCount(1);
await edit.click();
2. Find the row by its accessible name, then chain. A row's name is its cells' text joined together, which is what the error message printed.
const row = page.getByRole('row', { name: /Invoice 42/ });
await row.getByRole('button', { name: 'Edit' }).click();
3. Filter by a child locator with has. The inner locator is searched inside each row, not across the page.
const overdueRows = page
  .getByRole('row')
  .filter({ has: page.getByRole('cell', { name: 'Overdue', exact: true }) });

await expect(overdueRows).toHaveCount(1);
await expect(overdueRows).toContainText('Invoice 42');
4. Scope to a region first. Name your landmarks (<section aria-labelledby>, <nav aria-label>, dialogs with a title), then search inside them.
const invoices = page.getByRole('region', { name: 'Invoices' });
await expect(invoices.getByRole('button', { name: 'Edit' })).toHaveCount(3);
filter() also takes hasNot, hasNotText and visible, and filters stack: on the sample table, page.getByRole('row').filter({ hasText: 'Paid' }).filter({ hasNotText: 'Acme' }) leaves one row, Invoice 43.
Watch the substring rule here. hasText is a case-insensitive substring, so "Invoice 4" matches rows 41, 42 and 43, and "Invoice 42" will match "Invoice 420" the day it exists. When the value must match a whole cell, filter with has and an exact cell:
const row = page
  .getByRole('row')
  .filter({ has: page.getByRole('cell', { name: 'Invoice 42', exact: true }) });
await expect(row).toHaveCount(1);
Lists and tables
The pattern is always the same. Find the row or item by the text that identifies it, then find the cell or button inside it.
// tests/tables-and-lists.spec.ts (excerpt)
test('read one cell of the row you care about', async ({ page }) => {
  const row = page.getByRole('row', { name: /Invoice 42/ });

  // nth() is fine here: the column order is part of the table's contract.
  const status = row.getByRole('cell').nth(2);
  await expect(status).toHaveText('Overdue');
});

test('remove one team member from a list', async ({ page }) => {
  const ben = page.getByRole('listitem').filter({ hasText: 'Ben Okafor' });

  await expect(ben).toContainText('Editor');
  await expect(ben.getByRole('button', { name: 'Remove' })).toHaveCount(1);
});
nth() is acceptable when the position is the thing you mean: the third column of a table whose columns don't move, the first result after you sort by date, the last toast in a stack. It is a smell when it means "the one I happened to want when I wrote this". The Playwright docs warn about exactly that: after a page change, nth(), first() and last() can quietly point at a different element. If you use nth() on a table, add a comment that says why.
hasNot and hasNotText help with "everything except" questions. On the sample table, page.getByRole('row').filter({ hasNot: page.getByRole('button') }) is the header row, and filter({ hasNotText: 'Paid' }) is the header plus Invoice 42.
Attributes to avoid
These look stable on the day you write them and break for reasons no user would notice.
- Generated class names. CSS Modules, CSS-in-JS and build tools produce classes like
.Button_root__x7f2aor.css-1q2w3e. They change when someone edits a style or bumps a dependency. - Utility classes.
.bg-blue-600.px-4describes how a button looks. A design change rewrites it. - Auto-generated ids. React's
useId, component libraries and form builders generate ids such as:r5:(React 18) ormat-input-3(Angular Material). They change with render order. - Absolute XPath.
/html/body/div[2]/div/form/div[3]/buttonbreaks when anyone adds a wrapper. Parent steps such asxpath=..break the same way;filter({ has })does that job without depending on nesting. nth()as a habit. See above. One more row, one reordered list, and the test acts on the wrong element.- Layout selectors such as
:right-of(). The other locators page marks them deprecated.
If you must use CSS, use attributes with meaning: [name="email"], [type="submit"], [href="/pricing"]. They change for functional reasons, not for styling.
iframes and shadow DOM
iframes. An iframe is a separate document, so page-level locators don't look inside it. Enter it first with page.frameLocator('iframe[title="Payment"]') (or page.locator('iframe[title="Payment"]').contentFrame()), then use the same locators as anywhere else: .getByLabel('Card number').fill(...). Card fields from payment providers sit in cross-origin iframes, often nested. Playwright iframes covers those cases.
Shadow DOM. Playwright locators pierce open shadow roots by default, so getByRole, getByTestId and CSS find a button inside a web component with no extra syntax. Two exceptions: XPath does not pierce shadow roots, and closed shadow roots are not supported. On a page with a <promo-card> web component, getByRole('button', { name: 'Claim offer' }) finds the button inside its open shadow root, while locator('xpath=//button') matches nothing.
A locator review checklist for pull requests
Paste this into your PR template, or use it when you review a test.
- Every interactive element is found by role and name, label or test id, not by class or position.
- Every
getByRolecall passes aname. - No generated classes, auto ids or absolute XPath.
- Repeated controls are scoped to their row, item, dialog or region.
-
nth(),first()andlast()have a comment that says why position matters. -
hasTextfilters can't match a longer value by accident ("Invoice 4" vs "Invoice 42"). - Text that differs per environment (dates, ids, counts) uses a regular expression.
- New test ids follow the team's naming scheme, and the developer knows tests depend on them.
- Icon-only controls got an
aria-labelin the app, not a CSS selector in the test. - No
waitForTimeoutadded to "fix" a locator. A locator that needs a sleep is matching the wrong thing, or the test needs a web-first assertion. See flaky Playwright tests.
How Blendra ranks recorded locators
If you record flows with Blendra, it applies a similar ranking when it picks a step's locator. Its order is test id first (data-testid, data-test, data-cy, data-test-id), then role and accessible name, label, placeholder, the name attribute, text, and CSS last (locator priority). That puts test ids ahead of roles, which suits teams that already agreed test ids with their developers. A test id that looks like display text, such as a label copied into data-testid, is flagged as weak (test ids).
It also keeps up to four of the safer alternates it recorded for the same element (it skips ones that matched several elements, brittle CSS and roles without a name). The exported Playwright code joins them to the primary locator with locator.or(), so a step still finds its element when the primary stops matching. The page library rates each locator High, Medium or Low: a role with an exact name or a test id that doesn't look like display text is High, and CSS is Low. When a locator does break, a repair offers only locators recorded for that same step and waits for your approval.
FAQ
Is XPath bad in Playwright?
Not bad, just last. XPath ties a test to the DOM's nesting and is hard to read in review. It is still useful for an occasional legacy page with no roles, labels or ids. When you do use it, prefer short relative expressions on meaningful attributes, such as //input[@name="email"], over absolute paths.
XPath vs CSS in Playwright comes down to two differences. CSS pierces open shadow roots and XPath does not (other locators). XPath can step up to a parent with .., but filter({ has }) does the same job without tying the test to nesting. Both read the implementation, so both rank below the user-facing locators.
Should I use getByText or getByRole?
getByRole for anything a user interacts with: buttons, links, fields, tabs, rows. getByText for non-interactive content such as a success message or an empty-state paragraph. Text often appears in several places, so getByText hits strict mode violations more often.
When is nth() fine?
When position is the thing you are testing or relying on: a fixed column, the newest item in a list sorted by date, the last toast in a stack. Scope it to the smallest container first (row.getByRole('cell').nth(2), not page.locator('td').nth(14)), and say why in a comment.
Does Playwright pierce shadow DOM?
Yes, for open shadow roots, with every locator except XPath. Closed shadow roots are not supported.
How do I see which locator Playwright would choose?
Open UI mode (npx playwright test --ui) or the code generator (npx playwright codegen <url>) and use Pick locator. Treat the suggestion as a draft. Check it has a name, check it is unique, and scope it if the page repeats it. Playwright codegen shows how to turn recorded locators into maintainable ones.