Blog / Flaky tests and debugging
Flaky tests and debugging
Playwright Trace Viewer: Find Why a Test Failed in CI
Set up traces in CI, get them out of a failed job, and read them in five steps to find the real cause of a failure.
A test fails in CI. You run it on your laptop and it passes. The Playwright trace viewer exists for exactly this moment. It replays what the CI browser did, one action at a time. For each action you get the page as it looked, the network calls, the console output and the line of test code that ran. You don't need to reproduce anything locally.
This guide covers the whole loop. You'll turn tracing on, get the trace out of a failed CI job and read it in a fixed order. Then you'll see three common failure signatures and the pane that gives each one away. All the code was run against Playwright Test 1.61 and pytest-playwright 0.10 in October 2026.
TL;DR
- Set
trace: 'on-first-retry'andretries: process.env.CI ? 2 : 0. Without retries, that mode never records anything. - Upload
test-results/as a CI artifact when the job fails, then open it withnpx playwright show-trace. - Read the failing action first (Errors, Call, Log). Then check its Before and After snapshots, then Network, then Console, then Source.
- In Python, use
pytest --tracing retain-on-failure. - Traces hold typed values, cookies and request bodies. Keep them out of public issues.
Turn tracing on (modes and their cost)
Tracing is set in use.trace in playwright.config.ts. Here is the config this guide uses:
// playwright.config.ts
import { defineConfig } from '@playwright/test';

const baseURL = process.env.BASE_URL ?? 'http://localhost:4173';

export default defineConfig({
  testDir: './tests',
  // Retry only in CI, so the first retry can record a trace.
  retries: process.env.CI ? 2 : 0,
  reporter: [['list'], ['html', { open: 'never' }]],
  use: {
    baseURL,
    trace: 'on-first-retry',
    actionTimeout: 10_000,
  },
  webServer: {
    // Replace with your app's start command, for example 'npm run start'.
    command: 'node app/server.mjs',
    url: baseURL,
    reuseExistingServer: !process.env.CI,
  },
});
GitHub Actions always sets CI to true, so this config retries in CI and runs each test once on your machine. The actionTimeout turns a stuck click into a clear locator.click: Timeout 10000ms exceeded error. Without it, a stuck click runs until the test timeout.
Playwright offers seven modes. They are all listed under testOptions.trace:
| Mode | What it records | When to use it |
|---|---|---|
off |
Nothing | Suites where you never read traces |
on-first-retry |
Only the first retry of a failed test | The usual CI default. Costs nothing while tests pass |
on-all-retries |
Every retry | Hunting a flake that changes from one attempt to the next |
retain-on-failure |
Every run, kept only when it fails | CI without retries, when you need the trace of the very first failure |
retain-on-first-failure |
The first run only, kept if it failed | Like the one above, but retries are never recorded |
retain-on-failure-and-retries |
Every run, kept if it failed or is a retry | Full evidence for a known flaky area |
on |
Every run, always kept | Local debugging of a single test. The trace viewer docs warn that this is performance heavy |
The cost has two parts: the time spent recording, and the disk and artifact space the traces take. Every retain-* mode records every test and throws away the passing traces at the end, so you pay the recording cost on the whole suite. on-first-retry records nothing until a test has already failed once.
on-first-retry has one blind spot. You get a trace of the retry, not of the original failure. If the retry passes, you hold a trace of a passing run. That still helps, because you can compare it with the failure's error message. But if the first failure is the one you need to see, use retain-on-failure or retain-on-first-failure. For more on retry settings, see Test retries in the Playwright docs.
Get traces out of CI
Each trace lands in test-results/<test-name>-retry1/trace.zip, in a folder per test and attempt. The run above produced exactly that:
test-results/signatures-orders-page-lists-three-orders-retry1/trace.zipPlaywright empties test-results/ at the start of every run. So upload it in the same job, before the runner is thrown away. Here is a GitHub Actions workflow:
# .github/workflows/e2e.yml
name: e2e
on: [push, pull_request]

jobs:
  test:
    runs-on: ubuntu-latest
    timeout-minutes: 30
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-node@v4
        with:
          node-version: lts/*
      - run: npm ci
      - run: npx playwright install --with-deps chromium
      - run: npx playwright test
      - name: Upload traces of failed tests
        if: ${{ failure() }}
        uses: actions/upload-artifact@v4
        with:
          name: test-results-${{ github.run_attempt }}
          path: test-results/
          retention-days: 7
A few details matter here:
if: ${{ failure() }}uploads only when an earlier step failed. A test that failed once and then passed on retry leaves the job green, so its trace is not uploaded. To keep those traces too, useif: ${{ !cancelled() }}. That is what Playwright's CI guide uses for the HTML report.- The HTML report already contains the traces. With the
htmlreporter on,playwright-report/data/holds a copy of eachtrace.zip, and the report bundles its own trace viewer. If you already uploadplaywright-report/, runnpx playwright show-report <folder>on the download and click a test's trace. - Artifact names must be unique per run in
upload-artifactv4. If you shard, put the shard index in the name. See Playwright sharding for the matrix setup. retention-days: 7keeps traces for a week instead of the repository default, which GitHub sets to 90 days. The privacy section below explains why shorter is better.
Playwright's own docs still show actions/upload-artifact@v4. Newer major versions of the action exist, so check its README before you pin one.
To download from a terminal instead of the browser, use the GitHub CLI: gh run download <run-id> -n <artifact-name>.
Open a trace in the Playwright trace viewer
Unzip the artifact, then point the CLI at a trace:
npx playwright show-trace test-results/signatures-orders-page-lists-three-orders-retry1/trace.zipThis opens the viewer in its own window. Pass --port 0 (any free port) or a fixed port to serve it over HTTP instead. That is handy on a remote machine.
You can also drop the zip onto trace.playwright.dev. Playwright's docs say that page loads the trace entirely in your browser and sends no data anywhere. It is still a third-party page, so check your company's rules first.
Read a trace in five steps
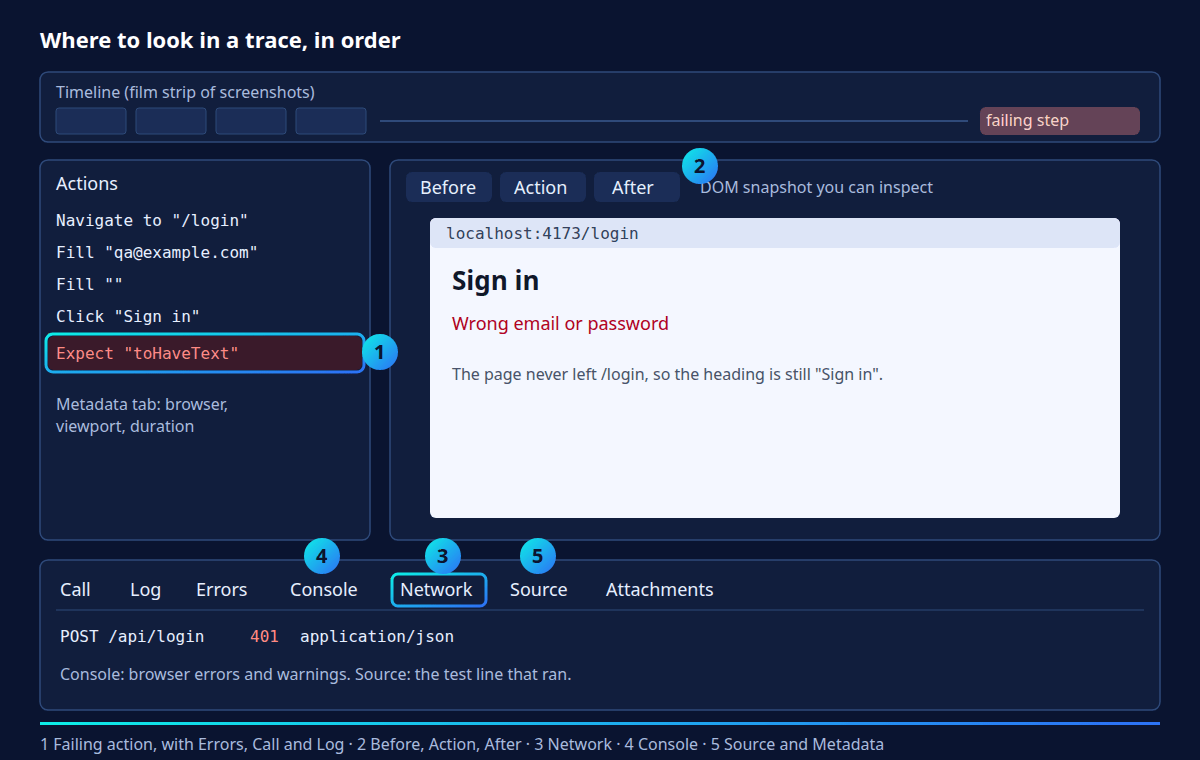
The viewer shows a lot at once. Read it in this order:
- The failing action. In the Actions list on the left, the failed step is red. Select it and read three tabs at the bottom. Errors has the assertion message. Call has the locator, timeout and parameters. Log has Playwright's own step-by-step account of what it waited for. Then read the actions above it. The root cause often sits one or two steps earlier.
- Before, Action and After snapshots. Each action has DOM snapshots from before it, from the moment of input and from after it. These are real DOM, not just screenshots. Check the address bar in the snapshot: a URL you didn't expect explains many "wrong text" failures.
- Network. The list can be filtered to the selected action. Look for 4xx and 5xx rows (they are shown in red), redirects to a login page, and empty response bodies.
- Console. This tab shows browser errors and warnings, and the test's own logs. A red error count beside an action in the list means console errors were logged while it ran.
- Source and Metadata. Source highlights the test line that ran. Metadata shows the browser, the viewport and the duration. Use it when CI and your laptop disagree about window size or browser.
Three failure signatures and where they show up
The examples below come from three tests that fail on purpose against a tiny local shop app. Run the suite with CI=1 npx playwright test and you get a retry trace for each one.
// tests/signatures.spec.ts
import { test, expect } from '@playwright/test';

test('checkout opens from the cart', async ({ page }) => {
  await page.goto('/');
  await page.getByRole('button', { name: 'Checkout' }).click();
  await expect(page).toHaveURL(/\/checkout$/);
});

test('signed-in user lands on their orders', async ({ page }) => {
  await page.goto('/login');
  await page.getByLabel('Email').fill('qa@example.com');
  await page.getByLabel('Password').fill(process.env.TEST_PASSWORD ?? '');
  await page.getByRole('button', { name: 'Sign in' }).click();
  await expect(page.getByRole('heading', { level: 1 })).toHaveText('Your orders');
});

test('orders page lists three orders', async ({ page }) => {
  await page.goto('/orders');
  await expect(page.getByRole('listitem')).toHaveCount(3);
});
1. Timeout waiting for an element
The error tells you that Playwright waited but not why:
TimeoutError: locator.click: Timeout 10000ms exceeded.Where it shows: the Log tab. Playwright found the button, then tried the click over and over. Here is the start of the Log, verbatim. After this it repeats the same cycle with longer waits until the timeout:
- waiting for getByRole('button', { name: 'Checkout' })
  - locator resolved to <button type="button" onclick="location.href='/checkout'">Checkout</button>
- attempting click action
  2 × waiting for element to be visible, enabled and stable
    - element is visible, enabled and stable
    - scrolling into view if needed
    - done scrolling
    - <div id="cookie-banner">…</div> intercepts pointer events
  - retrying click action
  - waiting 20ms
The Action snapshot shows the click target under a grey overlay. A cookie banner covered the button. This is a classic CI-only failure: the staging site that CI tests loads a consent banner, a chat widget or a promo modal that your local dev server never shows. If the log never reaches "locator resolved to", the locator matched nothing. That is a selector problem, not an overlay. Playwright's actionability checks page explains every check in that log.
2. Wrong text after navigation
Error: expect(locator).toHaveText(expected) failed

Locator:  getByRole('heading', { level: 1 })
Expected: "Your orders"
Received: "Sign in"
You might read this as "the orders page changed its heading". The trace says otherwise.
Where it shows: the Actions list, Network and the failed step's snapshot. The Actions list reads Fill "" for the password, so the field was filled with an empty string. Network shows POST /api/login returning 401. Select the failed Expect "toHaveText" step: its snapshot shows "Wrong email or password", and the address bar still reads /login. The navigation never happened. The TEST_PASSWORD secret was never set in CI. For how to pass it in, see environment variables in Playwright's docs.
Don't expect the click's After snapshot to show the message. The click returns as soon as the button is pressed, before the 401 response arrives. The message lands in the click's snapshot only when the server answers faster than that, so it varies from run to run.
3. A failing API call
Error: expect(locator).toHaveCount(expected) failed

Locator:  getByRole('listitem')
Expected: 3
Received: 0
Where it shows: Network and Console. Network has two orders rows. The page is 200, and the fetch to /api/orders is a red 500. Console shows the browser's Failed to load resource: the server responded with a status of 500 (Internal Server Error) and the app's own Failed to load orders: HTTP 500. A red error count in the Actions list points you at the console. It sits on whichever action was running when the error fired, here Navigate to "/orders" or the Expect step after it. The test is fine. The backend in that environment is not. Send it to whoever owns the API rather than editing the locator.
Next to each failure, Playwright 1.61 also writes an error-context.md file. It holds the error, the test source and an accessibility snapshot of the page. It is a quick first look when you can't open the trace yet.
Traces in Playwright for Python
pytest-playwright has a flag for this, and it accepts three values: on, off and retain-on-failure. There is no on-first-retry in the plugin.
pytest --tracing retain-on-failureTraces go to test-results/<test-id>/trace.zip, and you open them with the Python CLI: playwright show-trace test-results/<test-id>/trace.zip. The CI upload step is the same as above. For a full pytest setup, see pytest-playwright.
Outside pytest, record a trace yourself with the tracing API on the browser context:
# trace_manual.py: run with python trace_manual.py while the app is running
import os

from playwright.sync_api import sync_playwright

BASE_URL = os.environ.get("BASE_URL", "http://localhost:4173")

with sync_playwright() as p:
    browser = p.chromium.launch()
    context = browser.new_context()
    context.tracing.start(screenshots=True, snapshots=True, sources=True)
    page = context.new_page()
    try:
        page.goto(f"{BASE_URL}/login")
        page.get_by_label("Email").fill("qa@example.com")
        page.get_by_label("Password").fill("not-the-real-one")
        page.get_by_role("button", name="Sign in").click()
        page.get_by_role("alert").wait_for()
    finally:
        context.tracing.stop(path="trace.zip")
        browser.close()
Start tracing before you open the page. Stop it in finally so a failing step still writes the file.
Traces contain secrets: share them carefully
A trace is a recording of everything the test touched. When we unzipped the demo traces, we found:
- Typed values in plain text. The password from
fill()appears in the Actions list asFill "not-the-real-one"and in the action parameters inside the archive. - Cookies and headers. The
Cookie: session=…header of every request is in the network log. - Request and response bodies. The JSON posted to
/api/login, password included, is stored as a resource. - Your test source. With
sourceson, the archive includes the test files themselves. - Screenshots and DOM of every page the test saw, including any customer data on them.
Turning parts of the recording off reduces this but does not solve it:
// playwright.lean-trace.config.ts
import { defineConfig } from '@playwright/test';
import base from './playwright.config';

export default defineConfig({
  ...base,
  use: {
    ...base.use,
    trace: { mode: 'retain-on-failure', screenshots: false, snapshots: false, sources: false },
  },
});
With this config, the trace dropped the screenshots, the DOM snapshots and the network log. The typed password was still in the action list. Treat every trace as sensitive. So:
- Never attach a trace to a public issue, a public pull request or an open chat channel. Rebuild the failure with fake data instead.
- On a public repository, remember that anyone with read access can download artifacts. Keep
retention-daysshort, or don't upload traces from public pipelines. - Run E2E tests with test-only accounts and seeded data, never a real person's login.
- Playwright's CI guide gives the same advice for reports and logs: upload them only to trusted artifact storage, or encrypt them first.
What Blendra shows for a failed test, and what it doesn't yet
If your suite reports to Blendra, every failed test gets a cause. A cause names what happened, whose move it is (for example Environment, Test needs repair or Possible bug), how sure Blendra is and one next step. Causes are rule-based. They come from the error Playwright reported, the run's check results and the test's earlier runs. They are free on every plan and use no AI (Diagnose failures). Typical causes read "The test environment was unreachable", "The app returned a server error (HTTP 503)" or "The test password isn't set where the tests ran". For runs from your own CI, the causes show on the run page in Blendra. Sending CI results needs an API token, which comes with Pro and above. The failure codes underneath are listed in Failure reasons.
What Blendra doesn't do: the reporter sends test results from your CI, not trace files. The trace of a CI failure stays in your CI artifacts, so keep tracing on there. A Playwright TypeScript suite exported from Blendra already ships trace: 'on-first-retry' with two retries in CI. Its GitHub Actions workflow uploads the reports/ folder on every run, traces included. Causes tell you where to look first. The trace is how you confirm it.
FAQ
Why is my trace empty, or missing?
The most common reason is trace: 'on-first-retry' with retries: 0. No retry means no trace, and we confirmed that a local run with this config writes no trace.zip. Other causes: the upload step ran in a different job, on a fresh runner with no test-results/. A second playwright test command in the same job emptied the folder first. Or your config sets outputDir, so the traces went to that folder and not to test-results/.
Should CI record every trace or only on the first retry?
Use on-first-retry with retries, or retain-on-failure without them. on keeps a trace for every test, including the passing ones, and Playwright's docs call it performance heavy. Save it for local work on one test.
Can I trace just one test?
Yes. Override the config from the command line and filter to the test: npx playwright test -g "orders page" --trace on. -g matches the test title, so it keeps working when line numbers move. --trace takes the same mode names as the config. In Python, run pytest -k orders --tracing on.
How large are traces?
They grow with the number of actions, the page size, screenshots and network bodies. The tiny demo traces here are tens of kilobytes. A long test on a real app with images and fonts is much larger. Check yours with du -sh test-results/*/trace.zip. If artifact space is tight, keep only failures (retain-on-failure) and set screenshots: false in the trace object.
Do traces help with flaky tests?
They are the best evidence you have, but one trace shows one attempt. Compare a failing attempt with a passing one using on-all-retries or retain-on-failure-and-retries. Then follow the method in Flaky Playwright tests: find the cause, fix it, prove it's fixed.