Playwright
Playwright Test Data: Seed, Isolate and Clean Up Without Flakes
Patterns for creating, isolating and cleaning up test data in Playwright so parallel tests stop colliding.
Most Playwright test data problems show up the day you turn on parallel workers. A test that passed for months fails with "That email is already registered", or reads a name another test just wrote. The fix is not fewer workers. Each test should own the data it touches: it creates that data, uses it, and deletes it, without ever seeing another test's records.
This guide ranks four ways to get data into a test, then builds the pattern most suites need: seed through the API, make every value unique, and clean up in fixture teardown, with a safety net for what teardown misses. Every example was run on 22 October 2026 with @playwright/test 1.61 against a small demo app. Download the examples: the app is plain Node with no dependencies, and a collisions/ folder holds the broken versions so you can watch them fail.
TL;DR
- Read-only data can be shared. A product catalogue or a country list seeded once is fine. Anything a test edits, counts or must keep unique is not.
- Create what you change, per test, through the API. A fixture calls
request.post, hands the record to the test withuse(), and deletes it afterwards. - Make values unique across workers, retries, shards and pipelines. Combine a run id,
testInfo.parallelIndexand a random part. Don't rely on the parallel index alone. - Teardown runs when a test fails or times out, but not when the worker process dies. Add a teardown project that deletes this run's leftovers by prefix.
- Assert on your own records, never on totals. "Users (1)" breaks as soon as another worker adds a user.
- Secrets are not test data. Tokens and passwords come from environment variables, never from a JSON file in the repo.
Four Playwright test data patterns, ranked by isolation
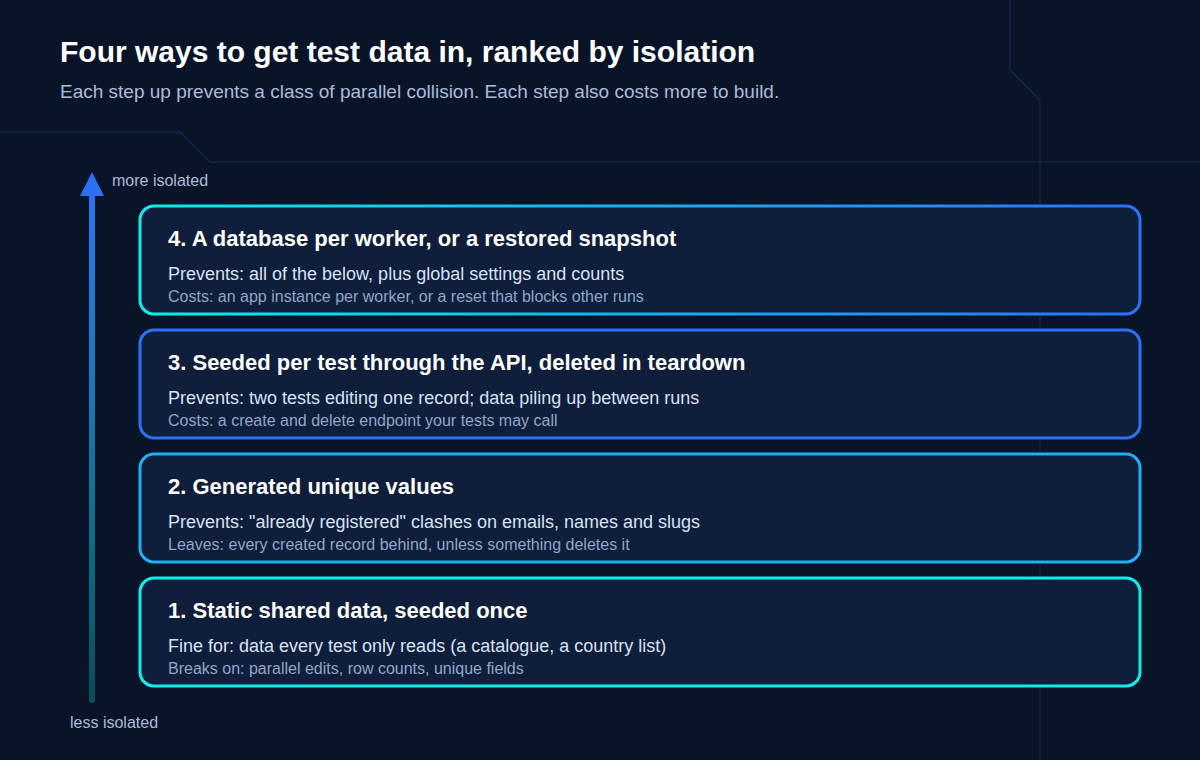
| Pattern | Good for | Breaks when |
|---|---|---|
| 1. Static data, seeded once | Data every test only reads | Two tests edit the same record, or a test counts rows |
| 2. Generated unique values | Sign-up forms, names, slugs | Nothing deletes the records, so the environment fills up |
| 3. Seeded per test through the API, deleted in teardown | Anything a test changes | Your app has no API to create the data, or teardown never runs |
| 4. A database per worker, or a restored snapshot | Global settings, feature flags, counts | You can't run an app instance per worker |
Most suites mix them, and keep pattern 4 for tests that change something global.
Three collisions you can reproduce
The collisions/ folder in the examples does each of these wrong on purpose. With four workers, three of its six tests failed on every run we tried. These are the real messages.
A hard-coded email in two sign-up tests. The second one to submit loses:
Error: expect(locator).toHaveText(expected) failed
Locator:  getByRole('alert')
Expected: "Welcome, Jane Doe!"
Received: "That email is already registered."
Three tests rename one pre-seeded user at the same time, then reload and check the name:
Locator:  getByRole('heading', { level: 1 })
Expected: "Grace Hopper"
Received: "Katherine Johnson"
Which rename test failed changed between runs. That is the signature of shared data: a different test fails each time, and the failure looks like a timing bug. With --workers=1, all three rename tests pass, so the bug hides until someone raises the worker count.
A test counts users while other tests create them:
Expected: "Users (1)"
Received: "Users (2)"
This one failed even with one worker, because the sign-up tests ran first in the same file. Counts depend on everything else that ran against the environment, including other pipelines.
Seed through the API with the request fixture
Creating data through the UI is slow, and it makes every test depend on the sign-up form working. Your API is faster and more direct. Playwright's built-in request fixture sends HTTP requests from Node and reads baseURL from your config, so request.post('/api/users') goes to the same app the browser tests (see the API testing guide). If a test only needs the page to show some data, and nothing has to be stored, mock the response instead.
Wrap the create and delete in a fixture. Code before await use() is setup, and code after it is teardown:
// tests/fixtures.ts
import { test as base, expect } from '@playwright/test';
import { adminHeaders, uniqueEmail } from './test-data';

type User = { id: string; name: string; email: string };

export const test = base.extend<{ user: User }>({
  user: async ({ request }, use, testInfo) => {
    // Setup: create a fresh user through the API.
    const response = await request.post('/api/users', {
      headers: adminHeaders(),
      data: { name: 'Test User', email: uniqueEmail(testInfo) },
    });
    expect(response.status(), await response.text()).toBe(201);
    const user: User = await response.json();

    // Hand the user to the test.
    await use(user);

    // Teardown: runs after the test, even when the test failed.
    const deleted = await request.delete(`/api/users/${user.id}`, {
      headers: adminHeaders(),
    });
    // 404 is fine: the test may have deleted the user itself.
    expect([204, 404]).toContain(deleted.status());
  },
});

export { expect };
A test asks for user and gets its own record. Three of these run in parallel and never see each other:
// tests/profile.spec.ts
import { test, expect } from './fixtures';

// Three tests rename "their" user at the same time. Each one has its own
// user, so none of them can see another test's name.
for (const newName of ['Grace Hopper', 'Katherine Johnson', 'Margaret Hamilton']) {
  test(`renames the user to ${newName}`, async ({ page, user }) => {
    await page.goto(`/users/${user.id}`);
    await page.getByLabel('Display name').fill(newName);
    await page.getByRole('button', { name: 'Save' }).click();
    await expect(page.getByRole('status')).toHaveText('Saved');

    await page.reload();
    await expect(page.getByRole('heading', { level: 1 })).toHaveText(newName);
  });
}
Three details in the fixture matter more than they look.
The status check carries the response body. expect(response.status(), await response.text()) puts the API's error message in the failure. "Expected 201, received 409" tells you less than the body that says why.
The admin token goes on each request, not in use.extraHTTPHeaders. The request fixture would pick it up from there, but so would the browser. We checked: with the token in test.use({ extraHTTPHeaders }), a fetch('/api/users') from inside the page got a 200 instead of a 401. Your UI tests would quietly run with admin rights. Pass the token per call, or use a separate playwright.request.newContext() for admin calls.
Fixtures depend on each other in the right order. If you add a project fixture that needs user, Playwright sets up user first and tears it down last. The project is deleted before its owner, so foreign keys don't block the cleanup.
Fail fast when seeding can't work
A missing or wrong token fails every test with the same 401. Two cheap checks avoid that. The config refuses to start without the variable:
// playwright.config.ts (excerpt)
if (!process.env.DEMO_ADMIN_TOKEN) {
  throw new Error('Set DEMO_ADMIN_TOKEN (see .env.example).');
}
And a setup project makes one authenticated call before any test runs:
// tests/run.setup.ts
import { test as setup, expect } from '@playwright/test';
import { adminHeaders } from './test-data';

// Fails once, early, with a clear message when the seed API is unusable,
// instead of failing every test with the same 401.
setup('the seed API accepts our token', async ({ request }) => {
  const response = await request.get('/api/users', { headers: adminHeaders() });
  expect(response.status(), 'Check DEMO_ADMIN_TOKEN').toBe(200);
});
Unique data per test and per worker
The fixture creates a new user, but the email still has to be unique. Many teams reach for Date.now(). Two workers can call it in the same millisecond. Others use testInfo.workerIndex or testInfo.parallelIndex. Those identify a worker within one run only, and the parallelism docs explain the difference:
parallelIndexis between0andworkers - 1. When a worker restarts, the new process gets the sameparallelIndex.workerIndexis unique per worker process in a run, so a restart gets a new one.
Neither is unique across shards. Each shard is its own Playwright run on its own machine, so every shard has a worker with parallelIndex 0. Two pipelines against one staging environment have the same problem. So build the value from three parts:
// tests/test-data.ts
import { randomUUID } from 'node:crypto';
import type { TestInfo } from '@playwright/test';

/** Every record this run creates starts with this prefix. */
export const runPrefix = () => `e2e-${process.env.E2E_RUN_ID}`;

/**
 * A unique email per call, readable in logs and safe across workers,
 * retries, shards and parallel pipelines:
 *   e2e-<run id>-w<parallel index>-<random>@example.test
 */
export function uniqueEmail(testInfo: TestInfo): string {
  const random = randomUUID().slice(0, 8);
  return `${runPrefix()}-w${testInfo.parallelIndex}-${random}@example.test`;
}

/** Headers for the admin API. Only Node-side code uses them, never the browser. */
export function adminHeaders() {
  return { Authorization: `Bearer ${process.env.DEMO_ADMIN_TOKEN}` };
}
The random part does the work of being unique. The run id and the worker number make a leftover record easy to trace: e2e-ci-4821-w3-ae9253df@example.test came from pipeline 4821, worker 3. The domain matters too. RFC 2606 reserves the .test top-level domain for testing, so an address under it never belongs to a real person who could receive your sign-up emails.
The run id has to be the same in every worker, and workers start as separate processes. Set it once in the config. The runner sets it before it starts the workers, and each worker inherits it:
// playwright.config.ts (excerpt)
process.env.E2E_RUN_ID ||= Date.now().toString(36);
In CI, pass the pipeline's id instead, for example E2E_RUN_ID=$GITHUB_RUN_ID. We checked both: with the generated id, the teardown project in a separate worker matched records created by test workers, and with E2E_RUN_ID=ci-4821, every email started with e2e-ci-4821-. The suite also passed with --repeat-each=5 on four workers, 42 tests in total, with no collisions.
Generate the value inside the test or fixture, not at the top of the file. A worker evaluates a file once, so a value computed at file level is shared by every test of that file in that worker. Two of those tests then create the same email, which is the collision you were trying to avoid.
Clean up in fixture teardown
Teardown is the code after await use(). We tested when it runs with the user fixture above. After a failed assertion, it ran and deleted the user. After a test hit its 2-second timeout, it still ran. When the test killed its own worker with process.exit(1), Playwright reported worker process exited unexpectedly (code=1, signal=null) and the user stayed in the app.
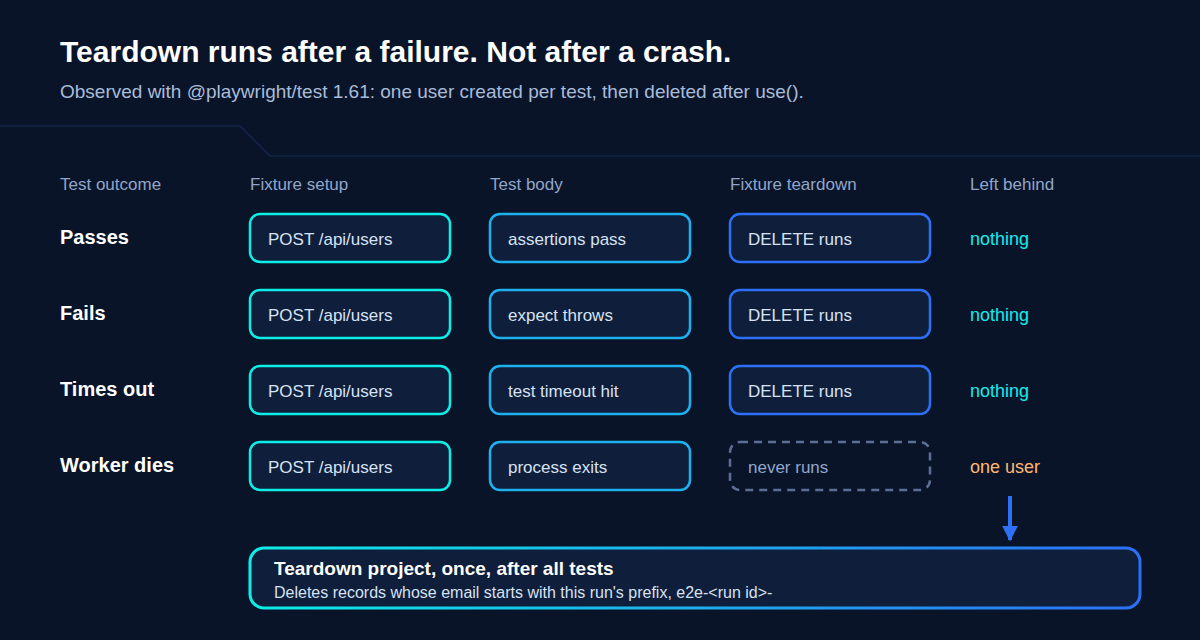
A worker can also be killed from outside, for example when the machine runs out of memory. So add a safety net. A teardown project runs after every project that depends on its setup project has finished. It finds this run's records by prefix and deletes them:
// tests/run.teardown.ts
import { test as teardown, expect } from '@playwright/test';
import { adminHeaders, runPrefix } from './test-data';

// A safety net for records whose fixture teardown never ran (a crashed
// worker, a timeout in teardown). It only touches this run's records.
teardown('delete leftovers from this run', async ({ request }) => {
  const response = await request.get('/api/users', { headers: adminHeaders() });
  expect(response.ok()).toBe(true);
  const users: { id: string; email: string }[] = await response.json();

  const leftovers = users.filter((u) => u.email.startsWith(`${runPrefix()}-`));
  for (const user of leftovers) {
    await request.delete(`/api/users/${user.id}`, { headers: adminHeaders() });
  }
  console.log(`sweep: removed ${leftovers.length} leftover user(s)`);
});
Wire it up in the config. The browser project depends on preflight, and preflight names sweep as its teardown:
// playwright.config.ts
import { existsSync } from 'node:fs';
import path from 'node:path';
import { defineConfig, devices } from '@playwright/test';

// Local runs read secrets from a git-ignored .env file (Node 20.12+).
// Variables already set in the environment (as in CI) are kept.
const envFile = path.join(__dirname, '.env');
if (existsSync(envFile)) process.loadEnvFile(envFile);

// Fail fast with one clear message instead of a 401 in every test.
if (!process.env.DEMO_ADMIN_TOKEN) {
  throw new Error('Set DEMO_ADMIN_TOKEN (see .env.example).');
}

// One id per run, shared by every worker: workers inherit the runner's
// environment. In CI, pass the pipeline's id instead (for example
// E2E_RUN_ID=$GITHUB_RUN_ID) so you can find a run's leftovers later.
process.env.E2E_RUN_ID ||= Date.now().toString(36);

export default defineConfig({
  testDir: './tests',
  fullyParallel: true,
  workers: 4,
  use: {
    baseURL: 'http://localhost:4185',
    trace: 'retain-on-failure',
  },
  projects: [
    { name: 'preflight', testMatch: /run\.setup\.ts/, teardown: 'sweep' },
    { name: 'sweep', testMatch: /run\.teardown\.ts/ },
    {
      name: 'chromium',
      use: { ...devices['Desktop Chrome'] },
      dependencies: ['preflight'],
    },
  ],
  webServer: {
    command: 'node app/server.mjs',
    url: 'http://localhost:4185/signup',
    reuseExistingServer: !process.env.CI,
    env: { DEMO_ADMIN_TOKEN: process.env.DEMO_ADMIN_TOKEN },
  },
});
The sweep also catches data the UI created. In the examples, the "valid details" sign-up test creates a user through the form, so no fixture owns it. Every full run ended with sweep: removed 1 leftover user(s): that sign-up user. When the sweep removes more than you expect, a teardown is failing or a worker died. That is worth a look.
Three rules keep cleanup safe:
- Delete by the id the API returned. The fixture never searches for "the test user". It deletes exactly the record it created.
- Scope the sweep to one run. A sweep that deletes every
e2e-record will delete records another pipeline is using right now. - Make teardown tolerate a 404. A test that deletes its own user is valid, and the teardown should not fail it.
Note that --no-deps skips setup projects and their teardowns, so the sweep won't run. Fine locally; in CI, keep the dependencies.
When you need a database per worker
Some tests change state every test shares: a feature flag, a global setting, a dashboard total. Unique records can't isolate those. The usual answer is an app instance and a database per worker, set up by a worker-scoped fixture ({ scope: 'worker' }). Name the database after parallelIndex, not workerIndex. A worker restarts after every test failure, and the replacement keeps the same parallelIndex, so it reconnects to the same database instead of building a new one.
To make a fresh copy fast, PostgreSQL can create a database from a template: CREATE DATABASE test_w0 TEMPLATE app_seed. The catch, from the PostgreSQL docs, is that the copy fails if any other session is connected to the template database. So keep the template for copying only, and never point a running app at it.
Resetting one shared database between tests looks simpler, but with parallel workers a reset deletes another test's data halfway through its run. If you must reset a shared environment, put those tests in a separate project that depends on all the others, so it starts after they finish, and give it fullyParallel: false with its tests in one file.
Data files and data-driven loops
Data-driven tests read a list of cases and create one test per case. Playwright TypeScript can import a JSON file directly:
[
  {
    "case": "valid details",
    "name": "Mary Jackson",
    "email": "{{unique}}",
    "message": "Welcome, Mary Jackson!"
  },
  {
    "case": "email already registered",
    "name": "Ada Again",
    "email": "ada@example.test",
    "message": "That email is already registered."
  }
]
That is an excerpt; the full data/signup-cases.json in the examples has four cases. The spec loops over it:
// tests/signup.spec.ts
import { test, expect } from '@playwright/test';
import cases from '../data/signup-cases.json';
import { uniqueEmail } from './test-data';

for (const row of cases) {
  // The title must be unique, so it carries the case name.
  test(`sign up: ${row.case}`, async ({ page }, testInfo) => {
    // Resolve placeholders inside the test: every test and retry gets its own email.
    const email = row.email === '{{unique}}' ? uniqueEmail(testInfo) : row.email;

    await page.goto('/signup');
    await page.getByLabel('Name').fill(row.name);
    await page.getByLabel('Email').fill(email);
    await page.getByRole('button', { name: 'Create account' }).click();

    await expect(page.getByRole('alert')).toHaveText(row.message);
  });
}
The parameterize guide notes that test titles must be unique, so put the case name in the title. The {{unique}} placeholder keeps the data file static and readable while each run still gets a new email. The duplicate-email case reads a pre-seeded user and never changes it, which is the one safe use of static shared data.
The same guide shows CSV with the csv-parse package, which suits cases kept in a spreadsheet. JSON needs no dependency.
The flaky alternative to a count is worth seeing next to its fix:
// tests/users-list.spec.ts
import { test, expect } from './fixtures';

test('the new user appears in the user list', async ({ page, user }) => {
  await page.goto('/users');

  // Flaky: other workers add and delete users while this test runs.
  // await expect(page.getByRole('row')).toHaveCount(3);

  // Stable: find this test's own row and check it.
  const row = page.getByRole('row').filter({ hasText: user.email });
  await expect(row).toHaveCount(1);
  await expect(row.getByRole('link')).toHaveText(user.name);
});
Secrets are not test data
An admin token, a test password or a payment provider's test key does not belong in the JSON file next to the emails. A data file is committed, copied into reports and pasted into tickets. A secret belongs in an environment variable.
The config above loads a git-ignored .env file with Node's built-in process.loadEnvFile, added in Node 20.12 and no longer experimental since Node 22.21 and 24.10. You don't need the dotenv package. We checked the order: a variable already set in the environment wins over the file. So CI secrets override a stray local file. Commit a .env.example that lists the names with empty values, so a new teammate knows what to set.
For login state, which is the other kind of secret test data, see Playwright authentication. It covers one account per worker with the same parallelIndex idea. For several environments and their variables, see Playwright environment variables.
The same fixture in Playwright Python
With pytest-playwright, a fixture that yields has the same shape. Code after yield is teardown, and pytest runs it whether the test passed or failed:
# conftest.py
import os
import uuid

import pytest
from playwright.sync_api import APIRequestContext, Playwright


@pytest.fixture(scope="session")
def admin_api(playwright: Playwright, base_url: str):
    # A separate request context: the admin token never reaches the browser.
    api = playwright.request.new_context(
        base_url=base_url,
        extra_http_headers={"Authorization": f"Bearer {os.environ['DEMO_ADMIN_TOKEN']}"},
    )
    yield api
    api.dispose()


@pytest.fixture
def user(admin_api: APIRequestContext):
    email = f"e2e-py-{uuid.uuid4().hex[:8]}@example.test"
    response = admin_api.post("/api/users", data={"name": "Test User", "email": email})
    assert response.status == 201, response.text()
    created = response.json()

    yield created  # the test runs here

    # Teardown: runs after the test, pass or fail.
    deleted = admin_api.delete(f"/api/users/{created['id']}")
    assert deleted.status in (204, 404)
After a run with pytest --base-url http://localhost:4185, the app held only its pre-seeded user.
Test data in a Blendra export
Blendra records a flow in your browser and exports it as a Playwright suite. Each enabled scenario of a recording, such as the happy path and its data variations, becomes its own test. The values each scenario types live in fixtures/test-data/<journey>.data.ts, one object per scenario that types values, kept apart from the page objects and imported by the spec. See Scenarios in export and the generated project structure.
Sensitive values never reach that file. A password or card number is written as a reference such as process.env.TEST_PASSWORD!, .env.example lists the names, and the suite stops before the first step with "Missing test credentials" when one is unset. Sensitive values lists what is detected. The Playwright Python and Cypress exports (Beta, on Pro+ and Team) keep the same data as JSON, with each secret as an {{env:NAME}} reference.
What the export does not do is create or delete records in your backend. A recorded sign-up types the same email on every run, so its second run against the same environment meets "already registered" unless something deletes the user in between. For a journey like that, give each scenario its own value and add cleanup, or build the value in the data file with a helper like uniqueEmail above. The exported config runs tests in parallel on your machine (fullyParallel: true) and with one worker in CI, so two scenarios that create the same record collide locally first.
FAQ
Should I use beforeAll or a fixture to seed data?
Use a fixture. A beforeAll record is shared by the tests of that file that run in the same worker. With fullyParallel, a file's tests can spread over several workers, and each worker runs beforeAll again. You get a few shared records, not one per test. A test-scoped fixture gives each test its own record and cleans it up in the same place. Keep beforeAll, or a worker-scoped fixture, for data the tests only read.
Is Date.now() unique enough for test emails?
No. Two workers can read the same millisecond, and so can two shards on different machines. Add a random part such as randomUUID().slice(0, 8). Keep the timestamp or run id only to make leftovers easy to trace.
Does fixture teardown run when a test fails?
Yes. In our runs it ran after a failed assertion and after a test timeout. It did not run when the worker process exited, which is why the end-of-run sweep exists. Teardown time counts toward the test timeout, and you can give a slow fixture its own limit with the { timeout } option.
Can I just run the tests with one worker instead?
It fixes less than you'd think. With --workers=1, only the rename collision went away. The fixed email still failed, because the second test ran after the first, and the count still failed, because the sign-up tests ran before it. You also pay in run time on every run. Fix the data, then raise the worker count, and see Playwright sharding when one machine is no longer enough.