Blog / Flaky tests and debugging
Flaky tests and debugging
Playwright Retries: Configure Them, Read Them, Don't Let Them Hide Bugs
How retries work in Playwright, what 'flaky' in the report means, and a policy that keeps retries honest.
Playwright retries run a failed test again, and a test that passes the second time turns a red build green. That keeps a pipeline moving, and it is also how a real bug gets merged. This guide shows what happens during a retry, how to configure retries at every level, how to read the "flaky" status Playwright gives a test that passed late, and a policy that keeps retries honest.
Every example ran on Playwright 1.61.1 against a small local app that the config starts. The app has two deliberate quirks: report names are unique (a second create answers 409), and the first export of each report answers 503 with "Export service is warming up". So every export test fails its first attempt and passes its retry, on every run. Download the examples: the app is plain Node with no dependencies, global-setup.ts empties it before each run, and demo/ holds the two tests that fail on purpose. The README lists every command with the result we got.
TL;DR
- Retries are off by default. Turn them on in CI only:
retries: process.env.CI ? 2 : 0. - A failed test throws away its worker. The retry runs in a new process with a new browser, and
beforeAllruns again. - A test that fails and then passes is flaky, not passed. A run with flaky tests and no failures still exits 0, unless you set
failOnFlakyTests. test.describe.configure({ retries })wins over the config and over--retrieson the command line.- Clean up what a failed attempt left behind, or the retry fails for a different reason. Fixture teardown does this best;
testInfo.retryis the backstop. - The JUnit reporter writes a flaky test as a plain pass. Read retry results from the list, HTML or JSON reporter.
How a retry runs
Playwright runs tests in worker processes, and each worker has its own browser. When a test fails, Playwright throws that worker away and starts a new one. With retries on, the new worker runs the failed test again first, then carries on with the rest of the file (Retries).
This file makes the mechanics visible. Its first test fails its first attempt on purpose:
import { test, expect } from '@playwright/test';

// One retry for this file only, whatever the config or the command line says.
test.describe.configure({ retries: 1 });

test.beforeAll(async ({}, testInfo) => {
  console.log(`beforeAll   worker ${testInfo.workerIndex}, pid ${process.pid}`);
});

test.afterAll(async ({}, testInfo) => {
  console.log(`afterAll    worker ${testInfo.workerIndex}, pid ${process.pid}`);
});

test.beforeEach(async ({}, testInfo) => {
  console.log(`beforeEach  "${testInfo.title}", retry ${testInfo.retry}`);
});

test('fails on the first attempt only', async ({}, testInfo) => {
  // Demo only: fail the first attempt on purpose, so the retry always happens.
  expect(testInfo.retry, 'the first attempt fails on purpose').toBeGreaterThan(0);
});

test('runs after it', async ({}, testInfo) => {
  console.log(`test body   "${testInfo.title}", retry ${testInfo.retry}`);
});
The output of npx playwright test tests/lifecycle.spec.ts, error details trimmed:
Running 2 tests using 1 worker

beforeAll   worker 0, pid 872254
beforeEach  "fails on the first attempt only", retry 0
afterAll    worker 0, pid 872254
  ✘  1 [ui] › tests/lifecycle.spec.ts:18:5 › fails on the first attempt only (4ms)
beforeAll   worker 1, pid 872285
beforeEach  "fails on the first attempt only", retry 1
  ✓  2 [ui] › tests/lifecycle.spec.ts:18:5 › fails on the first attempt only (retry #1) (3ms)
beforeEach  "runs after it", retry 0
test body   "runs after it", retry 0
afterAll    worker 1, pid 872285
  ✓  3 [ui] › tests/lifecycle.spec.ts:23:5 › runs after it (0ms)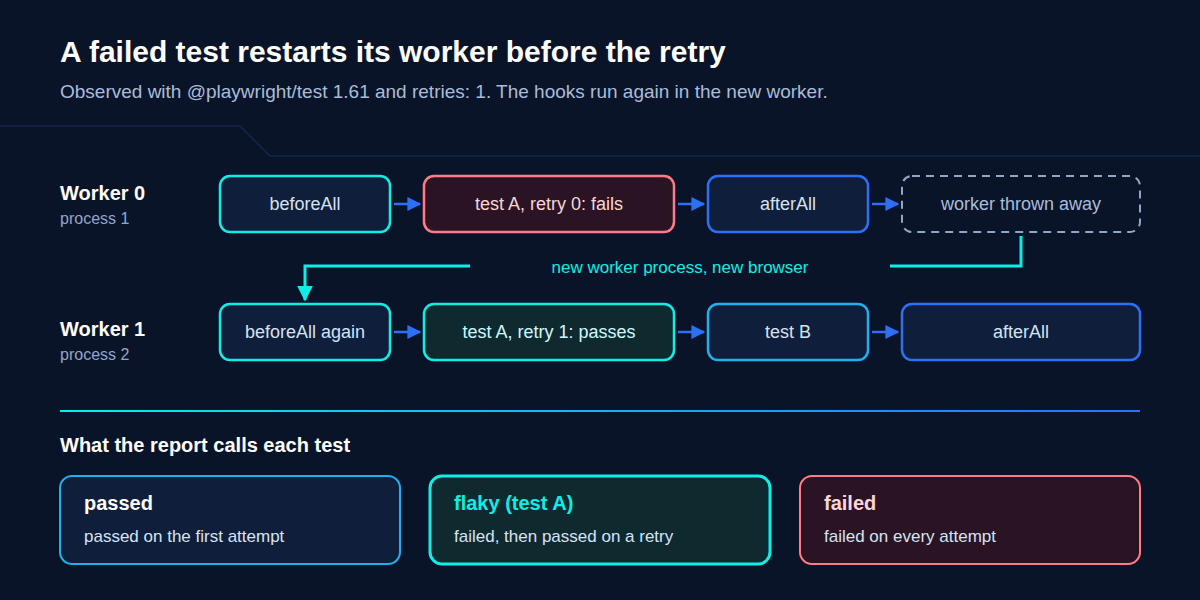
What that tells you:
beforeAllruns again in the new worker, andafterAllalready ran in the old one. IfbeforeAllseeds data, a retry seeds it twice.- Everything is fresh. New process, new browser, new context. Worker-scoped fixtures are set up again too. Nothing in memory survives from the failed attempt, but anything it wrote to a server or a database does.
testInfo.retrycounts attempts. It is 0 on the first run, 1 on the first retry, and so on.- The rest of the file moves. "runs after it" ran in worker 1, because worker 0 no longer existed.
- Serial groups retry as a whole. With
test.describe.configure({ mode: 'serial' }), the whole group runs again in the new worker. In our check, the test before the failing one ran a second time, andtestInfo.retrywas 1 for every test in the group. - Every failed attempt pays its full wait. The export test below took 5.2 s to fail, because its assertion waited out the 5-second expect timeout, and 0.3 s to pass on the retry. A test that hits the default 30-second test timeout with
retries: 2costs about 90 seconds before it is reported as failed.
Configure Playwright retries
You can set retries in four places: the top of the config, a project, a file or describe group, and the command line.
In the config, globally and per project
This is the config the examples use:
import { defineConfig, devices } from '@playwright/test';

export default defineConfig({
  testDir: './tests',
  // Retry failed tests twice in CI. Locally, a failure stays a failure.
  retries: process.env.CI ? 2 : 0,
  reporter: [
    ['list'],
    ['json', { outputFile: 'results/results.json' }],
    ['junit', { outputFile: 'results/junit.xml' }],
    ['html', { outputFolder: 'results/html', open: 'never' }],
  ],
  use: {
    baseURL: 'http://127.0.0.1:4471',
    // Keep a trace of the first retry of a failed test.
    trace: 'on-first-retry',
  },
  projects: [
    { name: 'ui', testIgnore: /api\.spec\.ts/, use: { ...devices['Desktop Chrome'] } },
    // API tests have no UI to race: no whole-test retries, poll a slow call instead.
    { name: 'api', testMatch: /api\.spec\.ts/, retries: 0 },
  ],
  // The demo app: started for the run, emptied before it.
  webServer: {
    command: 'node server.mjs',
    url: 'http://127.0.0.1:4471/reports',
    reuseExistingServer: !process.env.CI,
  },
  globalSetup: './global-setup.ts',
});
Projects inherit the top-level retries unless they set their own. Here, UI tests get two retries in CI and API tests get none. An API test has no rendering or animation to race. When it fails, the cause is usually the API or the test, and a whole-test retry mostly hides it. If one call is allowed to be slow, poll that call instead (see below).
Per file or group: describe.configure retries
test.describe.configure({ retries }) sets retries for a whole file when you call it at the top level, or for one group when you call it inside test.describe. Use it to switch retries off where a retry is harmful, not to switch them up for a test you don't trust:
import { test, expect } from '@playwright/test';

test.describe('report creation', () => {
  // Creating a report is not idempotent, so a blind retry would trip over the first attempt.
  test.describe.configure({ retries: 0 });

  test('create a report', async ({ page, request }) => {
    await page.goto('/reports');
    await page.getByLabel('Report name').fill('Yearly sales');
    await page.getByRole('button', { name: 'Create report' }).click();
    await expect(page.getByRole('status')).toHaveText('Created: Yearly sales');

    await request.delete('/api/reports/Yearly%20sales');
  });
});
There is no retries option on a single test(). To change one test, wrap it in a describe group as above.
On the command line
npx playwright test --retries=3 overrides the top-level config and every project, for that run only.
Which setting wins
We set retries: 3 at the top, retries: 1 on one project, retries: 2 on a describe group and retries: 0 on a group nested inside it, then counted the attempts of tests that always fail:
| Setting | Example | Wins over | Attempts we saw |
|---|---|---|---|
Innermost describe.configure |
{ retries: 0 } |
everything else, including --retries |
1 |
describe.configure |
{ retries: 2 } |
the command line, project and config | 3 |
--retries |
--retries=0 |
project and top-level config | 1 |
| Project | retries: 1 |
top-level config | 2 |
| Top-level config | retries: 3 |
the default of 0 | 4 |
The surprise is the second row. With --retries=0 on the command line, the tests inside describe.configure({ retries: 2 }) still ran three times. That matters when you prove a fix with --repeat-each=20 --retries=0, as the flaky tests guide recommends. If the file sets its own retries, the retries are still on. Search the file for describe.configure first, and check that the output has no (retry #1) lines.
Read the flaky status
Playwright gives every test one of three outcomes, plus skipped:
- passed: passed on the first attempt.
- flaky: failed at least once, then passed on a retry.
- failed: failed on every attempt.
Each reporter shows this differently, and one of them drops it altogether. With the config above and three flaky tests:
- List reporter. Each retry gets a
(retry #1)suffix, and the summary counts flaky tests separately:3 flakyabove3 passed. - Dot reporter.
×means failed and will be retried,±means passed on retry. Two export tests print××±±. - HTML reporter. The filter bar has a Flaky count next to Passed and Failed. Each flaky test has a tab per attempt (Run, then Retry #1), with that attempt's error, steps and attachments.
- JSON reporter. The test's
statusis"flaky", and itsresultsarray holds one entry per attempt, each with its own error. - JUnit reporter. Our run wrote
tests="6" failures="0"with no flaky marker anywhere. A dashboard that reads onlyjunit.xmlsees six clean passes.
The exit code ignores flakiness by default: the run above exited 0. failOnFlakyTests: true in the config (added in Playwright 1.52) or --fail-on-flaky-tests on the command line fails the run when any test was flaky. The same suite with the flag exited 1.
List flaky tests from the JSON report
The HTML report is good for one test. For a whole run, or a nightly job, this script lists every flaky test with the error from its first attempt:
// Lists every flaky test in a Playwright JSON report, with the error from its FIRST attempt.
// Usage: node flaky-summary.mjs results/results.json
import { readFileSync } from 'node:fs';

const file = process.argv[2] ?? 'results/results.json';
const report = JSON.parse(readFileSync(file, 'utf8'));

function* tests(suite, titles = []) {
  for (const spec of suite.specs ?? []) {
    for (const test of spec.tests) yield { titles: [...titles, spec.title], spec, test };
  }
  for (const child of suite.suites ?? []) {
    yield* tests(child, child.file === suite.file ? [...titles, child.title] : titles);
  }
}

const strip = (text) => text.replace(/\u001b\[[0-9;]*m/g, '');
let flaky = 0;

for (const suite of report.suites) {
  for (const { titles, spec, test } of tests(suite)) {
    if (test.status !== 'flaky') continue;
    flaky += 1;
    const first = test.results[0];
    const passedOn = test.results.findIndex((r) => r.status === 'passed');
    const lines = strip(first.error?.message ?? first.status).split('\n');
    const received = lines.find((line) => line.trim().startsWith('Received'));
    console.log(`${spec.file}:${spec.line} [${test.projectName}] ${titles.join(' > ')}`);
    console.log(`  passed on retry #${passedOn} after ${passedOn} failed attempt(s)`);
    console.log(`  first error: ${lines[0]}`);
    if (received) console.log(`  ${received.trim()}`);
  }
}

console.log(`\n${flaky} flaky of ${report.stats.expected + report.stats.unexpected + report.stats.flaky} tests`);
Output after the run above, one test shown:
export.spec.ts:7 [ui] export a monthly report
  passed on retry #1 after 1 failed attempt(s)
  first error: Error: expect(locator).toHaveText(expected) failed
  Received: "Export failed: Export service is warming up"

3 flaky of 6 tests
Save that output as a CI artifact, or post it to the pull request. A flaky test nobody sees is a bug nobody fixes.
Read the first attempt, not the last
The first failure is the evidence. A retry can fail for a different reason, as the next section shows, and a passing retry tells you nothing about why the first attempt failed.
Traces follow the same rule. trace: 'on-first-retry' records the retry, which may well pass. If you want the failed attempt itself, trace: 'retain-on-failure-and-retries' records every run and keeps both the failed attempt and its retries. With it, our flaky export test left two traces, one in export-export-a-monthly-report-ui and one in export-export-a-monthly-report-ui-retry1; with on-first-retry it left only the second. Recording every run costs CPU and disk, so many teams turn it on only for the job that hunts flakes. The trace viewer guide shows how to read one from a CI artifact.
Cleanup on retry with testInfo.retry
A retry runs in a fresh browser, but your server remembers the first attempt. This test creates a report and exports it. It has one retry and no cleanup:
import { test, expect } from '@playwright/test';

test.describe.configure({ retries: 1 });

// FAILS ON PURPOSE. The first attempt creates the report, then the export fails.
// The retry tries to create the same report again and trips over the leftover.
test('export a weekly report (no cleanup)', async ({ page }) => {
  await page.goto('/reports');
  await page.getByLabel('Report name').fill('Weekly sales');
  await page.getByRole('button', { name: 'Create report' }).click();
  await expect(page.getByRole('status')).toHaveText('Created: Weekly sales');

  await page.getByRole('listitem').filter({ hasText: 'Weekly sales' })
    .getByRole('button', { name: 'Export' }).click();
  await expect(page.getByRole('status')).toHaveText('Export ready: Weekly sales');
});
Both attempts fail, for different reasons (trimmed):
Error: expect(locator).toHaveText(expected) failed
Expected: "Export ready: Weekly sales"
Received: "Export failed: Export service is warming up"

Retry #1 ───────────────────────────────

Error: expect(locator).toHaveText(expected) failed
Expected: "Created: Weekly sales"
Received: "A report named \"Weekly sales\" already exists"
The retry never reached the export. If you read only the last error, you would chase a "duplicate name" bug that does not exist. The real problem, a slow export service, is in the first attempt.
The quickest fix uses testInfo.retry. On a retry, remove what the failed attempt left behind:
import { test, expect } from '@playwright/test';

test.describe.configure({ retries: 1 });

const name = 'Monthly sales';

test('export a monthly report', async ({ page, request }, testInfo) => {
  // On a retry, remove whatever the failed attempt left behind.
  // testInfo.retry is 0 on the first attempt, 1 on the first retry, and so on.
  if (testInfo.retry > 0) {
    await request.delete(`/api/reports/${encodeURIComponent(name)}`);
  }

  await page.goto('/reports');
  await page.getByLabel('Report name').fill(name);
  await page.getByRole('button', { name: 'Create report' }).click();
  await expect(page.getByRole('status')).toHaveText(`Created: ${name}`);

  await page.getByRole('listitem').filter({ hasText: name })
    .getByRole('button', { name: 'Export' }).click();
  await expect(page.getByRole('status')).toHaveText(`Export ready: ${name}`);
});
Now the retry gets past "Create report", and the test is reported as flaky with the real cause, the 503, in its first attempt.
A fixture is the better home for cleanup. Its teardown runs after every attempt, passed or failed, so the next attempt and the next test both start clean:
import { test as base, expect } from '@playwright/test';

// The fixture deletes the report after every attempt, passed or failed,
// so a retry always starts from a clean slate.
const test = base.extend<{ reportName: string }>({
  reportName: async ({ request }, use) => {
    const name = 'Quarterly sales';
    await use(name);
    await request.delete(`/api/reports/${encodeURIComponent(name)}`);
  },
});

test.describe.configure({ retries: 1 });

test('export a quarterly report', async ({ page, reportName }) => {
  await page.goto('/reports');
  await page.getByLabel('Report name').fill(reportName);
  await page.getByRole('button', { name: 'Create report' }).click();
  await expect(page.getByRole('status')).toHaveText(`Created: ${reportName}`);

  await page.getByRole('listitem').filter({ hasText: reportName })
    .getByRole('button', { name: 'Export' }).click();
  await expect(page.getByRole('status')).toHaveText(`Export ready: ${reportName}`);
});
Keep testInfo.retry for what teardown cannot cover. Teardown does not run when the worker process crashes, so a "delete if it exists" step at the start of a retry is a cheap backstop. testInfo.retry is also a good switch for extra diagnostics: log more or attach the server's state only on a retry, when you know the test has already failed once. The test data guide covers seeding and teardown in depth.
Retry one step, not the whole test
Sometimes waiting really is the expected behaviour: a background job, a cache that warms up, an eventually consistent search index. Retrying the whole test for that throws away a browser and repeats every step. Poll the one call instead, with a bound:
import { test, expect } from '@playwright/test';

test('the export API answers once it has warmed up', async ({ request }) => {
  const name = 'Daily sales';
  await request.post('/api/reports', { data: { name } });

  // Retry one call inside the test, with a bounded timeout, instead of retrying the whole test.
  await expect
    .poll(async () => {
      const response = await request.post(`/api/reports/${encodeURIComponent(name)}/export`);
      return response.status();
    }, { intervals: [250, 500, 1_000], timeout: 10_000 })
    .toBe(200);

  await request.delete(`/api/reports/${encodeURIComponent(name)}`);
});
This test passed in 284 ms: the first call got a 503, the second a 200. It runs in the api project, which has retries: 0, so if the export service never recovers, the test fails once, at the 10-second poll timeout. The error shows the last value it saw, such as Expected: 200 and Received: 404, and a call log line that says the timeout was exceeded while waiting on the predicate. expect.poll and expect(...).toPass() are for waits the product promises. Do not use them to paper over a race in the UI.
A retry policy that keeps retries honest
Retries are a measuring tool. They keep the pipeline moving while they collect evidence about which tests are unstable. Here is a policy you can adopt or adapt:
- Off locally, on in CI.
retries: process.env.CI ? 2 : 0. On your machine, a failure should stay a failure. - Zero where a retry is harmful. API tests, tests that pay, send email or change an account:
retries: 0on their project or group. - Never raise retries to fix a flake. Going from 2 to 5 makes the dashboard greener and the suite slower, and fixes nothing.
- Every flaky result is a bug report. Publish the flaky list from the JSON report on every CI run. Give each flaky test an owner and a deadline, or quarantine it in a job that does not block merges.
- Keep the evidence. Upload the HTML report and traces from every run. Use
on-first-retryas the default, andretain-on-failure-and-retrieswhile you hunt a specific flake. - Gate the main branch once it is clean. When the suite has gone a few weeks without a flaky result, add
--fail-on-flaky-teststo the test command in the job that runs on the main branch only. Pull-request jobs keep reporting flakes without failing, and the next flake that lands fails the first main build after it. To gate every CI run instead, setfailOnFlakyTests: !!process.env.CIin the config. - Prove fixes without retries.
--repeat-each=20 --retries=0, after checking that nodescribe.configureturns them back on.
Retries and Blendra
Blendra records end-to-end tests in Chrome and exports them as a Playwright project you own. The exported playwright.config.ts follows rule 1: retries: isCI ? 2 : 0 with trace: 'on-first-retry', plus HTML, JUnit and JSON reports in reports/. You can change those lines like any other code in the project.
When that suite runs in your CI, its reporter sends every attempt, and Blendra keeps one result per test: the final attempt. So a test that failed and then passed on a CI retry shows as passed in Blendra, and CI runs have no "passed on retry" list (Diagnose failures). For retry detail from CI, keep using Playwright's own HTML or JSON report. When a test does fail, Blendra checks its earlier results. It calls the test flaky when its five newest results changed status at least twice, it has at least three passed or failed results, and more than 20% but less than 80% of its recent passed and failed results were failures (Flaky tests). Sending CI results to Blendra needs an API token, which comes with Pro and above (pricing).
FAQ
How many retries should I use in CI?
One or two. One retry is enough to sort "failed once" from "fails every time". A second one helps when CI machines are noisy. Beyond that, each extra retry mostly adds minutes to a test that is going to fail anyway.
Does a retry reuse the same browser or page?
No. The worker process that ran the failed attempt is thrown away, so the retry gets a new browser, context and page. beforeAll hooks and worker fixtures run again. Only state outside the test process, such as your database or server, carries over.
Why didn't --retries=0 turn retries off?
Because test.describe.configure({ retries }) in the test file wins over the command line. Remove it from the file while you verify a fix, or check the output for (retry #1) lines.
How do retries work in pytest-playwright and Cypress?
pytest-playwright has no retry option of its own. Teams usually add the pytest-rerunfailures plugin, which adds a --reruns option and a flaky marker, and reports retried tests as "rerun" in the summary. Cypress has built-in retries with separate values for cypress run and cypress open (Test Retries). The Cypress flaky tests guide covers that side, and Playwright with pytest covers the Python setup.