Blog / Flaky tests and debugging
Flaky tests and debugging
Flaky Playwright Tests: Find the Cause, Fix It, Prove It's Fixed
A field guide to flaky Playwright tests, organised by the error you are staring at, with a loop that proves the fix holds.
Flaky Playwright tests are rarely mysterious. The error message usually points to one of a handful of causes, and Playwright can reproduce the failure on demand. This guide is organised by the error you are looking at, with the failing code, the fixed code and the command that proves the fix holds.
Every example ran on Playwright 1.61 against a small fake app that a fixture serves from the test process. That is why the examples import test and expect from ./shop, and why the config's baseURL is http://shop.test. Snippets that start at test( go in a spec file that begins with that import. In your own suite, import from @playwright/test as usual.
TL;DR: five rules
- No fixed waits. Wait for the state you need with a web-first assertion, not for a number of milliseconds.
- One match per locator. A strict mode violation means the locator is ambiguous. Scope it to a row, a dialog or a region.
- Each test owns its data. Parallel tests that share an account or a record will collide, sooner or later.
- Retries are a signal. Turn them on in CI to collect evidence, then treat every "flaky" label as a bug report.
- Prove the fix with repeats. Run the test 20 or more times with retries off and more workers than CI uses.
What flaky Playwright tests are, and what they are not
A flaky test passes and fails against the same code. Nothing you control changed between the green run and the red one. Playwright uses a narrower, mechanical definition in its retries guide: a test is "flaky" when it failed on the first attempt and passed on a retry.
Some failures look flaky but are not:
- A test that is always red is broken, not flaky. Fix it or delete it.
- A test that fails while staging is down is reporting an outage. Retrying it hides the outage.
- A test that fails only on Mondays, or after midnight UTC, depends on the date. Pin the time to a Monday, or to just after midnight UTC, with
page.clockand it fails every time, which makes it an ordinary bug.
The fixes below are for real flakiness: a race between your test and your app, or between two tests.
Step 1: reproduce the flake on purpose
You cannot fix what you cannot see fail. Run the suspect test many times, with retries off, under more parallel load than usual:
npx playwright test tests/checkout.spec.ts --repeat-each=20 --retries=0 --workers=4--repeat-each=20runs every test in the file 20 times.--retries=0makes sure a failure is reported as a failure, not quietly retried.--workers=4runs the copies in parallel. Parallel copies of the same test fight over CPU, and over shared data if there is any.
Copies from --repeat-each already spread across workers. Add fullyParallel: true to the config (or pass --fully-parallel) so the other tests in the same file run at the same time too. Then each copy competes with its neighbours, which is where shared-state flakes show up.
If the failure only shows up in CI, make your machine more like CI. In Chromium you can slow the page's CPU down through the DevTools Protocol:
import { test, expect } from './shop';

// Chromium only: slow the page's CPU down 4x to get closer to a busy CI runner.
test('settings save on a slow CPU', async ({ page, browserName }) => {
  test.skip(browserName !== 'chromium', 'CPU throttling uses the Chrome DevTools Protocol');

  const cdp = await page.context().newCDPSession(page);
  await cdp.send('Emulation.setCPUThrottlingRate', { rate: 4 });

  await page.goto('/settings');
  await page.getByRole('button', { name: 'Save' }).click();
  await expect(page.getByRole('status')).toHaveText(/saved/i);
});
When the test fails at least once in 20 runs, you have a reproduction. Keep the command. You will run it again at the end to prove the fix.
Step 2: read the error, then the trace
Read the first error line and the call log under it before you open anything else. Playwright's messages are specific. The table maps the four this guide covers to their usual cause and fix.
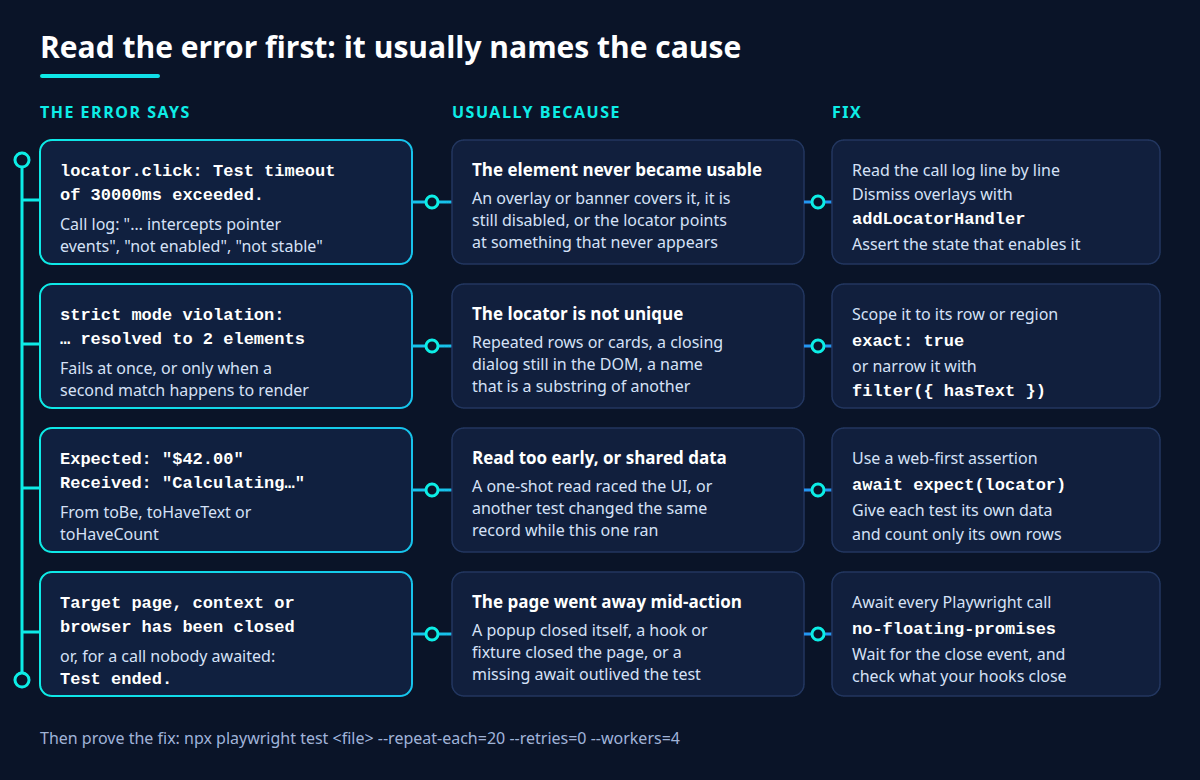
When the message is not enough, open the trace. It records every action, a DOM snapshot before and after each one, the console and the network. The Playwright trace viewer guide walks through reading one from a CI artifact.
Cause 1: fixed waits that race the UI
This is the classic flaky test. The save button calls an API that answers in one to three seconds, and the test guesses two:
// The flaky version. Do not copy this one.
test('settings save, with a fixed wait', async ({ page }) => {
  await page.goto('/settings');
  await page.getByRole('button', { name: 'Save' }).click();
  await page.waitForTimeout(2000);

  // textContent() reads once. If the save took longer than 2 s, this reads "Saving…".
  expect(await page.getByRole('status').textContent()).toBe('Saved');
});
Run 20 times with --retries=0, this test failed in about half the runs or more (10 to 14 of 20 in our batches), which is what you would expect from a two-second guess against a one-to-three-second delay. Each failure looked like this:
Error: expect(received).toBe(expected) // Object.is equality

Expected: "Saved"
Received: "Saving…"
The trouble is the combination of a fixed wait and a one-shot read. textContent() reads the page once and hands back whatever is there at that moment. The Playwright API docs are blunt about the wait itself: "Tests that wait for time are inherently flaky" (page.waitForTimeout).
The fix is a web-first assertion. It retries until the text matches or the expect timeout runs out (5 seconds by default):
test('settings save shows a confirmation', async ({ page }) => {
  await page.goto('/settings');
  await page.getByRole('button', { name: 'Save' }).click();

  // Retries until the text matches or the expect timeout (5 s by default) runs out.
  await expect(page.getByRole('status')).toHaveText(/saved/i);
});
This version passed 20 out of 20, and it stops waiting as soon as the text appears. A waitForTimeout(2000) followed by a web-first assertion is not flaky, just two seconds slower for no reason.
When you need the response itself, start waiting before the click that triggers the request:
test('placing an order returns an order id', async ({ page }) => {
  await page.goto('/checkout');

  // Start waiting before the click that triggers the request.
  const response = page.waitForResponse('**/api/orders');
  await page.getByRole('button', { name: 'Place order' }).click();
  const order = await (await response).json();

  expect(order.id).toBe(42);
  await expect(page.getByRole('status')).toHaveText('Order 42 placed');
});
If you write click() first and waitForResponse() second, a fast response can arrive before the listener exists. The test then waits for a response that has already come and gone, and fails with page.waitForResponse: Test timeout of 5000ms exceeded. (5 seconds was the demo's test timeout). In three batches of 20 runs against the fake app, the late version failed 0, 12 and 1 times (your counts will differ). A batch with zero failures is how this bug gets through code review.
waitForLoadState('networkidle') is not a fix either. Playwright's API docs mark networkidle as discouraged and tell you to rely on web assertions instead (page.goto). Apps with polling, analytics or websockets may never go idle. The auto-waiting guide covers what Playwright already waits for on every action.
Cause 2: locators that match more than one element
A strict mode violation means Playwright found more than one candidate and will not pick one for you. Here is the real output for a table with two "Delete" buttons:
Error: locator.click: Error: strict mode violation: getByRole('button', { name: 'Delete' }) resolved to 2 elements:
    1) <button type="button">Delete</button> aka getByRole('row', { name: 'Invoice 41 $18.00 Delete' }).getByRole('button')
    2) <button type="button">Delete</button> aka getByRole('row', { name: 'Invoice 42 $42.00 Delete' }).getByRole('button')
Why is this a flake? The second match is often there only some of the time: a dialog still animating out, a list still loading, or a toast from the previous step. The test passes when the page has one match and fails when it has two.
Scope the locator to the thing you mean. The error even suggests how:
test('delete invoice 42', async ({ page }) => {
  await page.goto('/invoices');
  const row = page.getByRole('row', { name: 'Invoice 42' });
  await row.getByRole('button', { name: 'Delete' }).click();

  await expect(page.getByRole('status')).toHaveText('Invoice 42 deleted');
  await expect(row).toHaveCount(0);
  await expect(page.getByRole('row', { name: 'Invoice 41' })).toBeVisible();
});
page.getByRole('row').filter({ hasText: 'Invoice 42' }) works the same way. Two more traps:
- Accessible names match as a case-insensitive substring by default.
{ name: 'Save' }also matches "Save draft". Addexact: truewhen the names overlap. - Do not "fix" strict mode with
.first(). It takes whichever match comes first in the DOM at that moment, which is the original race with a new name.
The locators guide ranks locator types by how well they survive redesigns.
Cause 3: tests that share state
Tests that pass alone and fail together usually share something: a user account, a cart, a "first project in the list". With fullyParallel and four workers, two tests edit the same record at the same moment. The error is an assertion that sees someone else's data, such as toHaveCount expecting 1 and receiving 2, or toHaveText showing another test's value.
Give each test its own data, and assert only on that data:
import { randomUUID } from 'node:crypto';
import { test as base, expect } from './shop';

// Every test gets its own project name, so parallel tests never fight over the same record.
const test = base.extend<{ projectName: string }>({
  projectName: async ({}, use, testInfo) => {
    await use(`e2e-${testInfo.parallelIndex}-${randomUUID().slice(0, 8)}`);
  },
});

test('create a project', async ({ page, projectName }) => {
  await page.goto('/projects');
  await page.getByLabel('Project name').fill(projectName);
  await page.getByRole('button', { name: 'Create project' }).click();

  const projects = page.getByRole('list', { name: 'Projects' });
  await expect(projects.getByRole('listitem').filter({ hasText: projectName })).toHaveCount(1);
});
Rules that follow from this:
- Never assert totals on shared lists. "The list has 3 items" breaks as soon as another test adds one. "My item is in the list" does not.
- One account per worker when tests change account settings.
testInfo.parallelIndexis a stable index per worker slot, which makes it a good key for a pool of test users. - No order dependence. If test B only passes after test A, B fails whenever it runs first, alone, or on a retry in a fresh worker. If the steps really are one story, put them in one test.
The test data guide covers seeding through the API and cleaning up after a run.
Cause 4: things that move or disappear
Before a click, Playwright checks that the element is visible, stable, enabled and receives events (actionability). When one of those never becomes true, the call log says which. This is the trimmed log from a click blocked by a consent banner that appears on some page loads and not others:
Error: locator.click: Test timeout of 5000ms exceeded.
Call log:
  - waiting for getByRole('button', { name: 'Export report' })
    - locator resolved to <button id="export" type="button">Export report</button>
  - attempting click action
    2 × waiting for element to be visible, enabled and stable
      - element is visible, enabled and stable
      - scrolling into view if needed
      - done scrolling
      - <div id="cookies" role="dialog" aria-label="Cookies">…</div> intercepts pointer events
The banner shows up on about half the page loads, so it blocked the click in about half of 20 runs. For overlays you cannot control, page.addLocatorHandler dismisses them whenever they get in the way. Toasts are the other half of this cause. Assert them immediately after the action that shows them, because they remove themselves:
import { test, expect } from './shop';

test.beforeEach(async ({ page }) => {
  // Whenever the cookie banner shows up and blocks an action, dismiss it, then carry on.
  await page.addLocatorHandler(page.getByRole('dialog', { name: 'Cookies' }), async (banner) => {
    await banner.getByRole('button', { name: 'Reject all' }).click();
  });
});

test('export shows a toast', async ({ page }) => {
  await page.goto('/dashboard');
  await page.getByRole('button', { name: 'Export report' }).click();

  // Assert the toast straight after the action that shows it: it hides itself after 1.5 s.
  await expect(page.getByRole('status')).toHaveText('Report exported');
  // And prove it goes away, instead of sleeping until it does.
  await expect(page.getByRole('status')).toBeEmpty();
});
With the handler in place, the test passed 20 out of 20. For lists that re-render or re-sort, keep using locators: a locator finds the element again on every attempt, while a value stored in a variable goes stale. Testing toast messages goes deeper on timing.
The fourth error in the table belongs here too. Target page, context or browser has been closed means the page went away while an action was waiting on it. Usually a popup closed itself, a hook or fixture closed the page, or the browser crashed. If the error instead reads locator.click: Test ended., a call was not awaited and the test finished without it. Playwright's best practices recommend the @typescript-eslint/no-floating-promises lint rule to catch missing awaits.
Cause 5: the environment
Some tests pass locally and fail in CI with no code involved:
- Slower CPUs. CI runners are often smaller and busier than your laptop. Tests that wait for state shrug this off; tests that wait for time break.
- Cold starts. A freshly started app can answer its first request slowly. Warm it up in global setup, or wait for a health endpoint.
- Third-party scripts. Chat widgets, A/B tests and consent banners load at different speeds, or not at all. Block them with
page.routeor handle them as in cause 4. Only test what you control. - Different worker counts. The example config in Playwright's configuration docs sets
workers: process.env.CI ? 1 : undefined, so your laptop runs in parallel while CI runs serially. Shared-state bugs show up wherever the parallelism is.
Timeouts should match reality. The defaults are 30 seconds per test and 5 seconds per assertion (timeouts). If a report really takes 12 seconds to generate, give that one assertion { timeout: 15_000 }. A bigger global timeout does not fix a race. It only makes the failures slower.
Retries: a useful signal, a bad fix
Retries are how you find flaky tests at scale. They are not how you fix them. This config retries only in CI and records a trace when it does:
import { defineConfig, devices } from '@playwright/test';

export default defineConfig({
  testDir: './tests',
  fullyParallel: true,
  forbidOnly: !!process.env.CI,
  // Retries only in CI. Locally a failure should stay a failure.
  retries: process.env.CI ? 2 : 0,
  reporter: [['list'], ['html', { open: 'never' }]],
  use: {
    baseURL: 'http://shop.test',
    // Record a trace on the first retry of a failed test.
    trace: 'on-first-retry',
  },
  projects: [{ name: 'chromium', use: { ...devices['Desktop Chrome'] } }],
});
After a failure, Playwright throws away the worker process and retries the test in a fresh one. A test that fails first and passes on a retry is reported as flaky in the list output and the HTML report. Here is the summary from one run of the fixed-wait test with --repeat-each=10 --retries=2 (test names trimmed):
  2 failed
  3 flaky
  5 passed (13.8s)
Three things to know:
trace: 'on-first-retry'records the retry, not the first failure. If you want the failing attempt itself,retain-on-failurerecords every run and keeps the failed ones, at the cost of more CPU and disk (trace modes).--fail-on-flaky-testsmakes a run exit non-zero when any test was flaky. It is a strict but honest gate for a main branch.- Sometimes the flake is in the app, not the test. A double-submit bug or a missing loading state shows up as flakiness first.
The retries guide covers reading retry results across many runs.
Quarantine without losing the test
Sometimes you cannot fix a flake today, and it is blocking everyone's pull requests. Quarantine it, but keep it visible and keep it running:
import { test, expect } from './shop';

test(
  'checkout total',
  {
    tag: '@flaky',
    annotation: [
      { type: 'issue', description: 'https://github.com/your-org/shop/issues/1234' },
      { type: 'owner', description: 'payments team' },
      { type: 'revisit', description: '2026-11-15' },
    ],
  },
  async ({ page }) => {
    await page.goto('/checkout');
    await expect(page.getByTestId('total')).toHaveText('$42.00');
  },
);
Then split the CI run in two:
# Blocking job: everything except quarantined tests
npx playwright test --grep-invert @flaky

# Non-blocking job: only quarantined tests, no retries, so you keep collecting failures
npx playwright test --grep @flaky --retries=0
The annotations show up in the HTML report, so anyone who opens the test sees the ticket, the owner and the date (annotations). Two shortcuts to avoid. test.fixme() stops the test from running, so you lose the data that tells you when it is fixed. test.fail() expects the test to fail, which is wrong for a test that passes half the time. Set a limit too, such as two sprints to fix or delete it, or the quarantine job becomes a graveyard.
Prove it's fixed
Run the command from step 1 again, with the fix in place:
npx playwright test tests/checkout.spec.ts --repeat-each=20 --retries=0 --workers=4With the fixes in place, the whole example suite ran 11 tests 20 times each with zero failures. How many repeats you need depends on how flaky the test was (see the FAQ).
How Blendra helps
Blendra records end-to-end tests in your own Chrome and exports them as Playwright code. Three parts of it are aimed at this problem.
- Flaky is judged from history, not from one run. When a test fails, Blendra looks at its earlier results, up to the 20 newest. It calls the test flaky when its 5 newest results changed status at least twice, it has at least 3 passed or failed results, and more than 20% but less than 80% of those results were failures. A failure with a clearer cause, such as changed page text, keeps that cause, with the history added as evidence (Flaky tests).
- Every failure gets a cause. Each failed test gets an owner, a confidence and one next step. A strict mode report becomes "This step now matches 2 elements" (the count comes from Playwright's error), owned by Test needs repair, with Certain confidence and a Repair locator… next step. Causes are rule-based, use no AI and are free on every plan (Diagnose failures).
- Recorded steps keep their alternates. Each step stores the locator Blendra ranked first plus the alternates recorded with it. The exported step combines it with up to four of those alternates, the ones safe to use at run time, through Playwright's
locator.or(), and a repair only offers locators recorded for that same step.
Results from your own CI reach Blendra through the reporter in the exported suite. That needs an API token, which comes with Pro and above. See pricing.
FAQ
Why does my Playwright test pass locally and fail in CI?
Usually one of three things: a slower machine, a different worker count, or a fresh database and a cold app. Reproduce it with --repeat-each and more workers, throttle the CPU, and read the CI trace instead of guessing.
Should I wait for networkidle?
No. Playwright's docs discourage it for testing. Apps that poll or keep a websocket open may never become idle, and an idle network still does not mean the UI has rendered. Assert the state you need with expect(locator).
Are retries acceptable?
Yes, in CI, as a way to keep the pipeline moving while you collect evidence. Not as the fix. Track flaky results and treat each one as a bug. Consider --fail-on-flaky-tests on your main branch once the suite is stable.
How many repeats prove a fix?
It depends on how often it failed before. If the test failed 1 run in 10, a still-broken test passes 20 runs in a row about 12% of the time (0.9 to the power of 20), and 50 runs in a row about 0.5% of the time. A handy rule: zero failures in N runs puts the true failure rate below roughly 3 in N, with 95% confidence. For a test that failed once in 50, run a few hundred repeats, or run it nightly for a week.