CI/CD
Playwright in GitLab CI: Docker Image, Reports and Parallel Jobs
A complete .gitlab-ci.yml for Playwright, with the image, caching, test reports and sharding explained line by line.
Running Playwright in GitLab CI takes three decisions: which Docker image the job runs in, which reports GitLab should pick up, and how to split the suite across parallel jobs. This guide builds a complete .gitlab-ci.yml one piece at a time and explains each line, including the traps that only show up once a pipeline is red.
Everything below was checked on 22 October 2026 with @playwright/test 1.64.1 (the latest npm release that day) and Playwright for Python 1.64.0. Each .gitlab-ci.yml validates against GitLab's CI schema, and the pipelines were replayed locally in the same Docker images with GitLab's predefined variables, parallel copies, cache and artifacts. They were not run on gitlab.com, so what the GitLab interface shows comes from GitLab's linked documentation.
Key takeaways
- Use
mcr.microsoft.com/playwright:v<version>-nobleand pin the tag to the exact@playwright/testversion inpackage-lock.json. When the image's browser builds differ from the ones your version needs, every test fails with "Executable doesn't exist". artifacts:reports:junitputs a test summary in the merge request. Writejunit.xmlat the project root, or the screenshot links in it point nowhere.- Turn on
includeProjectInTestNamewhen the same test runs in several browsers. GitLab keeps only the first test with a given name. - Keep the HTML report with
artifacts:pathsandwhen: always.expose_asadds a link to it in the merge request. parallel: 4plus--shard=$CI_NODE_INDEX/$CI_NODE_TOTALsplits the suite. A second-stage job merges the blob reports into one HTML report.
Pick the image and pin it to your Playwright version
Microsoft publishes a Playwright Docker image with Node.js, the browsers and their system libraries already installed. The tag has two parts: the Playwright version and the Ubuntu release.
| Tag | Base |
|---|---|
mcr.microsoft.com/playwright:v1.64.1-noble |
Ubuntu 24.04 LTS |
mcr.microsoft.com/playwright:v1.64.1-jammy |
Ubuntu 22.04 LTS |
mcr.microsoft.com/playwright:v1.64.1-resolute |
Ubuntu 26.04 LTS |
The v1.64.1-noble image we tested ships Node.js 24.21.0 and npm 11.19.0, and runs as root. Running as root turns off Chromium's sandbox, which Playwright's Docker docs call acceptable for your own end-to-end tests but not for crawling untrusted sites. There is no Alpine variant, because the Firefox and WebKit builds need glibc.
The version-mismatch trap
Each Playwright release expects specific browser builds, listed in playwright-core/browsers.json. Your tests use whatever version npm ci installs from the lockfile. When the image's builds are not the ones that version expects, Playwright looks for browser folders the image does not have. Patch releases often share builds: a project locked to 1.64.0 passed in the v1.64.1 image, because both use Chromium build 1248. The version number does not tell you which bumps change the builds, though, so pin the exact version.
Read the version from the lockfile, not from the range in package.json:
npm ls @playwright/test
# playwright-gitlab-ci-example@ /builds/demo/shop
# └── @playwright/test@1.64.1
To see the failure for real, we ran the same project, locked to 1.64.1, in the older v1.61.1-noble image. Every test failed on all three attempts, and each failure carried this message:
Error: browserType.launch: Executable doesn't exist at /ms-playwright/chromium_headless_shell-1248/chrome-headless-shell-linux64/chrome-headless-shell
╔════════════════════════════════════════════════════════╗
║ Looks like Playwright was just updated to 1.64.1.      ║
║ Please update docker image as well.                    ║
║ -  current: mcr.microsoft.com/playwright:v1.61.1-noble ║
║ - required: mcr.microsoft.com/playwright:v1.64.1-noble ║
║                                                        ║
║ <3 Playwright Team                                     ║
╚════════════════════════════════════════════════════════╝
The message names the tag you need. The fix is a habit: bump @playwright/test and the image tag in the same merge request. Avoid the floating tags the registry also offers, such as latest and noble. They move under you, and the day they move, your pipeline breaks without a code change.
The image settles two more things. You do not need npx playwright install --with-deps, because the browsers and libraries are already there. And shared memory is less of a worry: Playwright's Docker docs recommend --ipc=host for Chromium, which you rarely control on a shared runner, but Playwright 1.64.1 starts Chromium with --disable-dev-shm-usage by default, and our replay ran with Docker's default shared memory without a crash.
A minimal Playwright job in GitLab CI
This is the smallest job that works:
e2e:
  image: mcr.microsoft.com/playwright:v1.64.1-noble
  script:
    - npm ci
    - npx playwright test
There is no stages: list, so the job lands in GitLab's default test stage. GitLab sets CI=true in every job, and that is the switch most Playwright configs read. In our replay the job printed:
$ npm ci
added 5 packages, and audited 6 packages in 863ms
$ npx playwright test
Running 8 tests using 1 worker
········
  8 passed (2.1s)
npm ci needs a committed package-lock.json. Without one it stops before installing anything:
npm error The `npm ci` command can only install with an existing package-lock.json or
npm error npm-shrinkwrap.json with lockfileVersion >= 1.
The Playwright config for GitLab CI
The config decides which reports exist, so it comes before the YAML that collects them. This one runs locally with the usual list and HTML reporters, and switches to CI reporters when CI is set:
// playwright.config.ts
import { defineConfig, devices, type ReporterDescription } from '@playwright/test';

// GitLab sets CI=true in every job. CI_NODE_TOTAL is the number of copies of a
// job started with `parallel:`, and 1 for a job without it.
const isCI = !!process.env.CI;
const sharded = Number(process.env.CI_NODE_TOTAL ?? '1') > 1;

// A sharded job writes a blob report for the merge job; a single job writes HTML directly.
const report: ReporterDescription = sharded ? ['blob'] : ['html', { open: 'never' }];

export default defineConfig({
  testDir: './tests',
  fullyParallel: true,
  forbidOnly: isCI,
  retries: isCI ? 2 : 0,
  workers: isCI ? 1 : undefined,
  reporter: isCI
    ? [
        ['dot'],
        // At the project root: GitLab resolves the screenshot links in this file
        // from the project directory, and Playwright writes them relative to the file.
        // The project prefix keeps names unique when the same test runs in several browsers.
        ['junit', { outputFile: 'junit.xml', includeProjectInTestName: true }],
        report,
      ]
    : [['list'], ['html']],
  use: {
    baseURL: process.env.BASE_URL ?? 'http://127.0.0.1:4173',
    trace: 'on-first-retry',
    screenshot: 'only-on-failure',
  },
  // Starts the demo app; point BASE_URL at a deployed environment to skip it.
  webServer: process.env.BASE_URL
    ? undefined
    : {
        command: 'node fixture/server.mjs',
        url: 'http://127.0.0.1:4173',
        reuseExistingServer: !isCI,
      },
  projects: [{ name: 'chromium', use: { ...devices['Desktop Chrome'] } }],
});
A few choices worth explaining:
workers: 1in CI follows the Playwright CI guide, which favours stability on shared runners and suggests sharding for more speed. Raise it once your runs are stable and the runner has spare cores.dotkeeps the job log short. It is also Playwright's default reporter on CI, but listing reporters replaces the default, so it has to be named.- The HTML reporter never opens a browser when
CIis set.open: 'never'covers runners where it isn't. BASE_URLlets the same suite run against a review app or staging. Without it,webServerstarts the demo app inside the job.
Test reports in merge requests (JUnit)
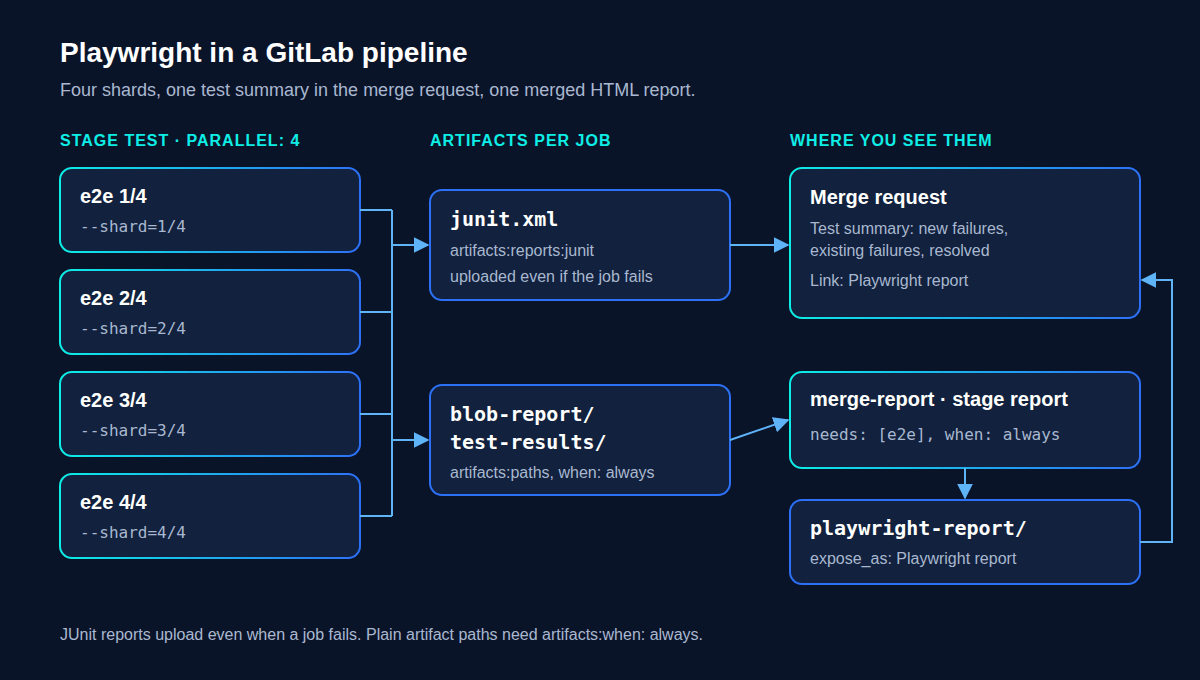
GitLab reads JUnit XML through artifacts:reports:junit. The merge request then shows a test summary that compares the branch with the target branch: newly failed tests, newly encountered errors, existing failures and resolved failures. The pipeline gets a Tests tab with every suite and test case.
# Fragment: add to the e2e job
  artifacts:
    reports:
      junit: junit.xml
Report artifacts upload whether the job passed or failed. GitLab's documented limits: files must end in .xml, each must be under 30 MB, and a job's JUnit files must total under 100 MB. Use a file name or a pattern, not a directory.
Two details of Playwright's JUnit output matter here.
Duplicate names across browsers
Playwright's JUnit reporter uses the spec file as classname and the describe blocks plus the title as name. The browser only appears as the hostname of the testsuite element, which GitLab does not display. We ran one spec in Chromium and Firefox, and the two suites contained identical test cases:
<testsuite name="cart.spec.ts" ... hostname="chromium" tests="3" ...>
<testcase name="starts empty" classname="cart.spec.ts" time="0.119">
...
<testsuite name="cart.spec.ts" ... hostname="firefox" tests="3" ...>
<testcase name="starts empty" classname="cart.spec.ts" time="1.242">
GitLab's docs say that with duplicate names only the first test is used, so a Firefox-only failure could vanish from the summary. The includeProjectInTestName option, off by default, prefixes each name with its project:
<testcase name="[chromium] starts empty" classname="cart.spec.ts" time="0.12">
<testcase name="[firefox] starts empty" classname="cart.spec.ts" time="0.833">
Screenshot links, and why junit.xml sits at the root
GitLab can show a screenshot in a failed test's details when the test case's system-out contains [[ATTACHMENT|path]], with the path relative to the project directory. Playwright already writes those lines for every attachment. It writes the paths relative to the folder of the XML file, though, not the project.
With outputFile: 'junit.xml', a failing test produced:
[[ATTACHMENT|test-results/cart-counts-items-added-chromium/test-failed-1.png]]With reports/junit.xml, the same failure produced:
[[ATTACHMENT|../test-results/cart-counts-items-added-chromium/test-failed-1.png]]The second path climbs out of the project directory, where GitLab looks. Keep the file at the root, and upload test-results/ as an artifact too, because the link only works if the file was uploaded.
HTML report as an artifact
The JUnit summary tells you what failed. The HTML report, with its traces and screenshots, tells you why. Keep it with artifacts:paths:
e2e:
  image: mcr.microsoft.com/playwright:v1.64.1-noble
  cache:
    key:
      files:
        - package-lock.json
    paths:
      - .npm/
  script:
    - npm ci --cache .npm --prefer-offline
    - npx playwright test
  artifacts:
    when: always
    expire_in: 2 weeks
    expose_as: Playwright report
    reports:
      junit: junit.xml
    paths:
      - playwright-report/
      - test-results/
when: alwaysmatters here. Plain artifact paths upload only on success by default, and a report from a green run is the one you need least.expose_asadds a link named "Playwright report" to the merge request. GitLab allows it once per job and on at most 10 jobs per merge request, and does not accept glob patterns. With more than one path, the link opens the artifact browser.expire_inkeeps storage in check. Without it, the instance's default applies.
To read the report, download the job's artifacts and serve the folder locally:
npx playwright show-report playwright-reportGitLab previews .html artifacts in the browser only when GitLab Pages is enabled for the instance, and private projects also need Pages access control (job artifacts docs), so treat that view as a bonus.
Cache npm downloads, not node_modules
npm ci deletes node_modules before it installs, so caching it buys nothing. Cache npm's download folder inside the project directory, as GitLab's caching examples do: npm ci --cache .npm --prefer-offline with .npm/ as the cached path. Keying on package-lock.json gives a fresh cache whenever dependencies change. The cache is best effort: GitLab's docs warn that it is not guaranteed, and by default it lives on one runner's machine.
Parallel jobs and sharding
GitLab's parallel keyword starts N copies of a job, named e2e 1/4 to e2e 4/4. Each copy gets CI_NODE_INDEX (from 1) and CI_NODE_TOTAL, which is exactly the x/y format Playwright's --shard flag expects:
# Fragment: the full file is below
e2e:
  parallel: 4
  script:
    - npm ci --cache .npm --prefer-offline
    - npx playwright test --shard=$CI_NODE_INDEX/$CI_NODE_TOTAL
In our replay each copy announced its slice, for example Running 2 tests using 1 worker, shard 1 of 4. JUnit needs nothing extra: every job uploads its own junit.xml and GitLab combines all of a pipeline's reports. Expect the test durations in the Tests tab to add up to more than the pipeline's wall time, because they are summed across parallel jobs.
The HTML report does need extra work. Four separate reports would be four partial views, so the config writes a blob report when CI_NODE_TOTAL is above 1, and a job in the next stage merges them:
needs: [e2e]on a parallel job waits for every copy and downloads all their artifacts. Files with the same name overwrite each other. Blob files are named per shard (report-1.ziptoreport-4.zip), so they land side by side. The duplicatejunit.xmlfiles overwrite each other harmlessly; the merge job does not use them.when: alwayslets the merge run after a failed shard. That is the run you will open the report for.
We made one test fail on purpose and replayed the full pipeline. Shard 1 exited with status 1, shards 2 to 4 passed, and the merge job still extracted all four blobs and built one report:
$ npx playwright merge-reports --config merge.config.ts ./blob-report
merging reports from /builds/demo/shop/blob-report
extracting: blob-report/report-1.zip
extracting: blob-report/report-2.zip
extracting: blob-report/report-3.zip
extracting: blob-report/report-4.zip
merging events
To run several browsers, Playwright's CI guide also shows parallel:matrix with a PROJECT list and a SHARD list, passed as --project=$PROJECT --shard=$SHARD. Choosing the shard count is covered in Playwright sharding.
The complete .gitlab-ci.yml
# .gitlab-ci.yml
# Playwright in GitLab CI: 4 parallel jobs, JUnit results in merge requests,
# and one merged HTML report.
stages:
  - test
  - report

default:
  # Pin the tag to the @playwright/test version in package-lock.json.
  # Mismatched browser builds mean missing browsers. Bump both in one merge request.
  image: mcr.microsoft.com/playwright:v1.64.1-noble
  # npm's download cache, keyed on the lockfile. It must live inside the project
  # directory, because GitLab only caches paths there.
  cache:
    key:
      files:
        - package-lock.json
    paths:
      - .npm/
  # Cancel this pipeline's jobs when a newer commit lands on the same branch.
  interruptible: true
  # Retry a job only when the runner itself broke. Playwright retries tests.
  retry:
    max: 1
    when: runner_system_failure

e2e:
  stage: test
  parallel: 4
  timeout: 30 minutes
  script:
    - npm ci --cache .npm --prefer-offline
    - npx playwright test --shard=$CI_NODE_INDEX/$CI_NODE_TOTAL
  artifacts:
    # Keep the files of failed jobs too: that is when you need them.
    when: always
    expire_in: 1 week
    reports:
      junit: junit.xml
    paths:
      - blob-report/
      # Screenshots and traces; junit.xml links to the screenshots in here.
      - test-results/

merge-report:
  stage: report
  # Run even when a shard failed.
  when: always
  # Waits for all 4 e2e jobs and downloads their artifacts.
  needs: [e2e]
  script:
    - npm ci --cache .npm --prefer-offline
    - npx playwright merge-reports --config merge.config.ts ./blob-report
  artifacts:
    when: always
    expire_in: 2 weeks
    expose_as: Playwright report
    paths:
      - playwright-report/
And the merge config it points to:
// merge.config.ts
// Used only by `playwright merge-reports --config merge.config.ts`.
// testDir lets blobs recorded in different checkout paths merge into one report.
export default {
  testDir: 'tests',
  reporter: [['html', { open: 'never' }]],
};
Blobs store absolute test paths. If your runners check out to different directories, a plain merge refuses to run, and the testDir in the merge config is the fix. The other choices in the file:
image,cache,interruptibleandretrysit underdefault:. GitLab has deprecated definingimage,services,cache,before_scriptandafter_scriptat the top level, and points todefaultinstead.interruptible: truesuits test jobs. GitLab's docs warn against it for deployment jobs, which should not stop halfway.
Python variant
Playwright for Python has its own image, mcr.microsoft.com/playwright/python, with its own tags. Pin it to playwright in requirements.txt. As of 22 October 2026 the newest Python tag was v1.64.0, one patch behind npm's 1.64.1, so do not copy the version from your TypeScript pipeline.
# requirements.txt
playwright==1.64.0
pytest==9.1.1
pytest-playwright==0.10.0
# .gitlab-ci.yml
default:
# The Python image has its own tags. Pin it to `playwright` in requirements.txt.
image: mcr.microsoft.com/playwright/python:v1.64.0-noble
variables:
# pip's cache must live inside the project directory for GitLab to cache it.
PIP_CACHE_DIR: "$CI_PROJECT_DIR/.cache/pip"
e2e:
stage: test
parallel: 2
cache:
key:
files:
- requirements.txt
paths:
- .cache/pip/
script:
- pip install -r requirements.txt
- pytest --junitxml=junit.xml --screenshot only-on-failure --output test-results
artifacts:
when: always
expire_in: 1 week
reports:
junit: junit.xml
paths:
- test-results/The image has Python 3.12 and pip but no Playwright package, so pip install brings the version you pinned. pytest has no built-in sharding. Rather than add a plugin, a short hook in conftest.py keeps every Nth test for each job:
# conftest.py
import os
import threading
from functools import partial
from http.server import SimpleHTTPRequestHandler, ThreadingHTTPServer
from pathlib import Path

import pytest

SITE = Path(__file__).parent / "site"


class QuietHandler(SimpleHTTPRequestHandler):
    def log_message(self, format, *args):  # keep the CI log readable
        pass


@pytest.fixture(scope="session")
def base_url():
    # Point BASE_URL at a deployed environment, or serve the demo page locally.
    if os.environ.get("BASE_URL"):
        yield os.environ["BASE_URL"]
        return
    server = ThreadingHTTPServer(("127.0.0.1", 0), partial(QuietHandler, directory=str(SITE)))
    threading.Thread(target=server.serve_forever, daemon=True).start()
    yield f"http://127.0.0.1:{server.server_port}"
    server.shutdown()


def pytest_collection_modifyitems(config, items):
    # GitLab `parallel: N` sets CI_NODE_INDEX (1..N) and CI_NODE_TOTAL.
    # Keep every Nth test for this job, so N jobs split the suite between them.
    total = int(os.environ.get("CI_NODE_TOTAL", "1"))
    index = int(os.environ.get("CI_NODE_INDEX", "1"))
    if total <= 1:
        return
    keep = [item for i, item in enumerate(items) if i % total == index - 1]
    config.hook.pytest_deselected(items=[item for item in items if item not in keep])
    items[:] = keep
Each of the two jobs reported collected 4 items / 2 deselected / 2 selected, so together they ran all four tests. The split is by count, not duration. The base_url fixture overrides the one pytest-playwright reads, so page.goto("/") works against the demo page or against whatever BASE_URL you set.
pytest's JUnit names already carry the browser, as in test_cart_counts_items[chromium], so the duplicate-name problem does not come up. Screenshots differ, though. pytest-playwright 0.10 records the screenshot path as a JUnit property, and GitLab does not parse properties elements. The failure screenshot is still in the test-results/ artifact. It just won't show in the merge request dialog. For more on the Python setup itself, see pytest-playwright.
Common failures and their fixes
| Symptom in the job log or merge request | Cause | Fix |
|---|---|---|
Executable doesn't exist at /ms-playwright/... |
The image's browser builds differ from the ones the installed Playwright needs | Set the tag the error box names, or pin both to one version |
npm ci fails with EUSAGE |
No package-lock.json in the repo |
Run npm install once and commit the lockfile |
| Test summary missing a browser's failure | Same test name in several projects | includeProjectInTestName: true |
| Screenshot link in a failed test does not open | junit.xml in a subfolder, or test-results/ not uploaded |
Write junit.xml at the root and add test-results/ to artifacts:paths |
| No HTML report after a red run | Artifact paths default to on_success |
artifacts: when: always |
| Merge job: "Blob reports being merged were recorded with different test directories" | Runners checked out to different paths | merge-reports --config merge.config.ts with testDir |
| A secret is empty in merge request pipelines | The CI/CD variable is protected | Protected variables only reach pipelines on protected branches and tags |
Sending results to Blendra from GitLab
If your suite comes from Blendra, the export is an ordinary Playwright project, and the GitLab setup above applies to it. The export includes a GitHub Actions workflow (.github/workflows/e2e.yml), not a .gitlab-ci.yml, so you write the GitLab job yourself. The reporter that sends results back to Blendra runs in any CI, GitLab included, and records the pipeline ID, job name and commit of a GitLab run.
A few export details change the job:
- The export has no lockfile and declares
@playwright/testas^1.52.0. Runnpm installonce, commitpackage-lock.json, then pin the image to the versionnpm ls @playwright/testprints. Its postinstall runsplaywright install chromium, which does nothing when the image matches and downloads Chromium on every job when it does not, one more reason to pin. - It already writes JUnit to
reports/junit/results.xmland the HTML report toreports/html. Because the JUnit file sits in a subfolder, GitLab's screenshot links will not resolve. The screenshots are still in the uploadedreports/folder. - Add
BLENDRA_API_TOKEN(masked),BLENDRA_PROJECT_IDandBLENDRA_API_URLunder Settings > CI/CD > Variables, using the values from.env.example. API tokens are available on Pro and above. Do not mark the token protected if merge request pipelines should report, because protected variables never reach unprotected branches.
# .gitlab-ci.yml for a Playwright TypeScript project exported from Blendra
e2e:
  # Match the @playwright/test version in package-lock.json.
  image: mcr.microsoft.com/playwright:v1.64.1-noble
  variables:
    TEST_ENV: staging
  script:
    - npm ci
    - npm test
  artifacts:
    when: always
    expire_in: 2 weeks
    reports:
      junit: reports/junit/results.xml
    paths:
      - reports/
Know two behaviours before you rely on it. Because GitLab sets CI, a passed run fails the job when the token is missing or when Blendra does not confirm it received the results; a failed run keeps its own failure. And the reporter does not combine shards into one run: each parallel job reports its own run, so keep a Blendra-reporting suite in one unsharded job, as above. The Playwright Python export (Beta, on Pro+ and Team) has its own pytest reporter with the same three settings; pin playwright in its requirements.txt before you pin the Python image. Details are in the reporter docs and Work with CI.
FAQ
Can I use a plain node image instead of the Playwright image?
Yes, but then every run must install browsers and system libraries with npx playwright install --with-deps, which adds download time and depends on package mirrors. A plain image makes sense when you need a Node.js version the Playwright image doesn't ship.
How do I run the tests against a review app or staging?
Set BASE_URL as a job variable, for example from your deploy job's environment URL. With the config above, webServer is skipped and every page.goto('/') resolves against that URL. Keep credentials in masked CI/CD variables, never in the YAML.
Why does the Tests tab show a longer duration than the pipeline took?
GitLab adds up test times across all parallel jobs. Four shards that each spend two minutes on tests show about eight minutes, in a test stage that took about two.
Should I set retry on the GitLab job or retries in Playwright?
Use Playwright's retries for tests. It reruns only the failed test, keeps the trace of the retry, and labels the test flaky in the reports. Use GitLab's job retry only for runner failures, as in the full file above. For the trade-offs of retries, see flaky Playwright tests. For every report format Playwright can write, see Playwright reporters.