Blog / Test design and QA docs
Test design and QA docs
Smoke vs Sanity vs Regression Testing, with Playwright Tags
Clear definitions, when each run belongs in your pipeline, and how to tag tests so CI picks the right set.
Smoke testing vs regression testing is mostly a question of scope and timing. A smoke run asks "is this build worth testing at all?" in a few minutes. A regression run asks "did this change break anything that used to work?" and takes as long as it needs. Sanity testing sits in between, and teams use the word in two different ways. This guide gives working definitions, shows where each run belongs in a CI pipeline, and then gets concrete: how to tag tests in Playwright and pytest so that each stage picks the right set with one command.
TL;DR
| Smoke | Sanity | Regression | |
|---|---|---|---|
| Question it answers | Is the build usable at all? | Does the thing we just fixed or changed work? | Did anything that used to work break? |
| Scope | Broad and shallow: the critical paths | Narrow and deeper: one feature or one fix | Everything you have |
| When | Every pull request and every deploy | After a hotfix or a small change, before wider testing | Before a release, on merge, nightly |
| Typical size | A handful of tests | The tests of one feature | The whole suite |
| On failure | Stop. Reject the build. | Stop. The fix is not done. | Triage each failure |
Key takeaways:
- Smoke is a subset of regression, not a separate suite. Tag the subset; don't tag "everything else".
- Keep smoke fast and boring. One flaky smoke test teaches the team to ignore red builds.
- In Playwright, tag with
{ tag: '@smoke' }and select with--grep @smoke. In pytest, mark with@pytest.mark.smokeand select with-m smoke. --grepis a regular expression, so@smokealso matches@smoke-mobile. Use"@smoke(?=\s|$)"when tags share a prefix.
Smoke testing vs regression testing vs sanity testing: definitions
Smoke testing runs a small set of tests that cover the most important functions, to decide whether a build is stable enough for more testing. If smoke fails, nobody should spend time on deeper testing. The name comes from hardware: power on a new board, and if it smokes, switch it off. Other names you will see are build verification test (BVT), intake test and confidence test.
Regression testing re-runs existing tests after a change to confirm that behaviour which worked before still works. A failure in an area that used to pass is a regression. In practice "the regression suite" means your whole automated suite, plus any manual cases you still run before a release.
Sanity testing is where the terms get muddy. Wikipedia's smoke testing article, which draws on the ISTQB glossary, lists sanity testing as a synonym of smoke testing. Many teams use it differently: a quick, narrow check that one fix or one small change works, run before anyone bothers with a full regression pass. Both uses exist. Pick one meaning, write it in your team's testing notes, and move on. This guide uses the second meaning, because it names a run that smoke and regression don't cover.
One more term that gets mixed in: retesting (also called confirmation testing) means re-running the exact test that failed, to confirm the bug is fixed. A sanity run usually includes that retest plus the tests around it.
Here is how the three look for a small shop with a product list, search, sign-in and checkout:
- Smoke: the home page lists products, and a guest can place an order.
- Sanity, after a coupon bug fix: the test that reproduced the coupon bug, plus every other checkout test.
- Regression: all of the above, plus search, sign-in errors, coupon edge cases and everything else in the suite.
What goes in a smoke set
A test earns a place in the smoke set when it meets all of these:
- It covers a critical path. If this breaks, users can't do the main thing your product is for: sign in, buy, publish, pay. Ask "would we roll back for this?" If not, it's regression.
- It's broad, not deep. One happy-path checkout, not twelve coupon variants. Smoke tells you the building stands; regression checks every room.
- It's fast. Agree a time budget for the whole set (a few minutes is a sensible target) and hold it. When a new test would break the budget, something else has to leave.
- It's stable. A smoke test with a history of flakes doesn't belong there until it's fixed. A failed smoke run must mean "stop", every time. See how to fix flaky Playwright tests for finding the cause.
- It doesn't depend on other tests. Each smoke test creates or finds its own data, so you can run any one of them alone.
- It works in every environment it runs in. If smoke also runs after a staging deploy, it can't rely on data that only exists on a developer's machine.
Watch for two failure modes. The first is smoke creep: every incident adds "just one more" smoke test until the set takes 20 minutes and runs as rarely as regression. Review the set when it breaks its budget. The second is smoke that only checks pages load. A page that renders an error banner still "loads". Assert on something the user needs, such as the product count or the confirmation message. The Playwright assertions guide covers checks that prove something.
A production-safe subset
Smoke after a production deploy needs one more rule: it must not change real data. No real orders, no emails to customers, no payments. Mark the read-only smoke tests with a second tag, such as @prod-safe, and run only those against production. The full smoke set runs on staging, where a test order costs nothing.
Where each run belongs in the pipeline
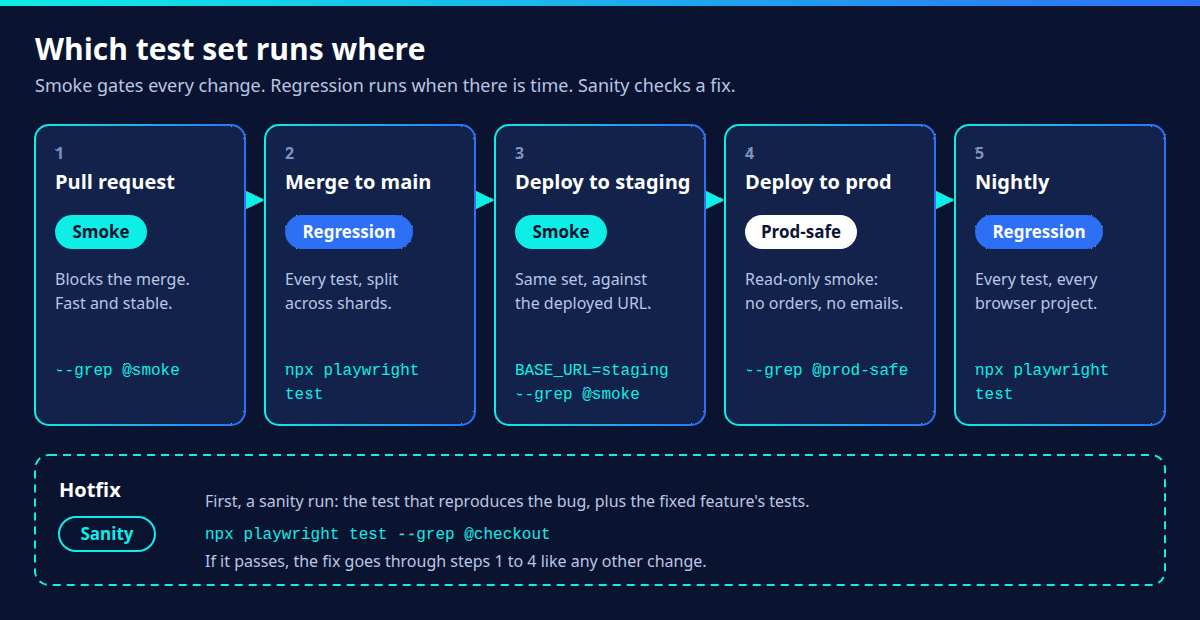
| Trigger | Set | Blocks? | Command |
|---|---|---|---|
| Pull request | Smoke | Yes, the merge | npx playwright test --grep @smoke |
| Merge to main | Regression | Yes, the deploy | npx playwright test (sharded) |
| Deploy to staging | Smoke, against staging | Yes, the promotion | BASE_URL=https://staging.example.com npx playwright test --grep @smoke |
| Deploy to production | Prod-safe smoke | Triggers a rollback decision | BASE_URL=https://example.com npx playwright test --grep @prod-safe |
| Nightly | Regression, every browser project | No, but someone triages it each morning | npx playwright test |
| Hotfix | Sanity, then the normal pipeline | Yes | npx playwright test --grep @checkout |
This split is a starting point, not a law. If your full suite runs in five minutes, run all of it on every pull request and skip the smoke job. The smoke/regression split exists because full suites get slow. When they do, sharding shortens regression runs, and smoke keeps pull requests quick.
The BASE_URL commands assume your config reads the base URL from an environment variable. Playwright environment variables shows that setup.
Here is a GitHub Actions workflow for the first two rows (a fragment: it needs your repository and its package.json to run):
name: e2e

on:
  pull_request:
  push:
    branches: [main]
  schedule:
    - cron: '0 3 * * *' # nightly, 03:00 UTC

jobs:
  smoke:
    if: github.event_name == 'pull_request'
    runs-on: ubuntu-latest
    timeout-minutes: 15
    steps:
      - uses: actions/checkout@v6
      - uses: actions/setup-node@v6
        with:
          node-version: lts/*
      - run: npm ci
      - run: npx playwright install --with-deps chromium
      - run: npx playwright test --grep "@smoke(?=\s|$)"

  regression:
    if: github.event_name != 'pull_request'
    runs-on: ubuntu-latest
    timeout-minutes: 60
    strategy:
      fail-fast: false
      matrix:
        shardIndex: [1, 2, 3, 4]
        shardTotal: [4]
    steps:
      - uses: actions/checkout@v6
      - uses: actions/setup-node@v6
        with:
          node-version: lts/*
      - run: npm ci
      - run: npx playwright install --with-deps
      - run: npx playwright test --shard=${{ matrix.shardIndex }}/${{ matrix.shardTotal }}
Pull requests get the smoke job only; pushes to main and the nightly schedule get the sharded regression job. To merge the shards' reports into one, see the sharding guide linked above. The action versions match the Playwright CI guide as of October 2026.
Tag tests in Playwright
Playwright Test has built-in tags. Pass a tag in the details object, as one string or an array. Every tag must start with @. A tag on test.describe applies to every test inside it.
The examples below run against a three-page demo shop (a product list with search, a sign-in page and a checkout) served locally, with baseURL set in the config. To run them against your own app, swap the URLs and labels for yours.
// tests/shop.spec.ts
import { test, expect } from '@playwright/test';

test('home page lists products', { tag: ['@smoke', '@prod-safe'] }, async ({ page }) => {
  await page.goto('/');
  await expect(page.getByRole('heading', { name: 'Demo Shop' })).toBeVisible();
  await expect(page.getByRole('list', { name: 'Products' }).getByRole('listitem')).toHaveCount(3);
});

test('search narrows the product list', async ({ page }) => {
  await page.goto('/');
  await page.getByLabel('Search products').fill('mug');
  await expect(page.getByRole('listitem').filter({ visible: true })).toHaveText(['Blue Ceramic Mug Buy']);
});

test.describe('checkout', { tag: '@checkout' }, () => {
  test('guest places an order', { tag: '@smoke' }, async ({ page }) => {
    await page.goto('/checkout.html?item=mug');
    await page.getByRole('button', { name: 'Place order' }).click();
    await expect(page.getByRole('status')).toHaveText('Order confirmed');
  });

  test('valid coupon lowers the total', async ({ page }) => {
    await page.goto('/checkout.html?item=mug');
    await page.getByLabel('Coupon code').fill('WELCOME10');
    await page.getByRole('button', { name: 'Apply coupon' }).click();
    await expect(page.getByRole('alert')).toHaveText('Coupon applied');
    await expect(page.locator('#total')).toHaveText('€10.80');
  });

  test('expired coupon shows an error', async ({ page }) => {
    await page.goto('/checkout.html?item=mug');
    await page.getByLabel('Coupon code').fill('SUMMER24');
    await page.getByRole('button', { name: 'Apply coupon' }).click();
    await expect(page.getByRole('alert')).toHaveText('This coupon has expired');
  });
});

test('wrong password shows an error', async ({ page }) => {
  await page.goto('/login.html');
  await page.getByLabel('Email').fill('ada@example.com');
  await page.getByLabel('Password').fill('not-the-password');
  await page.getByRole('button', { name: 'Sign in' }).click();
  await expect(page.getByRole('alert')).toHaveText('Wrong email or password');
});
Notice what isn't tagged: there is no @regression. The regression run is npx playwright test with no filter, so every test is in it by default. A @regression tag only adds a way to forget one.
Select tests with --grep
These are the selections this file supports, each checked with --list, which prints the matching tests without running them:
npx playwright test --grep @smoke                          # 2 tests: the smoke set
npx playwright test --grep @prod-safe                      # 1 test: safe for production
npx playwright test --grep @checkout                       # 3 tests: the sanity run after a checkout fix
npx playwright test --grep-invert @smoke                   # 4 tests: everything except smoke
npx playwright test --grep @checkout --grep-invert @smoke  # 2 tests: checkout, minus its smoke test
npx playwright test --grep "@smoke|@prod-safe"             # 2 tests: either tag
npx playwright test --grep "(?=.*@smoke)(?=.*@checkout)"   # 1 test: both tags
Add --list to any of them to preview the selection before you wire it into CI. Quote any pattern that contains |, or your shell treats it as a pipe. In PowerShell the Playwright docs use --grep --% "@fast^|@slow" for the "either tag" form.
What --grep actually matches
--grep is a regular expression, and it doesn't look at tags alone. The TestProject grep docs say it is tested against one string made of the project name, the test file name, the describe titles, the test title and the tags, separated by spaces. Two consequences:
A tag that starts with another tag's name matches both. Put a test tagged
@smokeand one tagged@smoke-mobilein a file, and--grep @smokeruns both (list reporter output, timings removed):$ npx playwright test --grep @smoke ✓ 1 pitfall/tags.spec.ts:3:5 › home page lists products @smoke ✓ 2 pitfall/tags.spec.ts:8:5 › product list fits a phone screen @smoke-mobileA word boundary doesn't help, because
-counts as a boundary:@smoke\bstill matches@smoke-mobile. Use a lookahead that requires a space or the end of the string after the tag:npx playwright test --grep "@smoke(?=\s|$)" # 1 test: @smoke onlyFile names and titles count too.
--grep shopselects all 6 tests above, because the file isshop.spec.ts. Keep the@in every tag pattern: it only matches tags, plus any@wordyou put in a title (Playwright treats those as tags anyway).
A pattern that matches nothing fails the run with Error: No tests found and exit code 1. That's what you want in CI: a typo in a tag fails loudly instead of passing with zero tests.
Tags also show up in the HTML report, and typing @smoke in the report's filter box narrows the list to the tagged tests.
Named sets in the config
If you'd rather type --project=smoke than a regular expression, put the filters on projects. grep and grepInvert work per project:
// playwright.config.ts (fragment: merge into your existing config)
import { defineConfig } from '@playwright/test';

export default defineConfig({
  testDir: './tests',
  projects: [
    // npx playwright test --project=smoke
    { name: 'smoke', grep: /@smoke(?=\s|$)/ },
    // npx playwright test --project=regression
    { name: 'regression', grepInvert: /@quarantine(?=\s|$)/ },
  ],
});
One trap: with both projects defined, a bare npx playwright test runs both, so the smoke tests run twice (8 tests instead of 6 for the file above). Always pass --project when you use this pattern. The @quarantine filter is one way to park a known-flaky test while someone fixes it. Playwright retries covers why parking beats retrying it forever.
Markers in pytest
pytest uses markers for the same job. Register them in pyproject.toml, and turn on --strict-markers so a typo stops the run:
[tool.pytest.ini_options]
testpaths = ["tests"]
addopts = "--strict-markers"
base_url = "http://localhost:4173"
markers = [
    "smoke: fast, stable checks of the critical paths; run on every change",
    "prod_safe: read-only checks that are safe to run against production",
    "checkout: tests of the checkout feature",
    "quarantine: known flaky; kept out of blocking runs until fixed",
]
Marker names must be valid Python identifiers, so prod-safe becomes prod_safe, and there is no @. The same suite with pytest-playwright:
# tests/test_shop.py
import pytest
from playwright.sync_api import Page, expect


@pytest.mark.smoke
@pytest.mark.prod_safe
def test_home_page_lists_products(page: Page):
    page.goto("/")
    expect(page.get_by_role("heading", name="Demo Shop")).to_be_visible()
    expect(page.get_by_role("list", name="Products").get_by_role("listitem")).to_have_count(3)


def test_search_narrows_the_product_list(page: Page):
    page.goto("/")
    page.get_by_label("Search products").fill("mug")
    expect(page.get_by_role("listitem").filter(visible=True)).to_have_text(["Blue Ceramic Mug Buy"])


@pytest.mark.checkout
class TestCheckout:
    @pytest.mark.smoke
    def test_guest_places_an_order(self, page: Page):
        page.goto("/checkout.html?item=mug")
        page.get_by_role("button", name="Place order").click()
        expect(page.get_by_role("status")).to_have_text("Order confirmed")

    def test_valid_coupon_lowers_the_total(self, page: Page):
        page.goto("/checkout.html?item=mug")
        page.get_by_label("Coupon code").fill("WELCOME10")
        page.get_by_role("button", name="Apply coupon").click()
        expect(page.get_by_role("alert")).to_have_text("Coupon applied")
        expect(page.locator("#total")).to_have_text("€10.80")

    def test_expired_coupon_shows_an_error(self, page: Page):
        page.goto("/checkout.html?item=mug")
        page.get_by_label("Coupon code").fill("SUMMER24")
        page.get_by_role("button", name="Apply coupon").click()
        expect(page.get_by_role("alert")).to_have_text("This coupon has expired")


def test_wrong_password_shows_an_error(page: Page):
    page.goto("/login.html")
    page.get_by_label("Email").fill("ada@example.com")
    page.get_by_label("Password").fill("not-the-password")
    page.get_by_role("button", name="Sign in").click()
    expect(page.get_by_role("alert")).to_have_text("Wrong email or password")
A marker on a class applies to every test method in it, so all three checkout tests carry checkout. For a whole module, set pytestmark = pytest.mark.checkout at the top of the file.
Select with -m and a boolean expression:
pytest -m smoke                       # 2 passed, 4 deselected
pytest -m prod_safe                   # 1 passed, 5 deselected
pytest -m "checkout and not smoke"    # 2 passed, 4 deselected
pytest -m "not quarantine"            # 6 passed
pytest --collect-only -q -m smoke     # list the selection without running it
Three differences from Playwright's --grep are worth knowing:
-mmatches marker names exactly.-m smokenever selects a test markedsmoke_mobile, so the prefix problem from the Playwright section doesn't exist here.-kis the substring filter.-k checkoutmatches test names, class names and module names that contain "checkout". It's handy for one-off runs, but a rename can silently change what it selects. Use markers for anything CI depends on.- An empty selection exits with code 5.
pytest -m smokdeselects everything and exits with 5 ("no tests collected"), which fails most CI steps.--strict-markersdoesn't catch a typo in-m; it catches typos in decorators. With it on,@pytest.mark.smokstops collection with'smok' not found in `markers` configuration option. Without it, pytest only prints aPytestUnknownMarkWarningand runs the test.
Tags in a Blendra export
Blendra records your app's flows in Chrome and exports them as a test suite in your repo. Tags work like this as of October 2026:
- You set tags on a recording or a journey through the API (
tagsonPATCH /api/recordings/:idorPATCH /api/flows/:flowId). There's no tags screen in the app yet. - Tags are stored in lower case with the
@added, soSmokebecomes@smoke. Each recording or journey takes up to 10. - On export layout 2, the default for new projects, the Playwright TypeScript export writes the tags on the journey's or recording's
test.describe()as{ tag: [...] }.SUITE.mdlists every tag, and the README's "Run by tag" section gives the command, with the exact-match lookahead from this guide:npx playwright test --grep "@smoke(?=\s|$)". Layout 1 ignores tags. - The Playwright Python export (Beta, on Pro+ and Team) registers one pytest marker per tag in
pyproject.toml, namedtag_plus the tag:@smokeruns withpytest -m tag_smoke. The prefix means a tag like@skipcan never switch on pytest's ownskipmarker. - The Cypress export (also Beta, on Pro+ and Team) writes
{ tags: ["smoke"] }on the test, and its docs give the command for running one tag.
Blendra's test case docs also carry a type field, with Smoke and Regression among the eleven types, if you keep written test cases next to the automated ones.
FAQ
Is sanity testing the same as smoke testing?
It depends on who you ask. Wikipedia's smoke testing article, which cites the ISTQB glossary, lists them as synonyms. Many teams use "sanity" for a narrow check of one fix or change, and "smoke" for a broad check of a whole build. Both are fine. What matters is that everyone on your team means the same thing by each word.
How many tests should a smoke suite have?
There's no right number. Set a time budget instead, and fill it with one test per critical path. If the set breaks the budget, drop the least critical test or make the slow one faster. Don't just raise the budget.
Should I tag tests @regression?
Usually not. If regression means "the whole suite", every untagged test is already in it, and a @regression tag only creates a way to miss one. Tag the subsets you select (@smoke, @prod-safe, a feature like @checkout) and run regression with no filter.
Should smoke tests run against production?
A read-only subset can, right after a deploy. Keep anything that creates orders, sends emails or charges cards out of it, and tag the safe tests separately (@prod-safe here). The rest of smoke belongs on staging.
Can I run only the tests affected by my change?
Playwright has --only-changed, which runs the test files that changed since a git ref you pass (--only-changed=origin/main), plus the test files that import a changed file, per the 1.46 release notes. End-to-end tests rarely import your app's source code, though, so a pull request that only changes the app can select no tests at all. Pair it with smoke rather than replacing smoke. Measuring what your suite actually exercises is a separate job, covered in E2E test coverage.