Blog / Test design and QA docs
Test design and QA docs
E2E Test Coverage: What to Measure When Line Coverage Doesn't Apply
Line coverage says little about an end-to-end suite. Here are measures a QA lead can defend.
E2E test coverage is a number QA leads are often asked for and rarely trust. Unit tests have line coverage. An end-to-end suite drives a real browser through a real app, so "which lines ran" answers the wrong question. The useful questions are different. Which user journeys does the suite reach? Which outcomes does it actually check? Where are the gaps that would hurt most? This guide turns each one into a number you can compute from a Playwright suite. You get a small demo app, the scripts, their real output, and the traps that make coverage numbers lie. To follow along, download the demo project, run npm install and npx playwright install chromium, then npx playwright test.
TL;DR
- Line coverage from e2e runs counts code that ran, not results anyone checked. In the demo below, a test that never checks the order runs the whole success path of the checkout button's code.
- Journey coverage: keep a list of user journeys, tag each test with one (
@journey:checkout), and count the journeys that have at least one test. - Outcome coverage: count the journeys where a test asserts something only a working journey produces, such as an order number. Then break the app on purpose to prove the assertion notices.
- Risk-weighted gaps: weight journeys by impact, report the share of risk points with an asserted outcome, and name the uncovered high-risk journeys.
- Don't report test counts or pass rates as coverage. Six tests can cover two journeys well and miss the one that locks customers out.
Why line coverage misleads for e2e
You can collect line coverage from browser tests. Playwright's page.coverage API records which JavaScript ran, in Chromium only, in V8's format. Its docs show how to turn that into an Istanbul report with the v8-to-istanbul package. The real question is what the number means.
The demo shop for this post has a checkout page with a "Place order" button. The click handler posts to /api/orders, then shows "Order placed" and an order number. Here is a test that many suites contain in some form (a fragment: the full file comes later):
test('checkout page loads', async ({ page }) => {
  await page.goto('/checkout.html');
  await expect(page).toHaveTitle(/Checkout/);
  await page.getByRole('button', { name: 'Place order' }).click();
});
We ran these steps with page.coverage.startJSCoverage() in Chromium and gave the order request half a second to finish. V8 reported that the click handler ran, success path included. The only block it never entered was the error branch. By line coverage, this test covers checkout. Yet it never looks at what the click did. Later you will make the order API fail, and this test will stay green.
Line coverage fits e2e suites poorly for three more reasons:
- It sees one side. Browser coverage measures the JavaScript the page loaded. The server code behind the journey needs its own instrumentation, and merging the two is a project of its own.
- It rewards walking, not checking. One long test that clicks through every page scores high and can assert nothing.
- It doesn't answer the business question. A line percentage can't tell anyone whether password reset works.
Line coverage still has one honest use for e2e: finding code that no browser test ever runs. That is a fair question to ask. Just don't read the number as a quality score.
Journey coverage: which user goals the suite reaches
A journey is something a user comes to do: sign in, check out, reset a password, download an invoice. User journey coverage is the share of those goals that at least one test walks through.
Start with an inventory, not with the tests
If you build the journey list from your tests, you only ever find journeys you already test. Build it from outside the suite instead:
- the product's main navigation and settings pages
- the flows that take money, grant access, or change or delete data
- the most visited pages in your analytics
- recent incidents and support tickets
- your written test cases (see how to write test cases)
Name each journey by the user's goal, not by the page, and give it a risk level. The demo keeps the inventory in a file next to the tests:
[
  { "id": "login", "name": "Sign in", "risk": "high" },
  { "id": "checkout", "name": "Checkout", "risk": "high" },
  { "id": "password-reset", "name": "Reset a forgotten password", "risk": "high" },
  { "id": "search", "name": "Search products", "risk": "medium" },
  { "id": "invoices", "name": "Download an invoice", "risk": "medium" },
  { "id": "profile", "name": "Edit profile", "risk": "low" },
  { "id": "newsletter", "name": "Newsletter sign-up", "risk": "low" }
]
Tag every test with its journey and risk
Playwright tags start with @, and you can put them on a single test or on a whole describe block (annotations docs). Pick one naming scheme and keep to it. Here @journey:<id> must match an id in journeys.json, and @risk:<level> lets you select runs by risk. A custom outcome annotation states what the test proves.
// tests/login.spec.ts
import { test, expect } from '@playwright/test';

test.describe('Sign in', { tag: ['@journey:login', '@risk:high'] }, () => {
  test('signs in with valid details', {
    annotation: { type: 'outcome', description: 'Account page greets the user by name' },
  }, async ({ page }) => {
    await page.goto('/login.html');
    await page.getByLabel('Email').fill('ana@example.com');
    await page.getByLabel('Password').fill('demo-password');
    await page.getByRole('button', { name: 'Sign in' }).click();
    await expect(page).toHaveURL(/\/account\.html$/);
    await expect(page.getByRole('heading', { name: 'Welcome back, Ana' })).toBeVisible();
  });

  test('rejects a wrong password', {
    annotation: { type: 'outcome', description: 'Error says the details are wrong' },
  }, async ({ page }) => {
    await page.goto('/login.html');
    await page.getByLabel('Email').fill('ana@example.com');
    await page.getByLabel('Password').fill('not-the-password');
    await page.getByRole('button', { name: 'Sign in' }).click();
    await expect(page.getByRole('alert')).toHaveText('Email or password is wrong');
    await expect(page).toHaveURL(/\/login\.html$/);
  });
});
// tests/checkout.spec.ts
import { test, expect } from '@playwright/test';
test.describe('Checkout', { tag: ['@journey:checkout', '@risk:high'] }, () => {
// Reaches the journey, proves nothing about it.
test('checkout page loads', async ({ page }) => {
await page.goto('/checkout.html');
await expect(page).toHaveTitle(/Checkout/);
await page.getByRole('button', { name: 'Place order' }).click();
});
test('places an order', {
annotation: { type: 'outcome', description: 'Confirmation shows an order number' },
}, async ({ page }) => {
await page.goto('/checkout.html');
await page.getByRole('button', { name: 'Place order' }).click();
await expect(page.getByRole('status')).toHaveText('Order placed');
await expect(page.getByTestId('order-number')).toHaveText(/^ORD-\d{6}$/);
});
});The third file holds two weak tests on purpose: a search test that asserts nothing, and a test with no journey tag.
// tests/search.spec.ts
import { test, expect } from '@playwright/test';

// Runs every step of a search and asserts nothing.
test('search for mugs', { tag: ['@journey:search', '@risk:medium'] }, async ({ page }) => {
  await page.goto('/search.html');
  await page.getByRole('searchbox').fill('mug');
  await page.getByRole('button', { name: 'Search' }).click();
});

// No journey tag: the coverage report flags it.
test('account page links to search', async ({ page }) => {
  await page.goto('/account.html');
  await page.getByRole('link', { name: 'Search products' }).click();
  await expect(page).toHaveURL(/\/search\.html$/);
});
The config starts the demo server, a Node file with no dependencies, before the tests run:
// playwright.config.ts
import { defineConfig } from '@playwright/test';

const baseURL = process.env.BASE_URL ?? 'http://127.0.0.1:4191';

export default defineConfig({
  testDir: './tests',
  use: { baseURL },
  webServer: {
    command: 'node server.mjs',
    url: `${baseURL}/login.html`,
    // Always start a fresh server so BREAK_ORDER=1 takes effect.
    reuseExistingServer: false,
  },
});
List the tests for each journey
--list collects the tests and prints them without running anything: no browser, no web server. That makes it cheap enough for every pull request.
npx playwright test --list --grep "@journey:checkout"Listing tests:
checkout.spec.ts:5:7 › Checkout › checkout page loads
checkout.spec.ts:11:7 › Checkout › places an order
Total: 2 tests in 1 fileThree more queries are worth keeping. The first needs both tags (the lookahead form from the Playwright docs). The second finds tests with no journey tag. The third checks a journey you expect to have tests:
# High-risk sign-in tests only (both tags must match)
npx playwright test --list --grep "(?=.*@risk:high)(?=.*@journey:login)"

# Tests without any journey tag
npx playwright test --list --grep-invert "@journey:"

# A journey with no tests: prints "Error: No tests found" and exits with code 1
npx playwright test --list --grep "@journey:password-reset"
That exit code is useful. A CI step can run the last command for each must-have journey and fail when someone deletes its last test.
Turn the list into a coverage report
With --reporter=json, --list prints the whole test tree, tags and annotations included, still without running a test. The script below joins it with the inventory and prints three numbers.
npx playwright test --list --reporter=json > list.json
node coverage-report.mjs list.json journeys.json
// coverage-report.mjs
import { readFileSync } from 'node:fs';
const [listFile, journeysFile] = process.argv.slice(2);
const report = JSON.parse(readFileSync(listFile, 'utf8'));
const journeys = JSON.parse(readFileSync(journeysFile, 'utf8'));
const WEIGHT = { high: 3, medium: 2, low: 1 };
// Flatten the suite tree (files > describes > specs) into one list of tests.
const specs = [];
const walk = (suite) => {
for (const spec of suite.specs ?? []) specs.push(spec);
for (const child of suite.suites ?? []) walk(child);
};
report.suites.forEach(walk);
// The JSON report stores tags without the "@": "journey:checkout".
const tagValue = (spec, key) =>
spec.tags.find((tag) => tag.startsWith(`${key}:`))?.slice(key.length + 1);
const outcomesOf = (spec) =>
(spec.tests[0]?.annotations ?? []).filter((a) => a.type === 'outcome');
const problems = [];
for (const spec of specs) {
const where = `${spec.file}:${spec.line} "${spec.title}"`;
const journey = tagValue(spec, 'journey');
const listed = journeys.find((j) => j.id === journey);
const risk = tagValue(spec, 'risk');
if (!journey) problems.push(`No journey tag: ${where}`);
else if (!listed) problems.push(`Unknown journey "${journey}": ${where}`);
else if (risk && risk !== listed.risk) {
problems.push(`Risk tag ${risk}, journeys.json says ${listed.risk}: ${where}`);
}
}
const rows = journeys.map((j) => {
const tests = specs.filter((spec) => tagValue(spec, 'journey') === j.id);
const outcomes = tests.flatMap(outcomesOf).length;
const state = outcomes ? 'outcome asserted' : tests.length ? 'reached only' : 'NO TEST';
return { ...j, tests: tests.length, outcomes, state };
});
const sum = (list) => list.reduce((total, j) => total + WEIGHT[j.risk], 0);
const proven = rows.filter((r) => r.outcomes > 0);
const pct = Math.round((100 * sum(proven)) / sum(rows));
const line = (r) =>
[r.name.padEnd(27), r.risk.padEnd(7), String(r.tests).padStart(5),
String(r.outcomes).padStart(8), ` ${r.state}`].join(' ');
const header = { name: 'Journey', risk: 'Risk', tests: 'Tests', outcomes: 'Outcomes' };
console.log(line({ ...header, state: 'State' }));
rows.forEach((r) => console.log(line(r)));
const gaps = rows.filter((r) => r.risk === 'high' && !r.outcomes);
console.log(`
Journeys with at least one test: ${rows.filter((r) => r.tests).length} of ${rows.length}
Journeys with an asserted outcome: ${proven.length} of ${rows.length}
Risk-weighted outcome coverage: ${sum(proven)} of ${sum(rows)} points (${pct}%)
High-risk gaps: ${gaps.map((r) => `${r.name} (${r.state})`).join(', ') || 'none'}`);
if (problems.length) {
console.log(`\nFix these tags:\n- ${problems.join('\n- ')}`);
process.exitCode = 1; // lets CI fail on untagged or mistagged tests
}The output for the demo suite:
Journey                     Risk    Tests Outcomes  State
Sign in                     high        2        2  outcome asserted
Checkout                    high        2        1  outcome asserted
Reset a forgotten password  high        0        0  NO TEST
Search products             medium      1        0  reached only
Download an invoice         medium      0        0  NO TEST
Edit profile                low         0        0  NO TEST
Newsletter sign-up          low         0        0  NO TEST

Journeys with at least one test:    3 of 7
Journeys with an asserted outcome:  2 of 7
Risk-weighted outcome coverage:     6 of 15 points (40%)
High-risk gaps: Reset a forgotten password (NO TEST)

Fix these tags:
- No journey tag: search.spec.ts:11 "account page links to search"
The script exits with code 1 here because of the untagged test. Tag it, or decide that it belongs to no journey, and the exit code goes back to 0.
Outcome coverage: what the suite really asserts
Journey coverage says a test went somewhere. Outcome coverage asks whether it checked that the journey worked. An outcome is something only a working journey produces: the order number, the "Email or password is wrong" message, the new URL, a saved value that is still there after a reload. A page title is not an outcome. Neither is a button that was visible before you clicked it. Both hold whether or not the click did anything.
Three traps are common:
- Tests with no assertion.
search for mugstypes a word, clicks Search and ends. It passes as long as nothing throws. - Tests that only check the page loaded.
checkout page loadsasserts a title and clicks a button. - Counting assertions as a stand-in for coverage. "Every test has an assertion" sounds healthy. The weak checkout test has one.
Find the tests that assert nothing
A custom reporter can count the expect calls each test really ran. The reporter API gives every step a category, and expect is the category for expect calls (TestStep docs).
// assertion-count-reporter.ts
import type { Reporter, TestCase, TestResult, TestStep } from '@playwright/test/reporter';

// Counts the expect() calls each test actually ran and lists tests that ran none.
export default class AssertionCountReporter implements Reporter {
  private counts = new Map<TestCase, number>();

  // Start from zero on every attempt, so a retry does not double the count.
  onTestBegin(test: TestCase) {
    this.counts.set(test, 0);
  }

  onStepEnd(test: TestCase, _result: TestResult, step: TestStep) {
    if (step.category === 'expect') this.counts.set(test, (this.counts.get(test) ?? 0) + 1);
  }

  onEnd() {
    console.log('\nexpect() calls per test');
    for (const [test, count] of this.counts) {
      const flag = count === 0 ? '  <- asserts nothing' : '';
      console.log(`${String(count).padStart(3)}  ${test.title}${flag}`);
    }
  }
}
Run it next to a normal reporter. The lines follow the order in which the tests started:
npx playwright test --reporter=line,./assertion-count-reporter.tsexpect() calls per test
0 search for mugs <- asserts nothing
2 signs in with valid details
1 checkout page loads
1 account page links to search
2 places an order
2 rejects a wrong password
6 passed (1.1s)Zero is a reliable red flag. One or more tells you nothing: checkout page loads ran one assertion and proves nothing about checkout. So this measure of assertion coverage catches the first trap only. For more on what the reporter API can do, see Playwright reporters.
Prove an outcome assertion by breaking the app
An outcome annotation is a claim. To check it, break the journey and see which tests fail. A test that stays green while the journey is broken does not cover it. This is the idea behind mutation testing, which tools like Stryker apply to unit tests: a change that no test catches "survives", and that marks a gap.
The demo server has a switch for this. With BREAK_ORDER=1, the order API answers 503 and the page shows an error instead of a confirmation. The command below is for bash or zsh; in PowerShell, run $env:BREAK_ORDER = '1' first and drop the prefix.
BREAK_ORDER=1 npx playwright test --grep @journey:checkoutThe output, trimmed to the parts that matter:
  ✓  1 tests/checkout.spec.ts:5:7 › Checkout › checkout page loads @journey:checkout @risk:high (113ms)
  ✘  2 tests/checkout.spec.ts:11:7 › Checkout › places an order @journey:checkout @risk:high (5.1s)

    Error: expect(locator).toHaveText(expected) failed

    Locator:  getByRole('status')
    Expected: "Order placed"
    Received: ""
    Timeout:  5000ms

  1 failed
  1 passed (5.8s)
The weak test passed against a broken checkout. It counts toward journey coverage, not toward outcome coverage. The outcome test failed, which is exactly its job.
Most apps have no break switch. You can fake the failure inside a test instead, with page.route. This fragment goes before the goto in a copy of the test:
await page.route('**/api/orders', (route) => route.fulfill({ status: 503 }));The copy must fail. If it passes, the original test proves nothing about placing an order.
Do this once per high-risk journey, when you write the test and again when you refactor it. You don't need it on every build. Playwright network mocking covers routing in depth, and Playwright assertions covers how to pick checks that prove something.
Risk-weighted gaps
Journeys aren't equal. A missing test for newsletter sign-up and a missing test for password reset each count as one gap, but only one of them locks customers out. Weighting fixes the count.
Keep the scale small. Three levels are enough:
| Risk | Weight | Typical journeys |
|---|---|---|
| High | 3 | Takes money, controls access, changes or deletes data |
| Medium | 2 | A core feature people use often, with a workaround if it breaks |
| Low | 1 | Rarely used, or cosmetic |
Risk-weighted outcome coverage is the sum of the weights of journeys with an asserted outcome, divided by the sum of all weights. In the demo, sign in (3) plus checkout (3) gives 6 of 15 points, or 40%.
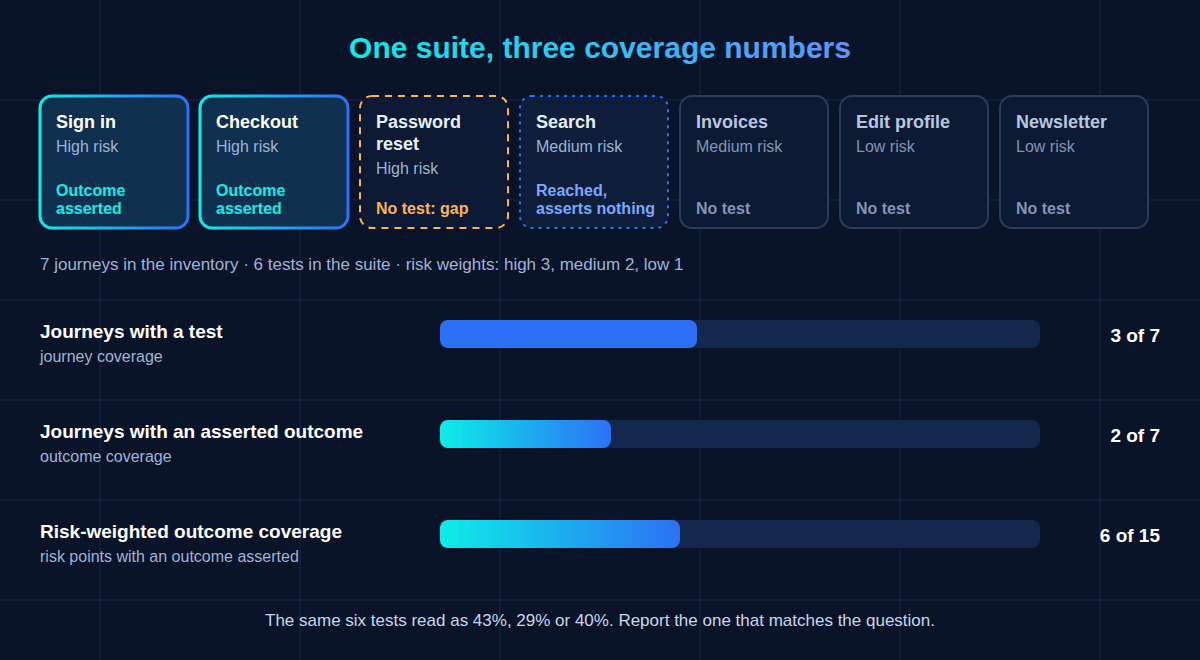
The percentage is the headline. The gap list is the work. Sort the journeys without an asserted outcome by weight and start at the top. In the demo, password reset comes first. Search and invoices tie at medium, and search is the quicker fix: its test exists and only needs an outcome assertion.
Watch for these traps:
- Journeys that are too coarse. "Checkout" with one happy-path test counts as covered, while a declined card is never tested. When a journey has several outcomes that matter, give each its own row: "Checkout: order placed" and "Checkout: card declined".
- Risk in two places. The
@risktag and the inventory can drift apart. The script flags tests whose tag disagrees withjourneys.json. - Chasing 100%. Some journeys are better checked by an API test or a unit test than by a slow browser test. Leave them out of the browser inventory and note where they are covered.
- Self-declared outcomes. The annotation is only as honest as the person who wrote it. Review it like code, and run the break-it check on high-risk journeys.
Reporting e2e test coverage to people outside QA
When a product manager asks "are we covered?", they want to know what could break without anyone noticing. Test coverage for QA leads means turning the end-to-end test coverage metrics above into something a non-tester can act on:
- Two numbers, each defined in one sentence. "2 of 7 user journeys have a test that checks they worked. Weighted by risk, that is 40%."
- The top gaps, by name. "Password reset has no test, and it is high risk."
- The trend. The same numbers every release, so a drop is visible.
- What changed in the inventory. Adding journeys lowers the percentage. Say so, or people will read it as a regression.
A status update can be this short:
E2E coverage, release 4.2
- 2 of 7 user journeys have a test that checks the result (40% of risk points)
- High-risk gap: password reset has no test (planned this sprint)
- Search has a test that never checks results (being fixed)
- Inventory unchanged since 4.1
Leave out the test count, the pass rate and line coverage. A pass rate tells you what passed, not what was checked. Adding tests to journeys that are already covered raises the count without closing a gap. Also say which run the numbers describe. A smoke run covers fewer journeys than the full regression run, by design (see smoke vs regression testing).
How Blendra shows what a suite proves
Blendra records flows in Chrome and turns them into Playwright tests with checks. Its Checks board answers the outcome question for those tests without any tagging:
- It sorts every enabled browser test, recorded or built, into three groups: proven, only checks the page loaded, and not proven yet. A test is proven when at least one of its checks looks at what the app did after a step. API suites are not counted.
- A check that only confirms the button the next step clicks was visible before the click puts the test in the "only checks the page loaded" group. That is the
checkout page loadstrap from above, caught automatically. - An Unchecked outcomes section lists, per recording, the messages, errors, page changes and dialogs the app showed while recording that no check looks at yet. It is a gap list built from what the app actually did.
- You can narrow the board to one journey. It also shows what is failing now and which checks are flaky (two or more flips in the last 10 results).
It does not map tests to your requirements or acceptance criteria, so it doesn't replace the journey inventory above. It tells you whether the tests you have check anything. For trends, run history is kept for 7 days on Free and up to 365 days on Team (test history).
FAQ
What is a good e2e test coverage percentage?
There is no standard target, and a single percentage invites gaming. Set the bar by risk instead. Every high-risk journey should have at least one test that asserts its outcome and fails when you break it. After that, add coverage where incidents and support tickets point.
Should I still collect code coverage from e2e tests?
It can help as a gap finder: it shows screens and handlers that no browser test ever runs. Don't use it as a quality score or a merge gate. As the demo shows, a test can run code without checking anything. Remember that Playwright's coverage API works in Chromium only.
How is journey coverage different from requirement traceability?
Requirement traceability links each requirement or acceptance criterion to the tests that verify it, usually in a test management tool. Journey coverage is coarser: one row per user goal. Start with journeys, because the list is short and anyone can review it. Add requirement links where audits or contracts ask for them.
Is counting assertions per test useful at all?
Only to find tests with zero. Above zero, the count can't tell a page-loaded check from an outcome check. Outcome coverage needs a stated outcome per journey and a check that the test fails when that outcome breaks.
How do I keep journey tags accurate?
Run the coverage script on every pull request and fail the build when it reports a tag problem: a missing journey tag, an unknown journey or a risk mismatch. Review new journeys in journeys.json the same way you review code.