Playwright
Selenium to Playwright Migration: A Step-by-Step Plan
How to move from Selenium to Playwright one flow at a time, with a mapping table for waits, locators and assertions.
A Selenium to Playwright migration rarely fails because Playwright is hard to learn. It fails when a team translates a few hundred tests line by line, keeps the old waits and page objects, and ends up with two half-working suites. This guide takes the safer route: inventory, one critical flow, both suites side by side in CI, the rest in waves, then delete Selenium.
Every code sample here, except the GitHub Actions workflow (whose commands we ran locally), ran against a small demo app with Selenium 4.51 and Playwright for Python 1.64 (pytest-playwright 0.10), plus Playwright Test 1.61 for TypeScript, in October 2026.
Key takeaways
- Don't translate code. Map the concepts with the table below, then rewrite each flow from what it should prove.
- Most of your wait code disappears. Playwright actions wait until the element is actionable, and
expectassertions retry. - Port your most important flow first, and run it 20 times before you trust it.
- Keep Selenium as the required CI check until each ported flow has a green parity record. Then delete it flow by flow.
- Don't trust anyone's speed claims, including ours. Time both suites yourself with the script below.
Reasons to migrate, and reasons to wait
Good reasons to move:
- Your flakes are timing flakes.
StaleElementReferenceException, clicks that land on a spinner, growingsleepcalls. A Playwright locator re-runs its query each time you use it, and before a click Playwright checks that the element is visible, stable, enabled and able to receive events (actionability). - You can't debug CI failures. The trace viewer records each action with DOM snapshots, network and console output, so you can open a CI failure on your laptop. See Playwright trace viewer.
- You run a Grid only for parallel runs. Playwright Test runs files in parallel workers and splits a suite across machines with
--shard(parallelism). In Python, pytest-xdist runs tests in parallel processes.
Good reasons to wait, or to stay:
- You write tests in Ruby. Playwright has official bindings for JavaScript/TypeScript, Python, Java and .NET (languages). Selenium's official bindings are Java, Python, C#, Ruby and JavaScript (Selenium install docs).
- You must test real Safari. Selenium drives Safari on macOS through SafariDriver, which comes with the operating system (Safari docs). Playwright tests its own WebKit build, not branded Safari (browsers).
- You test on real phones. Playwright emulates mobile viewports. Its real-device support is an experimental Android API for Chrome and WebView (Android). Keep real-iPhone tests on your WebDriver device cloud.
- The suite is stable, or your slowness is in the backend. A migration costs weeks, and a new framework won't fix a slow seed script.
Measure speed yourself
Published speed comparisons rarely share their suites. Port one representative flow, then time both versions on the same machine, app and browser family:
"""Time whole commands on this machine: min, median and max wall-clock seconds over N runs.

Usage: python tools/measure.py 5 "pytest tests/selenium -q" "pytest tests/playwright -q"
"""
import shlex
import statistics
import subprocess
import sys
import time


def time_command(command: str, runs: int) -> list[float]:
    timings = []
    for _ in range(runs):
        start = time.perf_counter()
        subprocess.run(shlex.split(command), check=True, stdout=subprocess.DEVNULL)
        timings.append(time.perf_counter() - start)
    return timings


if __name__ == "__main__":
    runs = int(sys.argv[1])
    for command in sys.argv[2:]:
        subprocess.run(shlex.split(command), check=True, stdout=subprocess.DEVNULL)  # warm-up, not counted
        t = time_command(command, runs)
        print(f"{command}\n  min {min(t):.1f}s  median {statistics.median(t):.1f}s  max {max(t):.1f}s")
Compare medians on a machine the size of your CI runners. Time again after a few dozen tests.
A Selenium to Playwright migration in five phases
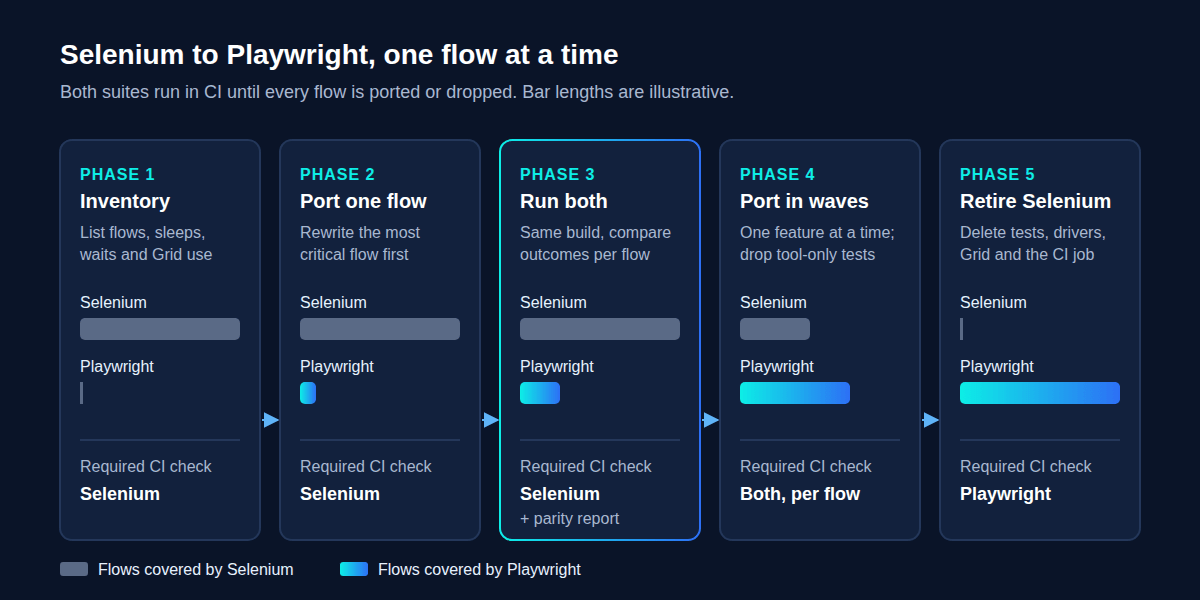
- Inventory every flow and the Selenium features it uses.
- Port one flow, your most critical, and prove it's stable.
- Run both suites against the same build and compare outcomes per flow.
- Port in waves, one feature area at a time.
- Retire Selenium: make Playwright the required check and delete the rest.
Take the inventory
Start with a spreadsheet: one row per test, with its owner, last month's failures and the hard parts it uses. Three searches from the repo root find most hard parts:
# Fixed sleeps and implicit waits: each one is a timing bug waiting to happen
grep -rnE "time\.sleep|Thread\.sleep|implicitly_wait|implicitlyWait" tests legacy_pages

# How much raw element lookup lives in each file
grep -rnEc "find_element|findElement" tests legacy_pages

# Frames, windows, alerts, raw JavaScript and Grid: plan these by hand
grep -rnE "switch_to|switchTo\(\)|ActionChains|new Actions|execute_script|executeScript|RemoteWebDriver|webdriver\.Remote" tests legacy_pages
Mark each test port, merge (it proves what another test proves) or drop. A test of Selenium's behaviour rather than your app's is a drop.
The Selenium to Playwright mapping table
Selenium in Java and Python on the left, Playwright Test in TypeScript on the right. Playwright for Python uses the same names in snake_case (get_by_label, to_be_visible).
| Task | Selenium (Java) | Selenium (Python) | Playwright (TypeScript) |
|---|---|---|---|
| Start and stop a browser | new ChromeDriver() … driver.quit() |
webdriver.Chrome() … driver.quit() |
the page fixture opens and closes it |
| Open a page | driver.get(url) |
driver.get(url) |
page.goto('/orders') with baseURL |
| Find a field | driver.findElement(By.id("email")) |
driver.find_element(By.ID, "email") |
page.getByLabel('Email') |
| Find a button by text | By.xpath("//button[text()='Save']") |
(By.XPATH, "//button[text()='Save']") |
page.getByRole('button', { name: 'Save' }) |
| Count matches | findElements(by).size() |
len(driver.find_elements(*loc)) |
await expect(locator).toHaveCount(3) |
| Type text | sendKeys("x") (appends) |
send_keys("x") (appends) |
fill('x') (replaces); pressSequentially('x') for key events |
| Pick an option | new Select(el).selectByVisibleText("UK") |
Select(el).select_by_visible_text("UK") |
selectOption('UK') |
| Hover, drag | new Actions(driver).moveToElement(el).perform() |
ActionChains(driver).move_to_element(el).perform() |
hover(), dragTo(target) |
| Implicit wait | manage().timeouts().implicitlyWait(...) |
driver.implicitly_wait(10) |
none: every action waits for actionability |
| Wait until visible | wait.until(ExpectedConditions.visibilityOfElementLocated(by)) |
wait.until(EC.visibility_of_element_located(loc)) |
await expect(locator).toBeVisible() |
| Wait for text | textToBePresentInElementLocated(by, "Paid") |
EC.text_to_be_present_in_element(loc, "Paid") |
await expect(locator).toContainText('Paid') |
| Wait until gone | invisibilityOfElementLocated(by) |
EC.invisibility_of_element_located(loc) |
await expect(locator).toBeHidden() |
| Check the URL | urlContains("/orders") |
EC.url_contains("/orders") |
await expect(page).toHaveURL(/\/orders/) |
| Fixed sleep | Thread.sleep(2000) |
time.sleep(2) |
delete it; wait for a state, or page.waitForResponse() |
| iframe | driver.switchTo().frame("payment") |
driver.switch_to.frame("payment") |
page.frameLocator('#payment'), no switching back |
| New window | driver.switchTo().window(handle) |
driver.switch_to.window(handle) |
const popupPromise = page.waitForEvent('popup') before the click, then const popup = await popupPromise |
| Alert | driver.switchTo().alert().accept() |
driver.switch_to.alert.accept() |
page.once('dialog', d => d.accept()) before the click |
| Run JavaScript | ((JavascriptExecutor) driver).executeScript(js) |
driver.execute_script(js) |
page.evaluate(fn) |
| Reuse a login | driver.manage().addCookie(cookie) |
driver.add_cookie({...}) |
storageState in the config |
| Page Factory | @FindBy + PageFactory.initElements(driver, this) |
none (locator tuples) | Locator fields set in the constructor |
| Parallel runs | RemoteWebDriver + Grid |
webdriver.Remote(...) + Grid |
workers and --shard |
Four differences break a straight port:
find_elementreturns the first match; a Playwright locator is strict. In the demo,page.get_by_role("button", name="Mark as shipped").click()failed withError: strict mode violation: get_by_role("button", name="Mark as shipped") resolved to 3 elementsand listed a more specific locator for each match. Scope the locator to its row, as the tests below do, rather than adding.first.send_keysappends;fillreplaces. A test that relied on a pre-filled value now types the whole value.- Dialogs are dismissed for you unless you register a handler first (dialogs). A test that accepts a confirm box needs
page.once('dialog', ...)before the click. - Selenium 4 relative locators (
locate_with(By.TAG_NAME, "input").below(label)in Python) have no good match. Playwright's layout selectors are deprecated (other locators). Use the field's label orfilter({ has }). Playwright locators ranks the options.
WebDriverWait vs expect: the same test in both
The demo app has a sign-in page and an orders list that loads after 600 ms. Search re-renders the whole list 300 ms after the last key press. "Mark as shipped" takes 700 ms, then shows a status message. A typical Selenium test, with a pytest driver fixture:
# tests/selenium/conftest.py
import pytest
from selenium import webdriver


@pytest.fixture
def driver():
    options = webdriver.ChromeOptions()
    options.add_argument("--headless=new")
    driver = webdriver.Chrome(options=options)  # Selenium Manager finds a matching chromedriver
    yield driver
    driver.quit()
# tests/selenium/test_orders.py
import os
from selenium.webdriver.common.by import By
from selenium.webdriver.support import expected_conditions as EC
from selenium.webdriver.support.ui import WebDriverWait
PASSWORD = os.environ.get("E2E_PASSWORD", "demo-password")
def test_mark_order_shipped(driver, base_url):
wait = WebDriverWait(driver, 10)
driver.get(f"{base_url}/login/")
driver.find_element(By.ID, "email").send_keys("ada@example.test")
driver.find_element(By.ID, "password").send_keys(PASSWORD)
driver.find_element(By.CSS_SELECTOR, "button[type='submit']").click()
wait.until(EC.text_to_be_present_in_element((By.TAG_NAME, "h1"), "Orders"))
driver.find_element(By.ID, "search").send_keys("Chen")
wait.until(lambda d: len(d.find_elements(By.CSS_SELECTOR, "#orders li")) == 1)
driver.find_element(
By.XPATH, "//li[contains(., 'ORD-1002')]//button[text()='Mark as shipped']"
).click()
toast = wait.until(EC.visibility_of_element_located((By.CSS_SELECTOR, "[role='status']")))
assert toast.text == "ORD-1002 marked as shipped"
wait.until(EC.text_to_be_present_in_element((By.CSS_SELECTOR, "#orders li .status"), "Shipped"))Every wait.until is there because something on the page is slow. Selenium's implicit wait defaults to 0, and the Selenium docs warn against mixing implicit and explicit waits because the timeouts can add up (waits). In Selenium's Python source, WebDriverWait ignores only NoSuchElementException by default, so a stale element inside your condition still escapes.
The same flow in Playwright for Python uses pytest-playwright's page fixture. If both suites live in one pytest project during the migration, three settings make that work:
# pyproject.toml
[tool.pytest.ini_options]
base_url = "http://localhost:4173"
pythonpath = ["."]
addopts = "--import-mode=importlib"
importlib mode lets both folders keep the same file names, such as test_orders.py. Without it, pytest stops with import file mismatch. pythonpath makes from pages.orders import ... work. The base_url fixture the Selenium test uses comes from pytest-playwright, or from pytest-base-url if you have it installed.
# tests/playwright/test_orders.py
import os

from playwright.sync_api import Page, expect

PASSWORD = os.environ.get("E2E_PASSWORD", "demo-password")


def test_mark_order_shipped(page: Page):
    page.goto("/login/")
    page.get_by_label("Email").fill("ada@example.test")
    page.get_by_label("Password").fill(PASSWORD)
    page.get_by_role("button", name="Sign in").click()
    expect(page.get_by_role("heading", name="Orders")).to_be_visible()

    page.get_by_label("Search orders").fill("Chen")
    orders = page.get_by_role("list", name="Orders").get_by_role("listitem")
    expect(orders).to_have_count(1)
    orders.filter(has_text="ORD-1002").get_by_role("button", name="Mark as shipped").click()

    expect(page.get_by_role("status")).to_have_text("ORD-1002 marked as shipped")
    expect(orders.filter(has_text="ORD-1002")).to_contain_text("Shipped")
The waits are gone. Each expect retries until it passes or its timeout runs out (5 seconds by default, per test timeouts). The click waits for the button to be actionable. The locators say what a user sees, a label, a role, a row's text, so they survive markup changes. When you still need an explicit wait, see Playwright auto-waiting.
If your new suite is TypeScript, the same test in Playwright Test:
// tests/orders.spec.ts
import { test, expect } from '@playwright/test';

const PASSWORD = process.env.E2E_PASSWORD ?? 'demo-password';

test('mark an order as shipped', async ({ page }) => {
  await page.goto('/login/');
  await page.getByLabel('Email').fill('ada@example.test');
  await page.getByLabel('Password').fill(PASSWORD);
  await page.getByRole('button', { name: 'Sign in' }).click();
  await expect(page.getByRole('heading', { name: 'Orders' })).toBeVisible();

  await page.getByLabel('Search orders').fill('Chen');
  const orders = page.getByRole('list', { name: 'Orders' }).getByRole('listitem');
  await expect(orders).toHaveCount(1);
  await orders.filter({ hasText: 'ORD-1002' }).getByRole('button', { name: 'Mark as shipped' }).click();

  await expect(page.getByRole('status')).toHaveText('ORD-1002 marked as shipped');
  await expect(orders.filter({ hasText: 'ORD-1002' })).toContainText('Shipped');
});
Stale elements, and why they mostly go away
A WebElement points to one DOM node, and dies when the app replaces it. In the demo, keeping the button, then searching (which re-renders the list), then clicking gave:
selenium.common.exceptions.StaleElementReferenceException: Message: stale element reference: stale element not found in the current frameA Playwright locator stores how to find the element, and Playwright runs that lookup again for each action (locators). This test passes even though the list is rebuilt between creating the locator and clicking:
# tests/playwright/test_orders.py (continued)
def test_locator_survives_rerender(page: Page):
    page.goto("/login/")
    page.get_by_label("Email").fill("ada@example.test")
    page.get_by_label("Password").fill(PASSWORD)
    page.get_by_role("button", name="Sign in").click()

    orders = page.get_by_role("list", name="Orders").get_by_role("listitem")
    ship = orders.filter(has_text="ORD-1002").get_by_role("button", name="Mark as shipped")
    expect(ship).to_be_visible()

    page.get_by_label("Search orders").fill("Chen")
    expect(orders).to_have_count(1)

    # A locator is a query, not an element: it finds the new button after the re-render.
    ship.click()
    expect(page.get_by_role("status")).to_have_text("ORD-1002 marked as shipped")
"Mostly" because Playwright still has ElementHandle, which points to one node like a WebElement, and its docs discourage it in favour of locators (ElementHandle). Don't translate find_element into query_selector. And the Selenium test that proved this exception tests Selenium, not your app. In the inventory, it's a drop.
Port one critical flow first
Pick the flow whose failure would hurt most: sign-in, checkout, or whatever pays the bills. Include one hard step, such as a frame, a new tab or a file upload: it teaches you more than ten easy tests.
- Write down what the flow proves before you open the old code. If you can't state the expected result, the old test probably doesn't check it. How to write test cases has a format for this.
- Write the Playwright test from that description. Use the old test only to check you didn't miss a step.
- Log in once and reuse it. If your Selenium tests sign in through the form every time, stop there. Playwright saves cookies and storage to a file and starts each test from it. See Playwright authentication.
- Prove it's stable. Run it many times in parallel:
# TypeScript: 20 runs across 4 workers
npx playwright test --repeat-each=20 --workers=4

# Python: 20 runs in a row, stopping at the first failure
for i in $(seq 20); do pytest tests/playwright -q -k mark_order_shipped || break; done- Break the app on purpose. Change the expected text or remove the button in a local build. The test should fail with a message that says why.
Common snags in the first port:
- A base class still sets an implicit wait. Delete it. Playwright has nothing to turn off.
- Hidden sleeps in helpers. Replace each with the state you were waiting for: an element, a URL, or a response with
page.waitForResponse(). - Retries hiding problems. Playwright Test reports a test that passed on retry as flaky. Treat flaky as a failure while you port. See how to fix flaky Playwright tests.
Page objects: rewrite, don't port
Selenium page objects grow waits, string-built XPath and getters that return text. Here is a typical one, written for the same app:
# legacy_pages/orders.py
from selenium.webdriver.common.by import By
from selenium.webdriver.support import expected_conditions as EC
from selenium.webdriver.support.ui import WebDriverWait


class LoginPage:
    EMAIL = (By.ID, "email")
    PASSWORD = (By.ID, "password")
    SUBMIT = (By.CSS_SELECTOR, "button[type='submit']")

    def __init__(self, driver, base_url):
        self.driver = driver
        self.base_url = base_url
        self.wait = WebDriverWait(driver, 10)

    def open(self):
        self.driver.get(f"{self.base_url}/login/")
        return self

    def sign_in(self, email, password):
        self.driver.find_element(*self.EMAIL).send_keys(email)
        self.driver.find_element(*self.PASSWORD).send_keys(password)
        self.driver.find_element(*self.SUBMIT).click()
        self.wait.until(EC.text_to_be_present_in_element((By.TAG_NAME, "h1"), "Orders"))
        return OrdersPage(self.driver)


class OrdersPage:
    SEARCH = (By.ID, "search")
    ROWS = (By.CSS_SELECTOR, "#orders li")
    TOAST = (By.CSS_SELECTOR, "[role='status']")

    def __init__(self, driver):
        self.driver = driver
        self.wait = WebDriverWait(driver, 10)

    def search(self, text, expected_rows):
        self.driver.find_element(*self.SEARCH).send_keys(text)
        self.wait.until(lambda d: len(d.find_elements(*self.ROWS)) == expected_rows)

    def ship(self, order_id):
        self.driver.find_element(By.XPATH, f"//li[contains(., '{order_id}')]//button").click()

    def toast_text(self):
        return self.wait.until(EC.visibility_of_element_located(self.TOAST)).text

    def status_of(self, order_id):
        return self.driver.find_element(
            By.XPATH, f"//li[contains(., '{order_id}')]/span[@class='status']"
        ).text
Three things shouldn't carry over. search() needs the expected row count, so test knowledge leaks into the page. toast_text() returns a string, so an assertion on it can't retry. And every lookup is an id, a class or an XPath. The rewritten page objects hold locators as attributes and user actions as methods. They return locators, so tests assert with expect:
# pages/orders.py
from playwright.sync_api import Locator, Page


class LoginPage:
    def __init__(self, page: Page):
        self.page = page
        self.email = page.get_by_label("Email")
        self.password = page.get_by_label("Password")
        self.sign_in_button = page.get_by_role("button", name="Sign in")

    def open(self) -> "LoginPage":
        self.page.goto("/login/")
        return self

    def sign_in(self, email: str, password: str) -> "OrdersPage":
        self.email.fill(email)
        self.password.fill(password)
        self.sign_in_button.click()
        return OrdersPage(self.page)


class OrdersPage:
    def __init__(self, page: Page):
        self.page = page
        self.heading = page.get_by_role("heading", name="Orders")
        self.search_box = page.get_by_label("Search orders")
        self.orders = page.get_by_role("list", name="Orders").get_by_role("listitem")
        self.toast = page.get_by_role("status")

    def order(self, order_id: str) -> Locator:
        return self.orders.filter(has_text=order_id)

    def search(self, text: str) -> None:
        self.search_box.fill(text)

    def ship(self, order_id: str) -> None:
        self.order(order_id).get_by_role("button", name="Mark as shipped").click()
A pytest fixture signs in, and the test keeps every assertion:
# tests/playwright/conftest.py
import os

import pytest
from playwright.sync_api import Page, expect

from pages.orders import LoginPage, OrdersPage

PASSWORD = os.environ.get("E2E_PASSWORD", "demo-password")


@pytest.fixture
def orders_page(page: Page) -> OrdersPage:
    orders = LoginPage(page).open().sign_in("ada@example.test", PASSWORD)
    expect(orders.heading).to_be_visible()
    return orders
# tests/playwright/test_orders_po.py
from playwright.sync_api import expect
from pages.orders import OrdersPage
def test_ship_with_page_objects(orders_page: OrdersPage):
orders_page.search("Chen")
expect(orders_page.orders).to_have_count(1)
orders_page.ship("ORD-1002")
expect(orders_page.toast).to_have_text("ORD-1002 marked as shipped")
expect(orders_page.order("ORD-1002")).to_contain_text("Shipped")The Selenium suite has a test with the same name, which the next step relies on. For the TypeScript version with test.extend, read Playwright page object model. For Python in depth, read Page objects in Playwright Python.
Run both suites in CI
While you port, both suites run on every pull request. Selenium stays the required check, since it's the suite you trust today. A third job compares outcomes by test name:
# .github/workflows/e2e.yml
name: e2e

on:
  push:
    branches: [main]
  pull_request:

jobs:
  selenium:
    runs-on: ubuntu-latest
    timeout-minutes: 20
    steps:
      - uses: actions/checkout@v6
      - uses: actions/setup-python@v6
        with:
          python-version: '3.12'
          cache: pip
      - run: pip install -r requirements.txt
      # GitHub's Ubuntu runners include Google Chrome; Selenium Manager fetches a matching driver.
      # Start your app here first (or pass --base-url to a preview deploy). The demo's root conftest.py serves it.
      - run: pytest tests/selenium --junitxml=results/selenium.xml
      - uses: actions/upload-artifact@v4
        if: ${{ !cancelled() }}
        with:
          name: selenium-results
          path: results/

  playwright:
    runs-on: ubuntu-latest
    timeout-minutes: 20
    steps:
      - uses: actions/checkout@v6
      - uses: actions/setup-python@v6
        with:
          python-version: '3.12'
          cache: pip
      - run: pip install -r requirements.txt
      - run: python -m playwright install --with-deps chromium
      # Start your app here first (or pass --base-url to a preview deploy). The demo's root conftest.py serves it.
      - run: pytest tests/playwright --junitxml=results/playwright.xml --tracing=retain-on-failure
      - uses: actions/upload-artifact@v4
        if: ${{ !cancelled() }}
        with:
          name: playwright-results
          path: results/
      - uses: actions/upload-artifact@v4
        if: ${{ failure() }}
        with:
          name: playwright-traces
          path: test-results/

  parity:
    needs: [selenium, playwright]
    if: ${{ !cancelled() }}
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v6
      # download-artifact@v4 already supports pattern and merge-multiple; a newer major is optional.
      - uses: actions/download-artifact@v4
        with:
          pattern: '*-results'
          merge-multiple: true
          path: downloaded/
      # Each artifact holds one file at its root (upload-artifact drops the shared results/ folder).
      - run: python3 tools/compare_junit.py downloaded/selenium.xml downloaded/playwright.xml
Selenium Manager, part of Selenium since 4.6, downloads the right driver (Selenium Manager), so the Selenium job needs no driver setup. The parity script reads both JUnit files:
# tools/compare_junit.py
"""Compare a Selenium and a Playwright JUnit XML report by test name.

Usage: python tools/compare_junit.py results/selenium.xml results/playwright.xml
Exit code 1 when a flow that exists in both suites has a different outcome.
"""
import sys
import xml.etree.ElementTree as ET


def outcomes(path: str) -> dict[str, str]:
    result = {}
    for case in ET.parse(path).getroot().iter("testcase"):
        name = case.get("name", "").split("[")[0]  # drop pytest parameters such as [chromium]
        if case.find("failure") is not None or case.find("error") is not None:
            result[name] = "failed"
        elif case.find("skipped") is not None:
            result[name] = "skipped"
        else:
            result[name] = "passed"
    return result


def main(selenium_xml: str, playwright_xml: str) -> int:
    old, new = outcomes(selenium_xml), outcomes(playwright_xml)
    differ = 0
    for name in sorted(old.keys() | new.keys()):
        if name not in new:
            state = "not ported yet"
        elif name not in old:
            state = "Playwright only"
        elif old[name] == new[name]:
            state = "same"
        else:
            state = "DIFFERENT"
            differ += 1
        print(f"{name:36} selenium={old.get(name, '-'):8} playwright={new.get(name, '-'):8} {state}")
    print(f"\n{len(old.keys() & new.keys())} flows in both suites, {differ} with different outcomes")
    return 1 if differ else 0


if __name__ == "__main__":
    sys.exit(main(sys.argv[1], sys.argv[2]))
On the demo repo, it printed:
test_locator_survives_rerender       selenium=-        playwright=passed   Playwright only
test_mark_order_shipped              selenium=passed   playwright=passed   same
test_ship_with_page_objects          selenium=passed   playwright=passed   same
test_stale_reference_after_rerender  selenium=passed   playwright=-        not ported yet

2 flows in both suites, 0 with different outcomes
The stale-reference test shows as "not ported yet" because the script can't know a test was dropped: delete it from the Selenium suite when you mark it drop. When we broke the Playwright side on purpose, it printed DIFFERENT for both shared flows and exited with 1. A difference means one suite is wrong. Find out which before you trust either.
Three team rules keep this phase short:
- Freeze the old suite. After an agreed date, new tests are Playwright only.
- Keep test names equal for ported flows, so the parity report can pair them.
- Delete a Selenium test only when its twin has a clean record, for example two weeks of main-branch runs. Switch the required check flow by flow.
If the Playwright suite outgrows one machine, split it with Playwright sharding. On GitLab, see Playwright in GitLab CI.
Retire Selenium
You're done when every inventory row is ported, merged or dropped with a reason. Then:
- Make the Playwright job the required check. Remove the Selenium and parity jobs.
- Delete
tests/selenium/,legacy_pages/, the driver fixture andseleniuminrequirements.txt(or the Maven/Gradle dependency). - Shut down the Grid (workers and shards replace it) and any driver download steps in CI. Then find leftovers with
grep -rniE "selenium|webdriver" ., including README files and onboarding docs. - Run
tools/measure.pyone last time on the full suite, for speed numbers from your own CI.
Re-record instead of translate (Blendra)
If your Selenium suite is mostly UI flows, you can record each critical flow again and start from generated Playwright code instead of translated code.
Blendra records flows with its Chrome extension and exports a Playwright TypeScript project. It writes page objects under pages/, their selectors under locators/, every page object as a fixture in fixtures/base.ts, and a GitHub Actions workflow (generated project structure). Page objects hold actions only; the checks live in the specs (page objects). Values typed into fields it detects as sensitive, such as passwords and card numbers, aren't stored, and the exported test reads them from environment variables (sensitive values). On Pro+ and Team, a project can export Playwright Python instead (Beta).
Know the limits. Recording happens in Chrome, and the exported config runs Chromium only, so adding Firefox or WebKit is up to you. A recording captures navigation, clicks, typing, selects and checkboxes. It does not capture hover, key presses, drag-and-drop, file uploads, or the API calls and database seeding in your setup code, so port those by hand. And run the parity job either way: a re-recorded flow still has to prove what the old test proved.
FAQ
Can I convert Selenium code to Playwright automatically?
Converters and AI assistants can translate syntax, but the output keeps the old waits, XPath and page object shape: the parts you're migrating away from. Use one for a first draft at most, and review it against the mapping table.
Can Playwright run on our existing Selenium Grid?
Yes, with limits. Set SELENIUM_REMOTE_URL to your hub. The Playwright docs mark the feature as experimental, and it supports only Chrome and Edge (Selenium Grid). It can bridge the migration. For the long term, use workers and --shard.
We use Selenium with Python and pytest. Do we have to change test runners?
No. pytest-playwright is a pytest plugin. It adds the page fixture, base_url and browser options to the pytest you already run. Both suites can share one pytest project with the three pyproject.toml settings shown above. See Playwright with pytest.
How long does a Selenium to Playwright migration take?
It depends on suite size and how many tests use frames, windows, downloads or custom Grid capabilities. Time your first ported flow, multiply by the flows of similar difficulty, and add time for the hard ones in your inventory. That beats any general figure.
Should we move to Cypress instead?
If your team writes Java or Python, Cypress isn't an option: its tests are JavaScript or TypeScript only. For a dated, side-by-side look, read Cypress vs Playwright.