Playwright
Playwright Visual Testing with toHaveScreenshot: Stable Snapshots in CI
Visual comparisons that don't fail on every font change: baselines, masks, thresholds and the CI setup that keeps them stable.
Playwright visual testing needs no plugin. Playwright Test ships with toHaveScreenshot(), which captures the page, compares it with a saved baseline image and fails when too many pixels differ. A first comparison takes a few lines. The hard part is keeping it green when nothing has really changed: a clock ticks, a font renders a little differently on the CI machine, or a spinner is caught mid-turn. This guide covers how the comparison works, why baselines drift between machines, and how to fix each cause. It ends with a safe way to update snapshots.
Every example comes from one small project: a static billing page with a live clock, a random tip and a spinning loader. All of it was run with @playwright/test 1.64.1 in October 2026, on an Ubuntu 24.04 laptop and inside the official Playwright Docker image. One experiment, the Ubuntu 22.04 comparison, ran on 1.61.1, and it is labelled where it appears. Every error message below is real output from those runs.
Key takeaways
- Make the baselines and run the comparisons in the same environment. The simplest way is the official Playwright Docker image, pinned to the exact version in your
package.json. - Fix dynamic content at the source first (freeze the clock, mock the data). Mask what's left, and mask a box whose size never changes.
- Keep animations disabled (the default). A running animation gives you "Failed to take two consecutive stable screenshots."
- Be careful with page-wide tolerances. A 0.5% ratio let a price change from $79 to $89 pass. A 20-pixel limit on the plan card caught it.
- Update snapshots on purpose: scope the update, run it in the same image, and review the PNGs like code.
How Playwright visual testing works with toHaveScreenshot
toHaveScreenshot() is a web-first assertion, like the ones in the guide to Playwright assertions. You can call it on a page or on a locator:
// Fragment: page and element comparisons.
await expect(page).toHaveScreenshot('billing.png', { fullPage: true });
await expect(page.getByRole('region', { name: 'Plan summary' })).toHaveScreenshot('plan-card.png');
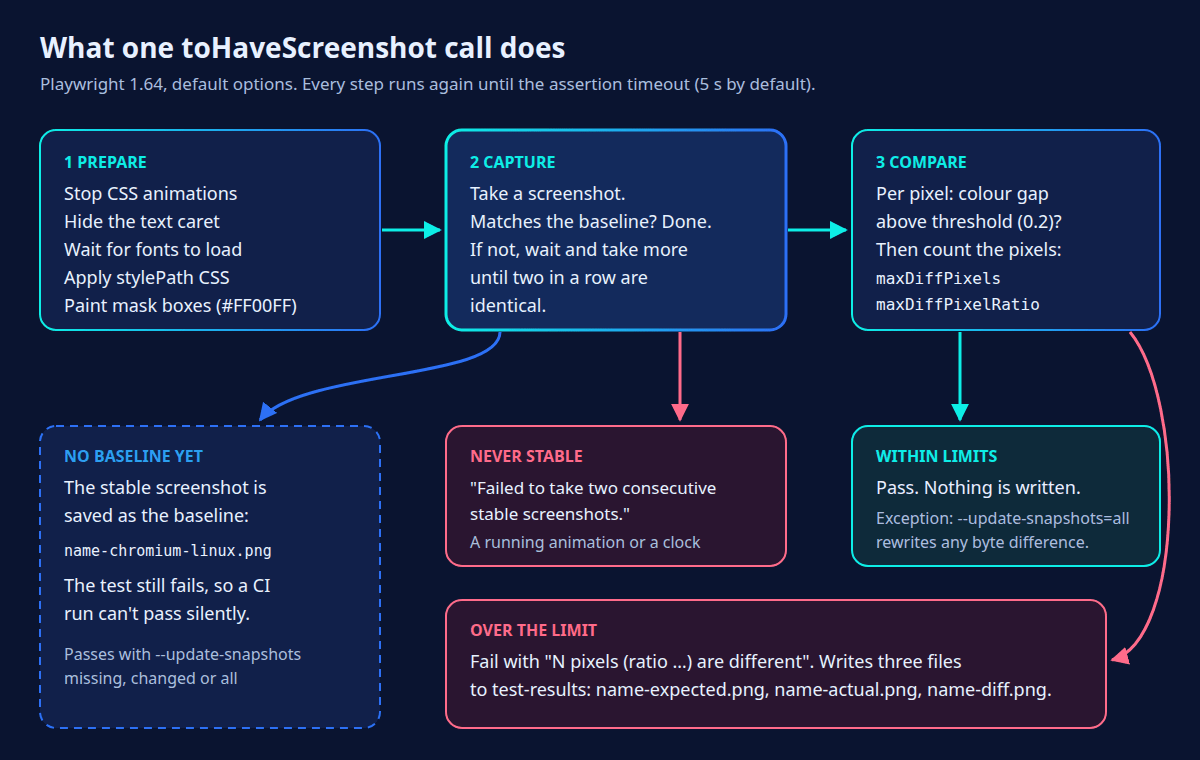
The first run has nothing to compare against, so Playwright saves what it saw as the baseline and fails the test anyway:
Error: A snapshot doesn't exist at …/tests/billing.visual.spec.ts-snapshots/plan-card-chromium-linux.png, writing actual.That failure is deliberate. The TestConfig docs say missing snapshots fail "so that the run does not silently pass in CI." Run the tests again and they compare against the new file.
Notice the file name. Playwright adds the project name and the platform to the name you gave: plan-card.png becomes plan-card-chromium-linux.png, in a folder named after the spec file. A baseline made on a Mac is saved as plan-card-chromium-darwin.png. Commit these folders. They are part of the test.
Each call then runs a small loop. The call log of a failing run shows the steps:
- Expect "toHaveScreenshot(billing.png)" with timeout 5000ms
  - verifying given screenshot expectation
- taking page screenshot
  - disabled all CSS animations
- waiting for fonts to load...
- fonts loaded
- 6282 pixels (ratio 0.01 of all image pixels) are different.
- waiting 100ms before taking screenshot
- taking page screenshot
  - disabled all CSS animations
- waiting for fonts to load...
- fonts loaded
- captured a stable screenshot
- 6282 pixels (ratio 0.01 of all image pixels) are different.
If the first screenshot already matches the baseline, the assertion passes at once. If not, Playwright keeps taking screenshots until two in a row are identical. Then it compares the last one with the baseline. A failure writes three files to test-results/: -expected.png, -actual.png and -diff.png.
Here is the full setup used in the rest of this post. The config sets shared defaults:
// playwright.config.ts
import { defineConfig, devices } from '@playwright/test';

export default defineConfig({
  testDir: './tests',
  reporter: [['list'], ['html', { open: 'never' }]],
  expect: {
    toHaveScreenshot: {
      // Allow up to 0.5% of the pixels to differ before a comparison fails.
      maxDiffPixelRatio: 0.005,
      // Applied while the screenshot is taken, never in normal runs.
      stylePath: './tests/screenshot.css',
    },
  },
  use: {
    baseURL: 'http://127.0.0.1:4327',
    // Same time zone and locale on every machine, so dates render the same.
    timezoneId: 'UTC',
    locale: 'en-GB',
  },
  projects: [{ name: 'chromium', use: { ...devices['Desktop Chrome'] } }],
  webServer: {
    command: 'node server.mjs',
    url: 'http://127.0.0.1:4327/billing',
    reuseExistingServer: !process.env.CI,
  },
});
And the spec:
// tests/billing.visual.spec.ts
import { test, expect } from '@playwright/test';

test.beforeEach(async ({ page }) => {
  // Freeze the clock before the page loads: "Last synced" and "Renews on" never change.
  await page.clock.setFixedTime(new Date('2026-10-01T09:30:00Z'));
  await page.goto('/billing');
  // Wait for the page to be ready, the same way a functional test would.
  await expect(page.getByRole('heading', { name: 'Pro plan' })).toBeVisible();
});

test('billing page looks right', async ({ page }) => {
  await expect(page).toHaveScreenshot('billing.png', {
    fullPage: true,
    // The tip is random on every load. Mask its fixed-size card, not the
    // paragraph: a longer tip wraps to two lines and changes the box height.
    mask: [page.getByRole('region', { name: 'Tip of the day' })],
  });
});

test('plan card looks right', async ({ page }) => {
  const planCard = page.getByRole('region', { name: 'Plan summary' });
  await expect(planCard).toHaveScreenshot('plan-card.png', {
    // A small card: allow a few pixels instead of a ratio.
    maxDiffPixels: 20,
  });
});
The tests/screenshot.css file holds one rule, .spinner { visibility: hidden; }. With baselines from the Docker image, this suite passed 20 out of 20 runs on the host (--repeat-each 10) and passed inside the image.
Why baselines differ between machines
The Playwright docs on visual comparisons warn that browser rendering "can vary based on the host OS, version, settings, hardware". In practice, three things bite.
The platform in the file name. A baseline made on macOS is …-chromium-darwin.png. A Linux CI runner looks for …-chromium-linux.png, finds nothing, writes it, and fails. Teams with Mac laptops and Linux CI usually meet this one first.
Fonts and rendering libraries. Even two Linux machines can disagree. To measure it, I made the baselines in the official v1.61.1-noble image (Ubuntu 24.04) and ran the same tests in the v1.61.1-jammy image (Ubuntu 22.04). This experiment used Playwright 1.61.1 in both images, so the Playwright version and the browser build were the same. The plan card still failed:
Error: expect(locator).toHaveScreenshot(expected) failed

Locator: getByRole('region', { name: 'Plan summary' })
  63 pixels (ratio 0.01 of all image pixels) are different.

  Snapshot: plan-card.png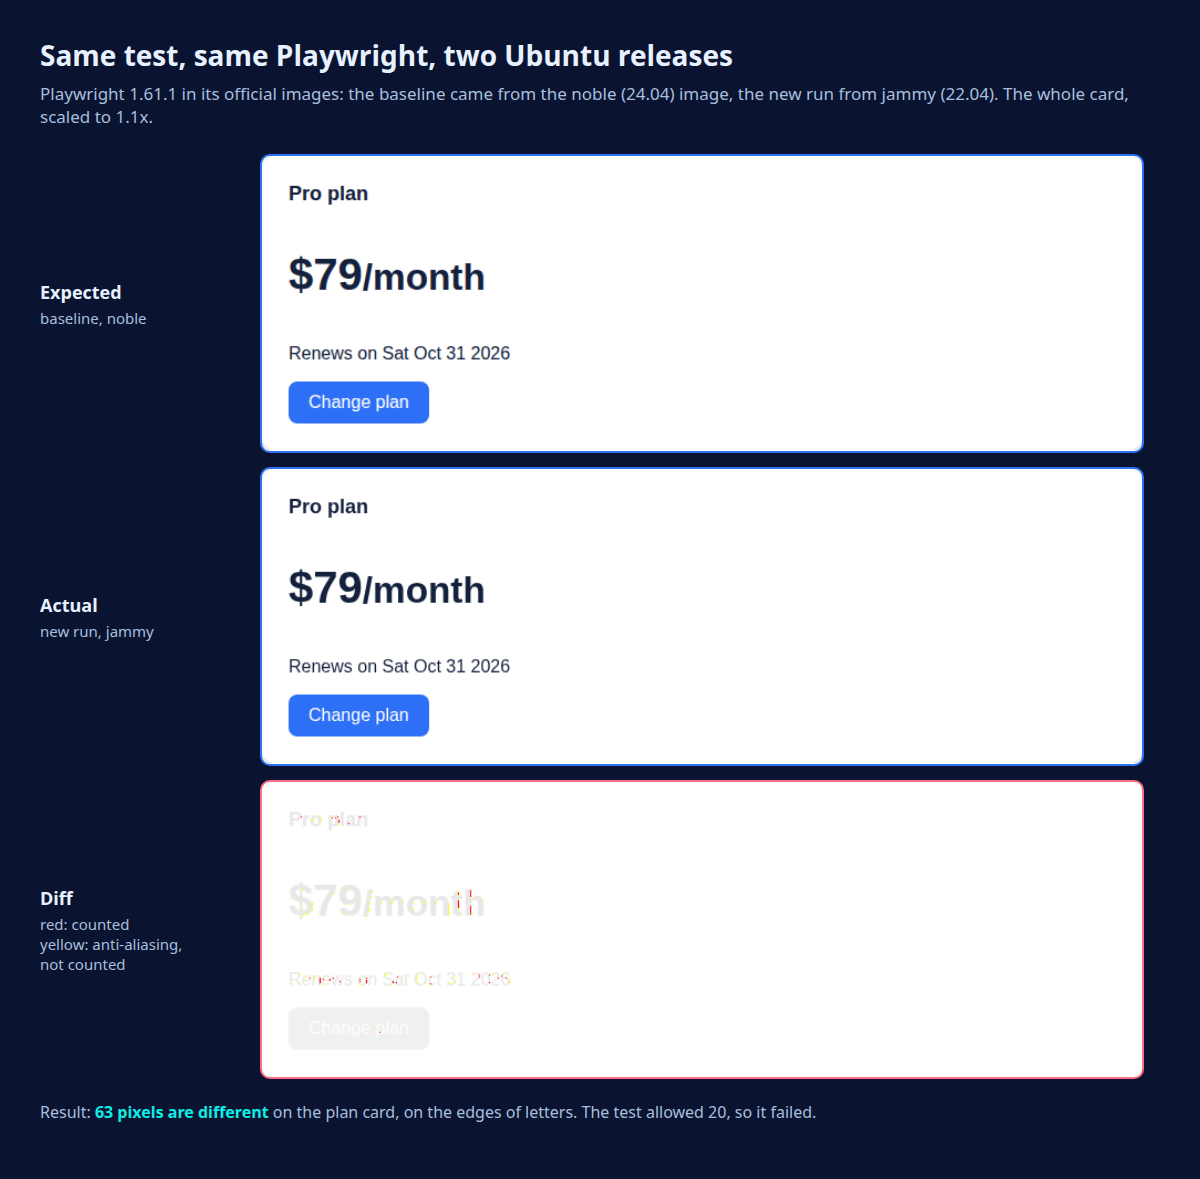
Nothing on the page changed. Glyph edges were drawn a little differently. The opposite results are worth knowing too. My Ubuntu 24.04 laptop matched the noble image, and the same baselines still passed after the upgrade to 1.64.1, both on the laptop and in the v1.64.1-noble image. Don't count on that luck. Make the environment the same on purpose.
Time zone and locale. The page formats its clock with toLocaleTimeString. With the clock frozen at 09:30 UTC, my laptop in Central Europe rendered 11:30:00. A runner in another zone renders another time. Setting timezoneId and locale in the config, as above, removes that difference.
Run Playwright visual tests in the Docker image
The fix is to make the baselines and run the comparisons in the same container. Pin the image tag to the exact @playwright/test version in your lock file. The Docker docs say a mismatch leaves Playwright unable to find its browser executables.
docker run --rm --ipc=host \
  -v "$PWD":/work -v /work/node_modules -w /work \
  mcr.microsoft.com/playwright:v1.64.1-noble \
  /bin/bash -c "npm ci && npx playwright test"
Each flag has a job:
--ipc=hostis recommended for Chromium, which can run out of memory without it.-v /work/node_modulesgives the container its own emptynode_modules. Without it,npm ciinside the container replaces thenode_moduleson your machine, which breaks native packages when your laptop isn't Linux.- The image already contains the browsers, so there is no
npx playwright installstep.
On a Linux host, everything the container writes belongs to root. That includes new baselines and test-results/. Hand them back to your user at the end of the same command:
docker run --rm --ipc=host \
  -v "$PWD":/work -v /work/node_modules -w /work \
  mcr.microsoft.com/playwright:v1.64.1-noble \
  /bin/bash -c "npm ci && npx playwright test; status=\$?; chown -R --reference=/work /work; exit \$status"
chown --reference=/work copies the owner of your project folder, so you don't need to know your user ID. The command saves the test's exit code in status and exits with it after the chown, so a failing visual test still fails the command. Without that, the exit code of chown (0) replaces the test's, and a script or CI job goes green even when screenshots fail. One more Linux detail: if the project had no node_modules folder yet, Docker creates an empty one owned by root as the mount point. Run npm ci on the host first, or delete that folder with sudo afterwards.
Mask dynamic content and stop animations
Anything that changes between runs breaks a screenshot. Deal with it in this order.
1. Fix the source
The best mask is the one you don't need. page.clock.setFixedTime() makes Date.now() and new Date() return a fixed value while timers keep running, as the clock docs explain. Call it before page.goto(). For data from an API, return a fixed response with page.route(). The guide to Playwright network mocking shows how.
Here is what the page looks like without any of this:
Error: expect(page).toHaveScreenshot(expected) failed

  1969 pixels (ratio 0.01 of all image pixels) are different.

  Snapshot: naive-billing.png
That run used the real clock and left the random tip unmasked, so the "Last synced" time had moved on since the baseline. The count changes from run to run (another run gave 1629), because the clock and the tip do.
2. Mask what you can't control
mask takes a list of locators. Playwright paints a solid box over each one (pink #FF00FF unless you set maskColor). The docs add a detail: the mask also covers invisible elements that match.
My first attempt masked the tip paragraph and still failed with 6,282 different pixels. The diff showed why. One tip fits on one line, another wraps to two, so the paragraph's box, and the mask with it, changed height. A mask hides content. It does not hide a change in layout. Mask a container whose size is fixed, like the whole "Tip of the day" card in the spec above.
The same rule applies to fullPage: true. If the page grows, the comparison fails whatever the tolerance says:
Error: expect(page).toHaveScreenshot(expected) failed

  Expected an image 1280px by 720px, received 1280px by 774px.
That came from adding five invoice rows. The message has no pixel count because the differing pixels stayed under the 0.5% limit. The size mismatch alone failed the test. For a list whose length varies, mock it or compare an element instead of the whole page.
3. Keep animations disabled
animations: 'disabled' is the default. Per the assertion docs, finite CSS animations and transitions jump to their end state, and infinite ones reset to their start. Turn it off and a spinner never holds still long enough:
Error: expect(locator).toHaveScreenshot(expected) failed

Locator: locator('header')
Timeout: 5000ms
  Failed to take two consecutive stable screenshots.
The setting covers CSS animations, transitions and the Web Animations API. It cannot stop a JavaScript timer that rewrites the DOM, such as a clock or a carousel driven by setInterval. Freeze those with page.clock, or hide them.
4. Hide the rest with stylePath
stylePath points to a CSS file that applies only while the screenshot is taken. It reaches into shadow DOM and iframes. Use it for things you never want in a baseline: loaders, cookie banners, chat widgets. Setting it under expect.toHaveScreenshot in the config applies it to every comparison. Two more defaults help you. The text caret is hidden (caret: 'hide'), and Playwright waits for fonts to load, as the call log above shows. Hover states are not reset, so move the mouse away first if a test hovered something.
Thresholds
Three options decide what counts as "different":
| Option | What it measures | Default |
|---|---|---|
threshold |
How far one pixel's colour may move (0 strict, 1 lax) before it counts | 0.2 |
maxDiffPixels |
How many pixels may differ | not set |
maxDiffPixelRatio |
Which share of all pixels may differ (0 to 1) | not set |
With neither limit set, a single differing pixel fails the test. In Playwright 1.64's comparator, setting both limits means the stricter one wins. The comparison uses the pixelmatch library, which also skips pixels it classifies as anti-aliasing (yellow in the diff image). So some rendering noise doesn't count, even at zero tolerance.
The trap is a ratio on a large image. On a 1280 × 720 page, 0.5% is 4,608 pixels. I changed the price on the billing page from $79 to $89 and ran both checks:
// Fragment from tests/tolerance.visual.spec.ts
test('whole page, 0.5% ratio', async ({ page }) => {
  await expect(page).toHaveScreenshot('tolerance-page.png', {
    fullPage: true,
    mask: [page.getByRole('region', { name: 'Tip of the day' })],
    maxDiffPixelRatio: 0.005,
  });
});

test('plan card, 20 pixels', async ({ page }) => {
  await expect(page.getByRole('region', { name: 'Plan summary' })).toHaveScreenshot('tolerance-card.png', {
    maxDiffPixels: 20,
  });
});
The whole-page check passed. The card check failed with "173 pixels (ratio 0.01 of all image pixels) are different". The wrong price was 173 pixels, well inside the page-wide allowance.
Two lessons follow. First, compare the components that matter as elements, with a small maxDiffPixels, and treat full-page shots as a smoke check for layout. Second, don't read the ratio in the error message as exact. Playwright rounds it up to two decimals, so 63 pixels on the plan card still prints as "ratio 0.01".
When fonts differ between machines, resist raising threshold until the test goes green. That hides real changes too. Fix the environment instead.
Update snapshots safely
When the UI changes on purpose, regenerate the baselines with --update-snapshots (or -u). The CLI docs list five modes. Here is what each one does in Playwright 1.64.1. I ran every mode against a missing, a failing and a passing baseline. The all row's last cell comes from reading the source, because my passing baseline matched byte for byte:
| Mode | Missing baseline | Comparison fails | Comparison passes |
|---|---|---|---|
none |
fails, writes nothing | fails | passes |
default (no flag) |
written, test fails | fails | passes |
missing |
written, test passes | fails | passes |
changed (flag with no value) |
written, test passes | rewritten, test passes | untouched |
all |
written, test passes | rewritten, test passes | rewritten if any byte differs |
changed is what you get from a bare --update-snapshots, and it's usually what you want. all also rewrites baselines that were within tolerance, which churns files for no visible reason. Older releases differ: Playwright 1.61, for example, accepts only all, changed, missing and none. Run npx playwright test --help to see the modes your version has.
A safe review flow looks like this:
- Read the failure first. In CI, upload
test-results/and the HTML report as artifacts. Locally, runnpx playwright show-report. A failed comparison has Diff, Actual, Expected, Side by side and Slider views. Decide whether the change is intended before you touch any baseline. - Update only what changed. Pass a file or a
--grepso a broken page elsewhere can't sneak into new baselines. - Update in the same image that CI uses:
docker run --rm --ipc=host \
  -v "$PWD":/work -v /work/node_modules -w /work \
  mcr.microsoft.com/playwright:v1.64.1-noble \
  /bin/bash -c "npm ci && npx playwright test tests/billing.visual.spec.ts --update-snapshots --grep 'plan card'; status=\$?; chown -R --reference=/work /work; exit \$status"
The same status and chown wrapper as before hands the new PNG and test-results/ back to your user on Linux.
- Commit the PNGs with the code change in the same pull request, so the reviewer sees the new baseline next to the change that caused it. Open the changed images and look at them. A baseline nobody looked at is a test nobody wrote.
Never run --update-snapshots automatically in CI on the main branch. It turns every visual regression into a new baseline.
The CI job uses the same image. This GitHub Actions workflow follows the container setup from the Playwright CI docs and keeps the diff images (I checked that the YAML parses; it was not run on GitHub):
# .github/workflows/visual.yml
name: Visual tests
on:
  pull_request:
  push:
    branches: [main]

jobs:
  visual:
    runs-on: ubuntu-latest
    # The same image, at the same version, that wrote the baselines.
    container:
      image: mcr.microsoft.com/playwright:v1.64.1-noble
      options: --user 1001
    steps:
      - uses: actions/checkout@v6
      - uses: actions/setup-node@v6
        with:
          node-version: lts/*
      - run: npm ci
      - run: npx playwright test
      # Expected, actual and diff images land in test-results/ when a comparison fails.
      - uses: actions/upload-artifact@v5
        if: ${{ !cancelled() }}
        with:
          name: visual-results
          path: |
            playwright-report/
            test-results/
          retention-days: 14
On GitLab the idea is the same: set the job's image: to the pinned Playwright image. The guide to Playwright in GitLab CI covers the rest of that pipeline. If a teammate can't run Docker, npx playwright test --ignore-snapshots still runs everything else in the suite while skipping the screenshot checks.
Where Blendra fits (it doesn't do visual checks)
Blendra doesn't do visual regression testing. It turns a flow you record in Chrome into a Playwright project with checks on what the page showed: the URL, the page title, whether an element or text is visible or hidden, an element's text, a field's value, whether a checkbox is checked or a control is enabled, and how many elements match. Those checks catch a checkout that stopped working. They won't catch a button that turned the wrong colour. That's the job of toHaveScreenshot.
The two sit together well. The exported TypeScript suite is an ordinary Playwright project in your repo, and its config runs every *.spec.ts under tests/. A file you add, such as tests/visual/billing.visual.spec.ts, runs with the rest. One thing to plan for: the exported GitHub workflow runs on ubuntu-latest and installs Chromium with npx playwright install --with-deps chromium. It doesn't use the Playwright container. Either make your baselines on that same runner, or run the visual specs in a separate job that uses the pinned image. Two settings in the exported config also matter. Its outputDir is reports/artifacts, so the expected, actual and diff PNGs land there instead of test-results/, and the exported workflow uploads them with the rest of reports/. And CI retries a failed test twice, so a visual failure runs three times before the job reports it. The docs on the generated project structure show every file in the export.
FAQ
Why does my visual test fail on the very first run?
Because no baseline exists yet. Playwright writes one and fails on purpose, so a CI run can't pass without a baseline. Run the tests again, or create baselines with --update-snapshots, and commit the new -snapshots folder.
Can Mac and Linux share the same baselines?
Not as they are. File names include the platform (darwin, linux), and the rendering differs anyway. Make one set of Linux baselines in the Docker image and run the comparisons there, locally and in CI.
What's the difference between toHaveScreenshot and toMatchSnapshot?
toHaveScreenshot takes the screenshot itself, waits for a stable image and applies the screenshot options covered here. toMatchSnapshot compares a value you pass in, such as text or a buffer, with a stored file.
Should I use maxDiffPixels or maxDiffPixelRatio?
Use maxDiffPixels for elements, because a fixed count stays meaningful whatever the element's size. Use a small maxDiffPixelRatio as a default in the config. Check what it adds up to on your largest screenshot, since 0.5% of a full page hid a price change in the test above.
Can I use toHaveScreenshot from Playwright for Python?
No. The locator assertion docs note that screenshot assertions only work with the Playwright Test runner, which is the Node.js one. In Playwright for Python 1.64, expect has ARIA snapshot matchers but no screenshot matcher. You can take screenshots with page.screenshot(), but you need another tool to compare them.