Locators and selectors
data-testid Best Practices: Naming, Ownership and Shipping to Production
Test ids make selectors boring in the best way. A naming scheme, an ownership rule and the production question, answered.
Most data-testid best practices are not about the attribute. They are about four team decisions: when an element earns a test id, what you call it, who may change it, and whether it ships to production. Get those right and test ids become the most boring part of your suite, which is exactly what you want from a selector. This guide gives you a policy you can copy, with lint rules that enforce it and working setups for Playwright and Cypress.
Every snippet ran against a small React checkout and a static legacy page: Playwright Test 1.61 (TypeScript), Cypress 16.2, and Playwright for Python 1.64 with pytest. The one exception is a Next.js setting, marked as a configuration fragment. Each block starts with its file name; download the examples to get the small app, the legacy page and the configs, so you can run every spec.
data-testid best practices, in short
- Role first, test id second. Use
getByRolewhen a control has an accessible name that stays the same in every run. Add a test id when it doesn't, or when the element isn't a control at all: a total, a row, a chart. - Name by purpose:
area-element-partin lowercase kebab-case, such ascheckout-place-order. Never display text, colour, position or a generated hash. - The component owns the id. Renaming or removing one is a breaking change and needs the tests updated in the same pull request.
- Keep them in production unless you have a measured reason not to. If you strip them, never run the test-id suite against the stripped build.
- One attribute per codebase. Tell your tool which one:
testIdAttributein Playwright, a custom command in Cypress.
When to add a test id, and when a role is enough
Playwright's own locators guide recommends role locators first and test ids when you "can't locate by role or text" (or have chosen the test-id approach). Testing Library ranks getByTestId last in its query priority, because users can't see or hear the attribute. Cypress goes the other way: its best practices page rates cy.get('[data-cy="submit"]') as "Always" and text matching as "Depends".
Both camps are right about different elements. A role locator such as getByRole('button', { name: 'Place order' }) finds the button and proves it has the right name. A test id finds the button whatever its label says, which is useful exactly when the label is not under your control. So the question to ask per element is short:
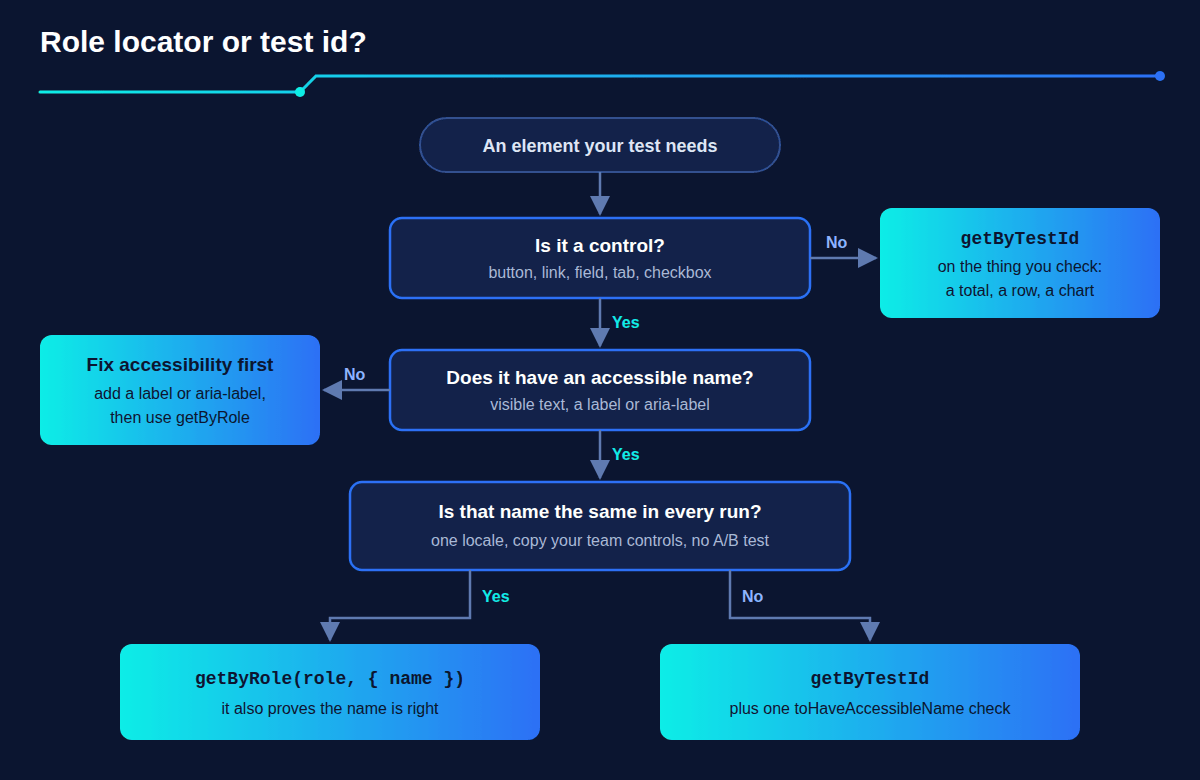
Add a test id when one of these is true:
- The copy changes between runs. You test several locales, marketing owns the button text in a CMS, or an A/B test swaps the label.
- The text is what you are checking. You can't find the order total by its text when the total is the thing under test. Find
checkout-total, then assert its text. - The element is not a control. Containers, summary panels, chart wrappers and list rows have no useful role and name.
- The same control repeats. Ten "Edit" buttons in ten rows. Put the id on the row, pick the row by its text, then find the button inside it.
Don't add a test id to work around a missing accessible name. An icon-only button with no aria-label is an accessibility bug. Fix the label, then use getByRole.
A naming scheme that scales
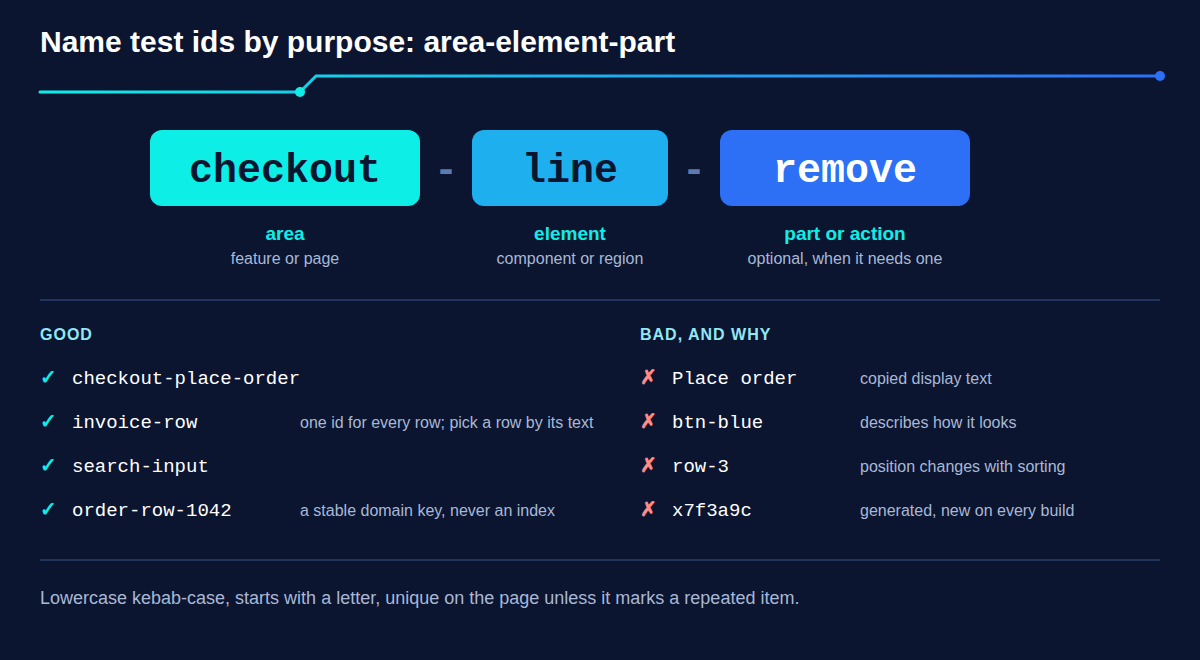
A test id is an interface between two codebases, so name it like one. The scheme that holds up best is area-element-part:
The rules behind it:
- Lowercase kebab-case, starting with a letter.
checkout-place-order, notCheckoutPlaceOrderorcheckout_place_order. Pick one style; mixing them is how duplicates happen. - Describe purpose, not appearance or text.
btn-bluebreaks with the next theme.Place orderbreaks with the next copy edit, and then the test id has no advantage over the text. - Never encode position.
row-3points at a different row as soon as someone sorts the table. - Repeated items share one id. Every row gets
checkout-line; the test filters by text. If you need a unique id per row, append a stable domain key (order-row-1042), never an array index. - Never generate ids at runtime from random values or timestamps. A test can't know them in advance.
Here is the scheme in a small React checkout. First the design-system button, because this is where test ids most often disappear:
// src/Button.tsx
import type { ButtonHTMLAttributes } from 'react';

type ButtonProps = ButtonHTMLAttributes<HTMLButtonElement> & {
  variant?: 'primary' | 'secondary';
  /** Forwarded to the real <button>, so tests can target it. */
  'data-testid'?: string;
};

export function Button({ variant = 'primary', type = 'button', ...rest }: ButtonProps) {
  // `...rest` carries data-testid, aria-label and onClick to the DOM element.
  // A design-system component that drops unknown props removes your test ids.
  return <button type={type} className={`btn btn-${variant}`} {...rest} />;
}
If your shared Button picks only known props and drops the rest, <Button data-testid="checkout-place-order"> renders a button with no test id, and the test fails with a timeout that looks like a missing element. Forward the rest props, and declare data-testid in the props type so the next developer knows it is supported.
The checkout component uses it with one id per role in the UI:
// src/CheckoutSummary.tsx
import { useState } from 'react';
import { Button } from './Button';

type Line = { sku: string; name: string; qty: number; priceCents: number };
type Locale = 'en' | 'de';

const copy = {
  en: { title: 'Your order', total: 'Total', placeOrder: 'Place order',
        remove: 'Remove', placed: 'Order placed' },
  de: { title: 'Deine Bestellung', total: 'Summe', placeOrder: 'Jetzt kaufen',
        remove: 'Entfernen', placed: 'Bestellung aufgegeben' },
};

type Props = { initialLines: Line[]; locale: Locale };

export function CheckoutSummary({ initialLines, locale }: Props) {
  const [lines, setLines] = useState(initialLines);
  const [placed, setPlaced] = useState(false);
  const t = copy[locale];
  const money = new Intl.NumberFormat(locale, { style: 'currency', currency: 'EUR' });
  const totalCents = lines.reduce((sum, l) => sum + l.qty * l.priceCents, 0);
  const remove = (sku: string) => setLines((all) => all.filter((l) => l.sku !== sku));

  return (
    <section aria-labelledby="summary-title" data-testid="checkout-summary">
      <h2 id="summary-title">{t.title}</h2>
      <ul>
        {lines.map((line) => (
          // One id for every row; tests pick a row by its text.
          <li key={line.sku} data-testid="checkout-line">
            <span>{line.name}</span> × {line.qty}
            <Button
              variant="secondary"
              aria-label={`${t.remove} ${line.name}`}
              data-testid="checkout-line-remove"
              onClick={() => remove(line.sku)}
            >
              ✕
            </Button>
          </li>
        ))}
      </ul>
      <p>
        {t.total}:{' '}
        <strong data-testid="checkout-total">{money.format(totalCents / 100)}</strong>
      </p>
      <Button data-testid="checkout-place-order" onClick={() => setPlaced(true)}>
        {t.placeOrder}
      </Button>
      {placed && <p role="status">{t.placed}</p>}
    </section>
  );
}
The page renders in English or German (?lang=de), so the same test can run in both languages without a lookup table of labels:
// tests/checkout.spec.ts
import { test, expect } from '@playwright/test';

const locales = [
  { lang: 'en', total: '€27.50', placed: 'Order placed' },
  { lang: 'de', total: '27,50 €', placed: 'Bestellung aufgegeben' },
];

for (const { lang, total, placed } of locales) {
  test(`places an order (${lang})`, async ({ page }) => {
    await page.goto(`/?lang=${lang}`);

    // The same test ids work in every language; only the expected copy changes.
    await expect(page.getByTestId('checkout-total')).toHaveText(total);
    await page.getByTestId('checkout-place-order').click();
    await expect(page.getByRole('status')).toHaveText(placed);
  });
}

test('removes one line and updates the total', async ({ page }) => {
  await page.goto('/');
  const lines = page.getByTestId('checkout-line');

  // Every row shares one test id. Pick the row by its text, then the button in it.
  await lines
    .filter({ hasText: 'Desk lamp' })
    .getByTestId('checkout-line-remove')
    .click();

  await expect(lines).toHaveCount(1);
  await expect(page.getByTestId('checkout-total')).toHaveText('€8.00');
});
getByTestId matches the whole attribute value, case-sensitively. getByTestId('checkout') does not find checkout-total. That strictness is a feature: a test id either matches or it doesn't. For more on filter() and chaining, see the Playwright locators guide.
Enforce the scheme with lint rules
A naming scheme that lives only in a wiki drifts within a month. You can enforce this one with ESLint's built-in no-restricted-syntax rule and the typescript-eslint parser, with no extra plugin:
// eslint.config.mjs
import tsParser from '@typescript-eslint/parser';

const KEBAB = '/^[a-z][a-z0-9]*(-[a-z0-9]+)+$/';

export default [
  {
    files: ['src/**/*.tsx', 'lint-demo/**/*.tsx'],
    languageOptions: {
      parser: tsParser,
      parserOptions: { ecmaFeatures: { jsx: true } },
    },
    rules: {
      'no-restricted-syntax': [
        'error',
        {
          selector: 'JSXAttribute[name.name=/^data-(test|test-id|cy|qa)$/]',
          message: 'Use data-testid: the one test id attribute in this codebase.',
        },
        {
          selector: `JSXAttribute[name.name='data-testid'] > Literal[value!=${KEBAB}]`,
          message: 'data-testid is kebab-case <area>-<element>, e.g. checkout-place-order.',
        },
      ],
    },
  },
  {
    files: ['tests/**/*.ts', 'lint-demo/**/*.ts'],
    languageOptions: { parser: tsParser },
    rules: {
      'no-restricted-syntax': [
        'error',
        {
          selector:
            "CallExpression[callee.property.name='locator'] > Literal[value=/data-testid/]",
          message: "Use page.getByTestId('…'), not a raw [data-testid] selector.",
        },
      ],
    },
  },
];
Run against a component that uses data-testid="Promo Banner", data-cy="promo-text" and data-testid="promoClose", plus a spec that calls page.locator('[data-testid="promo-close"]'), npx eslint lint-demo reports (paths shortened):
lint-demo/PromoBanner.tsx
  4:22  error  data-testid is kebab-case <area>-<element>, e.g. checkout-place-order  no-restricted-syntax
  5:10  error  Use data-testid: the one test id attribute in this codebase            no-restricted-syntax
  6:27  error  data-testid is kebab-case <area>-<element>, e.g. checkout-place-order  no-restricted-syntax

lint-demo/promo.spec.ts
  6:22  error  Use page.getByTestId('…'), not a raw [data-testid] selector  no-restricted-syntax

✖ 4 problems (4 errors, 0 warnings)
Two limits to know. The value check only sees plain string values. Both data-testid={`order-row-${id}`} and data-testid={'Bad Value'} pass unchecked, so review values inside braces by hand. And if you want ready-made rules, testing-library/consistent-data-testid in eslint-plugin-testing-library checks values against a pattern, playwright/prefer-native-locators in eslint-plugin-playwright rewrites raw test-id selectors to getByTestId, and Cypress points to the cypress/require-data-selectors rule.
Who owns test ids
Test ids fail in a quiet way. A developer renames checkout-submit to checkout-place-order during a refactor, the app still works, and the suite goes red a day later in someone else's pipeline. The fix is an ownership rule, written down:
- The component owns its test ids. Whoever writes the component adds them, in the same pull request as the component. QA can request one; they shouldn't have to add it in a separate change.
- A test id is public API. Renaming or removing one is a breaking change. The pull request that changes it updates the tests that use it. A repo-wide search for the id string is enough to find them, which is one more reason to ban generated ids.
- Code review checks them. Add a line to your pull request template: "New interactive elements have a role and name, or a test id that follows the scheme."
- Delete dead ids. When no test references an id any more, remove it. Unused ids invite people to build on them.
In a monorepo, a CODEOWNERS entry for the end-to-end test folder makes the dependency visible: changes to tests and to the components they target are reviewed by people who know both.
Keep or strip in production: the trade-off
This is the question teams argue about most. Testing Library's FAQ makes the case for keeping them: a few end-to-end tests against production benefit from the attributes. It also names babel-plugin-react-remove-properties for teams that would rather strip them.
| Keep test ids in production | Strip them at build time | |
|---|---|---|
| What you test | The exact artifact you ship | A different build from the one you ship |
| Smoke tests on production | Can use the same locators | Must use role and text locators only |
| Page weight | A few extra attributes per element | Slightly smaller HTML |
| DOM exposure | Anyone can read the ids | Ids not visible |
| Build setup | Nothing to configure | A compiler option or plugin, per framework |
The page-weight point is real but small, and it's yours to measure: compare your built HTML with and without ids before deciding. The exposure point matters only if an id leaks something. checkout-place-order tells a scraper nothing it couldn't learn from the button's text. An id like admin-delete-tenant or one that contains an email address is a naming problem, not a build problem: rename it.
If you do strip them, know what your tool removes. In Next.js, compiler.reactRemoveProperties: true removes JSX props matching ^data-test by default (Next.js compiler docs). That pattern covers data-testid, data-test and data-test-id, but not data-cy. This is a configuration fragment, shown as the Next.js docs show it; it isn't part of the demo project:
// next.config.js (configuration fragment)
module.exports = {
  compiler: {
    reactRemoveProperties: true, // removes JSX props matching ^data-test
  },
};
Then make sure the suite can never run against that build by accident. Without a guard, every test fails with a locator timeout, and someone loses an hour reading traces. One test turns that into a clear message:
// tests/build-guard.spec.ts
import { test, expect } from '@playwright/test';

test('the build under test still has test ids', async ({ page }) => {
  await page.goto('/');
  // Fails with a clear message when the suite runs against a stripped build.
  // eslint-disable-next-line no-restricted-syntax -- any test id, not one element
  const anyTestId = page.locator('[data-testid]').first();
  await expect(anyTestId, 'No data-testid in this build. Were test ids stripped?')
    .toBeAttached();
});
Pointed at a page with no test ids, it fails with Error: No data-testid in this build. Were test ids stripped? after the normal expect timeout. On its own it runs in parallel with the other specs, so they still fail with their own timeouts. To stop them, put the guard in a setup project and list that project in the other projects' dependencies: when the guard fails, the rest of the suite doesn't run. Our default: keep test ids, keep them meaningful, and spend the effort on naming instead of stripping.
Configure Playwright and Cypress
Playwright: testIdAttribute
getByTestId reads data-testid unless you say otherwise. Set the attribute once in the config; projects can override it:
// playwright.config.ts
import { defineConfig, devices } from '@playwright/test';

export default defineConfig({
  testDir: './tests',
  use: {
    baseURL: 'http://localhost:4317',
    // data-testid is already the default. Spelling it out tells the next reader
    // which attribute getByTestId() reads in this repo.
    testIdAttribute: 'data-testid',
  },
  projects: [
    { name: 'chromium', testIgnore: /legacy/, use: { ...devices['Desktop Chrome'] } },
    {
      // Pages that still carry data-cy from an older Cypress suite.
      name: 'legacy-pages',
      testMatch: /legacy/,
      use: { ...devices['Desktop Chrome'], testIdAttribute: 'data-testid,data-cy' },
    },
  ],
  webServer: {
    command: 'node build.mjs && node server.mjs',
    url: 'http://localhost:4317',
    reuseExistingServer: !process.env.CI,
  },
});
The legacy-pages project uses a newer option, added in Playwright 1.61: a comma-separated list makes one getByTestId read several attributes, which the API reference documents for setTestIdAttribute. Playwright Test 1.60 and older don't document the list, so on those versions upgrade first or keep a single attribute. The list helps during a migration, when old pages still carry data-cy:
// tests/legacy.spec.ts
import { test, expect } from '@playwright/test';

// Runs in the 'legacy-pages' project, where testIdAttribute is 'data-testid,data-cy'.
test('one getByTestId reads both attributes during a migration', async ({ page }) => {
  await page.goto('/legacy.html');

  await page.getByTestId('cookie-accept').click(); // data-testid
  await page.getByTestId('newsletter-email').fill('ana@example.com'); // data-cy
  await page.getByTestId('submit').click(); // data-cy

  await expect(page.getByTestId('newsletter-done')).toHaveText('Thanks for subscribing');
});
This passed on Playwright Test 1.61.1. Treat the list as a bridge, not a policy: the lint rule above still allows only data-testid in new code.
In Playwright for Python, call selectors.set_test_id_attribute once per session. With pytest-playwright, a session fixture in conftest.py does it:
# python/conftest.py
import pytest


@pytest.fixture(scope="session", autouse=True)
def configure_test_ids(playwright):
    # Same effect as testIdAttribute in playwright.config.ts: get_by_test_id reads data-cy.
    playwright.selectors.set_test_id_attribute("data-cy")
# python/test_legacy.py
from pathlib import Path
from playwright.sync_api import Page, expect
LEGACY_PAGE = (Path(__file__).parent.parent / "public" / "legacy.html").resolve().as_uri()
def test_subscribe_with_data_cy(page: Page):
page.goto(LEGACY_PAGE)
page.get_by_test_id("newsletter-email").fill("ana@example.com")
page.get_by_test_id("submit").click()
expect(page.get_by_test_id("newsletter-done")).to_have_text("Thanks for subscribing")One difference we hit: the Python docs describe the same comma-separated form, but on Playwright for Python 1.64, set_test_id_attribute("data-testid,data-cy") made the next locator fail with InvalidSelectorError: Error while parsing selector. Stick to one attribute in Python until a release fixes that, and check your own version before relying on it. For the rest of the pytest setup, see Playwright with pytest.
Cypress: data-cy, or one custom command
Cypress's docs use data-cy, and a plain attribute selector is all you need:
// cypress/e2e/legacy.cy.ts
describe('legacy newsletter page', () => {
  it('subscribes using the data-cy convention', () => {
    cy.visit('/legacy.html');

    cy.get('[data-cy=newsletter-email]').type('ana@example.com');
    cy.get('[data-cy=submit]').click();
    cy.get('[data-cy=newsletter-done]')
      .should('be.visible')
      .and('have.text', 'Thanks for subscribing');
  });
});
The attribute name itself doesn't matter. What matters is that it appears in one place. If your app already uses data-testid (because Playwright, Testing Library or your component library expects it), don't add data-cy next to it. Write one custom command instead:
// cypress/support/e2e.ts
// One place that knows which attribute holds test ids.
// Change TEST_ID_ATTRIBUTE here, not in every spec.
const TEST_ID_ATTRIBUTE = 'data-testid';

declare global {
  namespace Cypress {
    interface Chainable {
      getByTestId(id: string): Chainable<JQuery<HTMLElement>>;
    }
  }
}

Cypress.Commands.add('getByTestId', { prevSubject: 'optional' }, (subject, id) => {
  const selector = `[${TEST_ID_ATTRIBUTE}="${id}"]`;
  // Chained off an element: search inside it. Otherwise: search the page.
  return subject
    ? cy.wrap(subject as JQuery<HTMLElement>).find(selector)
    : cy.get(selector);
});

export {};
// cypress/e2e/checkout.cy.ts
describe('checkout', () => {
it('removes one line and places the order', () => {
cy.visit('/');
// cy.contains(selector, text) yields the row that holds the text, not the text node.
cy.contains('[data-testid="checkout-line"]', 'Desk lamp')
.getByTestId('checkout-line-remove')
.click();
cy.getByTestId('checkout-line').should('have.length', 1);
cy.getByTestId('checkout-total').should('have.text', '€8.00');
cy.getByTestId('checkout-place-order').click();
cy.contains('[role="status"]', 'Order placed');
});
});Since Cypress 16.2 there is also a built-in cy.getByRole(), so the "role first, test id second" rule works in Cypress without a plugin. More on structuring a Cypress suite in Cypress best practices, and on moving between the two tools in migrate from Cypress to Playwright.
Test ids and accessibility
Test ids are invisible to assistive technology. That cuts both ways. Adding data-testid never hurts a screen-reader user. But a test that finds everything by test id also never notices when a button loses its accessible name.
Two habits close that gap:
- Never use ARIA attributes as test hooks. Adding
aria-label="submit-btn"so a test can find a button changes what a screen reader announces. That's what the test id is for. - Pair a test-id locator with one accessibility assertion on the elements that matter:
// tests/a11y.spec.ts
import { test, expect } from '@playwright/test';

test('test-id targets are still accessible', async ({ page }) => {
  await page.goto('/');

  // The test id finds the element; these assertions check what a screen reader gets.
  const placeOrder = page.getByTestId('checkout-place-order');
  await expect(placeOrder).toHaveRole('button');
  await expect(placeOrder).toHaveAccessibleName('Place order');

  const removeLamp = page
    .getByTestId('checkout-line')
    .filter({ hasText: 'Desk lamp' })
    .getByTestId('checkout-line-remove');
  await expect(removeLamp).toHaveAccessibleName('Remove Desk lamp');
});
The icon-only remove button shows only "✕", but its accessible name is "Remove Desk lamp". If someone drops the aria-label, the name falls back to the button's text, and this test fails with Expected: "Remove Desk lamp" and Received: "✕". Every test that only clicks the button keeps passing. It isn't a full accessibility audit, and neither is any choice of selector, as the Cypress docs point out. It does stop the most common regression. For more on web-first checks like these, see Playwright assertions.
How Blendra uses test ids
If you record tests with Blendra, your test ids matter from the first click. When the element you click has a data-testid, data-test, data-cy or data-test-id, the recorder picks that test id first, ahead of role and name, label, placeholder, the name attribute, text and CSS (locator priority), as long as the id matches only that element on the page. It ranks test ids above roles because a recorder can't tell whether a label will change next sprint.
A shared id is different. checkout-line-remove matches the remove button in every row, so the recorder skips it and uses the next locator that is unique, usually role and name (Remove Desk lamp). That is one more reason to give controls in repeated rows an accessible name: it is what a recorder falls back to.
Not every value counts. A test id with spaces, one that ends in punctuation, or one that doesn't start with a letter looks like display text pasted into the attribute. Blendra treats it as weak and uses the next locator in the ranking instead, usually role and name (test ids). Every id that follows the scheme in this post passes that check. In the page library, a test id that doesn't look like display text is rated High strength (manage locators).
The exported Playwright code matches a recorded test id against all four attributes in one selector, so it works whichever attribute your team chose, with no testIdAttribute setting. The beta Playwright Python and Cypress exports match the same four.
FAQ
data-testid vs data-cy: which should I use?
Whichever your main tools read by default, used consistently. Playwright's getByTestId and Testing Library default to data-testid; Cypress's docs use data-cy. If you run both tools, or might switch, data-testid with a small Cypress command is the least friction. The real mistake is having both in the same codebase.
Should every element get a test id?
No. Interactive elements with a stable accessible name are better found by role, which also tests the name. Add test ids where the role or name is missing, changes between runs, or is the value you're checking. Blanket ids on every div add noise and make it harder to see which ones tests depend on.
Do test ids in production slow the page down or leak anything?
Each one adds a short attribute to the HTML and does nothing at runtime; measure your built HTML if weight matters. They reveal little beyond the visible UI, as long as you keep emails, customer names and internal codenames out of them.
Can I put the same test id on many elements?
Yes, for repeated items such as list rows or cards. Use getByTestId('checkout-line').filter({ hasText: '…' }) in Playwright, or cy.contains('[data-testid="checkout-line"]', '…') in Cypress, to pick one. For single controls, keep ids unique on the page. Playwright's strict mode will throw when an action's locator matches more than one element.